
In March this year, the model at the top of every leaderboard was GPT-5.4. By June, it was Claude Opus 4.8. As I write this in late October, the composite leader is Claude Opus 5.5, the human-preference leader is Gemini 4 Argon, and the video model that owned the spring (Sora 2) has been switched off entirely. Three different answers to “what is the most advanced AI in the world” in seven months, and none of them were wrong on the day they were given.
The AI market moves faster than any product roadmap we’ve ever seen. The tool that was setting the benchmarks in Q1 is already outpaced in Q3 and the sheer amount of noise makes it extremely difficult to work out what actually warrants your engineering effort. This isn’t another piece of content that is just a series of slick demos. We’ve actually gone through the most advanced AI systems in 2026 and assessed them on what they actually do under pressure: writing and reviewing production code, disassembling a 90-page contract, running a support workflow at 2am with no one looking. All the numbers are from October 2026 and are linked to their source. An undated AI ranking is just a historical record when Google finally indexes it.
Key Takeaways
- There’s no such thing as a single ‘best’ AI. There’s just the right AI for your particular use case.
- Agentic AI is the defining shift of 2026 and it’s a complete reworking of how teams are structured.
- Speed and cost are just as important as raw intelligence.
- Enterprise AI adoption is about governance not capability.
- The biggest competitive advantage is shipping workflows.
What Is the Most Advanced AI Right Now? Three Scoreboards, Three Different Winners
Short answer 25th October 2026: Claude Opus 5.5 is number one on the Artificial Analysis Intelligence Index (AAII). Gemini 4 Argon is number one on the LMArena text leaderboard (real people vote on blind pairs). GPT-6 Astra has the best vendor reported maths/reasoning scores. Pick your scoreboard and you pick your winner.
That’s not a dodge. It’s how the NBA works, too. The regular-season MVP, the Finals MVP, and the All-Star fan vote regularly go to three different players in the same year, and nobody thinks the league is broken. They measure different things.
The independent composite: Opus 5.5 at 58, then a crowded pack
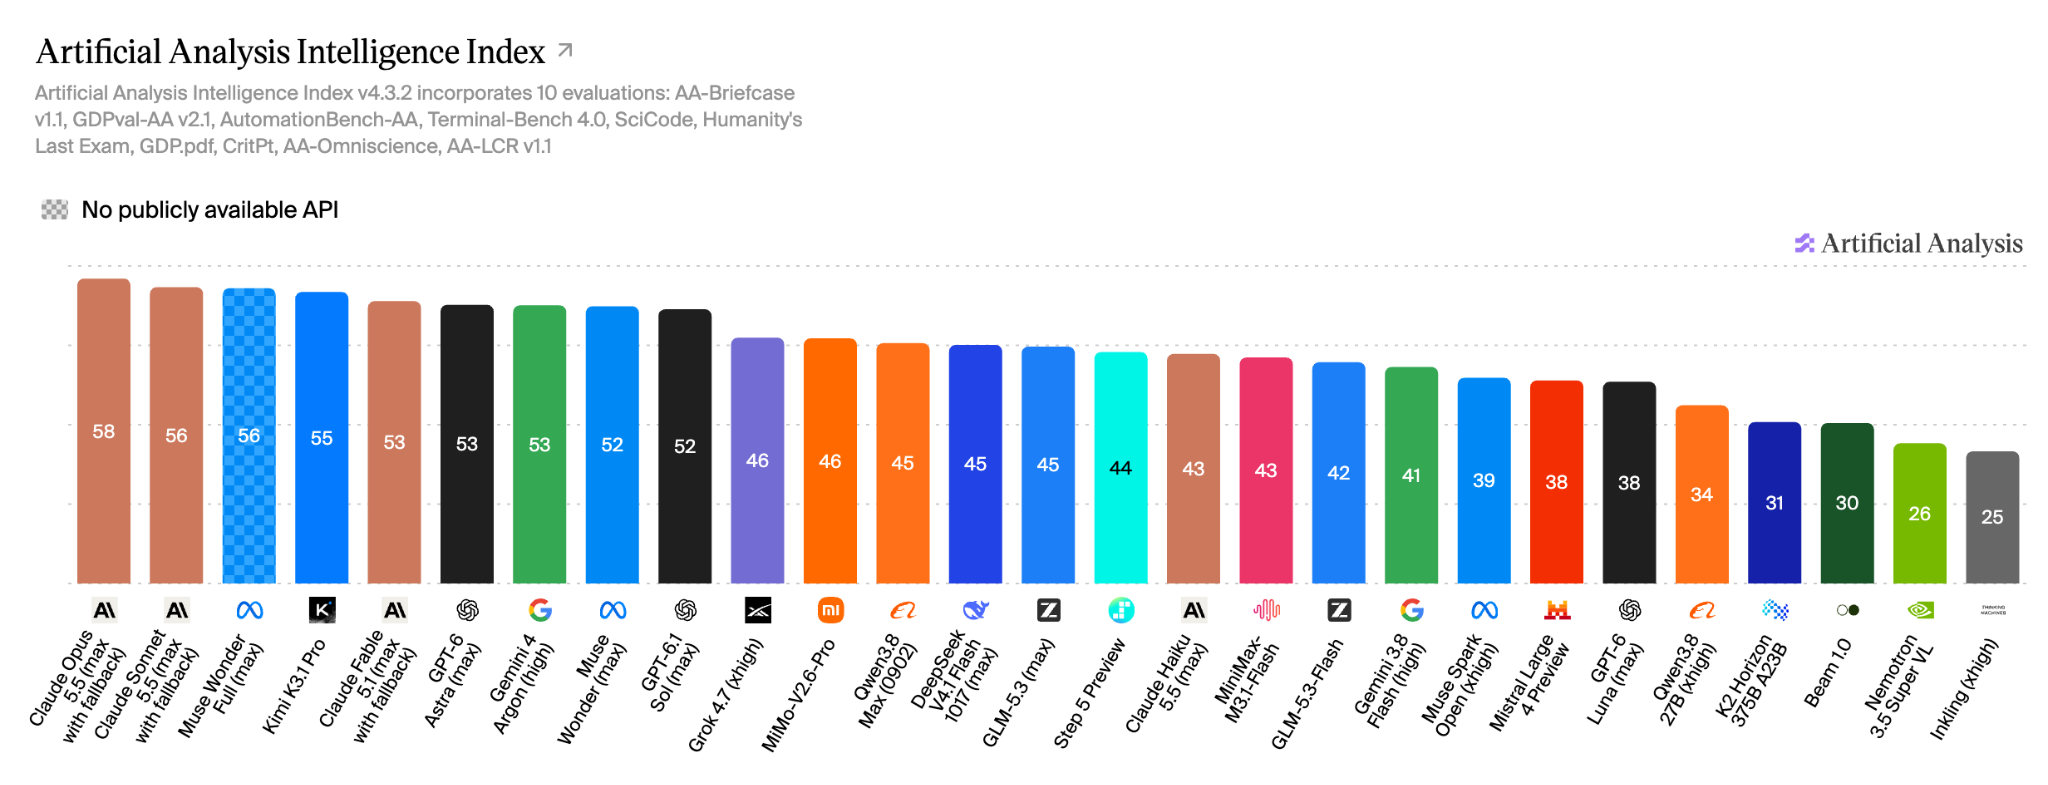
Artificial Analysis runs the same ten evaluations on every model and publishes one overall score. As of this writing the top of the LLM leaderboard looks like this:
| 1 | Claude Opus 5.5 (max effort) | Anthropic | 58 |
| 2 | Claude Sonnet 5.5 (max) | Anthropic | 56 |
| 2 | Muse Wonder Full (max) | Meta | 56 |
| 4 | Kimi K3.1 Pro | Moonshot AI | 55 |
| 5 | GPT-6 Astra (max) | OpenAI | 53 |
| 5 | Gemini 4 Argon (high) | 53 | |
| 5 | Claude Fable 5.1 (max) | Anthropic | 53 |
Source: Artificial Analysis LLM Leaderboard, October 2026. The index is re-based on a regular basis (now v4.3) so a score from August is not comparable to a score from October.
The gap between first and fifth is five points. In practice, that is the difference between a model that gets your test suite green on the first pass and one that needs a second prompt, which is real, but it’s not the difference between “the world’s most advanced AI” and an also-ran.
Human preference: Gemini 4 Argon, by a nose
On LMArena (where people go and compare two random answers, pick the better one) Gemini 4 Argon came in at the end of September and went on to take the top spot. The October snapshot has Argon at 1532, Claude Opus 5.5 at 1516, Claude Fable 5.1 at 1512 and Opus 5 at 1509. Argon’s lead is within its early confidence interval, so I’d still call that preliminary rather than definitive. The thing people like about Argon is the way it talks. That’s obviously very important for a chatbot and far less so for a batch pipeline.
Vendor-reported frontier results: GPT-6 Astra, with footnotes
OpenAI refers to GPT-6 Astra as “a new generation of intelligence” and reports 97.6% on FrontierMath Tier 4 and 96.0% on GPQA Diamond. ARC Prize (the independent body that runs the ARC-AGI tests) ran Astra themselves and published two figures: 62.7% on ARC-AGI-3 with the standard harness and 99.9% with OpenAI’s provider adapter. Same model, same test, a 37-point difference depending on the harness. ARC Prize was very clear to stress that this in no way constitutes proof of AGI. I’d be extremely cautious about accepting that as such.
Is ChatGPT the most advanced AI?
ChatGPT is a product. GPT-6 is the model family under it, and the two get conflated in almost every “which AI is the most advanced” thread on Reddit. By the independent composite, GPT-6 Astra ties for fifth at 53, behind Claude and Meta. By developer usage, the Stack Overflow 2026 survey puts Anthropic models at 75% and OpenAI’s at 74%, which is a statistical coin flip. Where ChatGPT still wins outright is reach: GPT-6 Luna is available to Free and Go users, and no other frontier lab gives away a 1M-token model at that tier.
So: the most advanced AI chatbot for most people is probably still the one they already have open. The most advanced AI model for your workload is a different question, and the rest of this guide is about answering it.
Most Advanced AI Systems Compared: 17 Frontier Models on One Table (October 2026)
Here are the top AI models side by side on the metrics that determine a production bill: intelligence, context, price and output speed. The scores and speeds are from Artificial Analysis; the prices are the vendors’ own listed rates (standard tier, uncached). All figures were checked on 25th October 2026.
| 1 | Claude Opus 5.5 | Anthropic | 58 | 1M | $4 / $20 | 96 | Claude apps, API, AWS, Google Cloud, Azure |
| 2 | Claude Sonnet 5.5 | Anthropic | 56 | 1M | $2 / $10 | 133 | Claude apps, API |
| 3 | Muse Wonder Full | Meta | 56 | 1M | Subscription only (Muse Code) | n/a | No API, no open weights |
| 4 | Kimi K3.1 Pro | Moonshot AI | 55 | 1M | $2 / $10 | 73 | API |
| 5 | GPT-6 Astra | OpenAI | 53 | 1.05M | $10 / $50 | 58 | ChatGPT paid plans, API, Azure, Bedrock |
| 6 | Gemini 4 Argon | 53 | 1.05M unified | $2 / $10 intro, $4 / $20 from Dec 1 | 79 | Gemini app (AI Pro / Ultra), AI Studio, API | |
| 7 | Claude Fable 5.1 | Anthropic | 53 | 1M | $10 / $50 | 68 | API, Claude apps |
| 8 | Muse Wonder | Meta | 52 | 1.05M | $4 / $20 | 145 | Meta Model API, Muse Code |
| 9 | GPT-6.1 Sol | OpenAI | 52 | 1.05M | $2 / $10 | 57 | ChatGPT paid plans, API |
| 10 | Grok 4.7 | SpaceXAI | 46 | 500K | $2 / $6 | 97 | Grok, Grok Build, API, Cursor |
| 11 | MiMo-V2.6-Pro | Xiaomi | 46 | 1M | Open weights | 55 | Self-host or API |
| 12 | DeepSeek V4.1 Flash | DeepSeek | 45 | 1M | $0.30 / $1.20 peak, half off-peak | 195 | Open weights (MIT), API |
| 13 | Qwen3.8 Max | Alibaba | 45 | 984K | Not listed | 42 | API |
| 14 | Claude Haiku 5.5 | Anthropic | 43 | 1M | $0.10 / $0.50 | 236 | Claude apps, API |
| 15 | Gemini 3.8 Flash | 41 | 1M | $0.75 / $3.75 | 141 | Gemini app, API | |
| 16 | GPT-6 Luna | OpenAI | 38 | 1.05M | $0.10 / $0.50 | 137 | ChatGPT Free and Go, API |
| 17 | Mistral Large 4 Preview | Mistral | 38 | 524K | Not listed | 95 | API |
Price footnotes that matter: GPT-6 Astra and Sol charge 2x input and 1.5x output on any prompt over 272K tokens. Grok 4.7 moves to a higher tier above 200K. Argon’s $2 / $10 rate ends November 30, 2026. DeepSeek bills by time of day. Haiku 5.5 is $0.10 / $0.50 only for prompts up to 100K tokens.
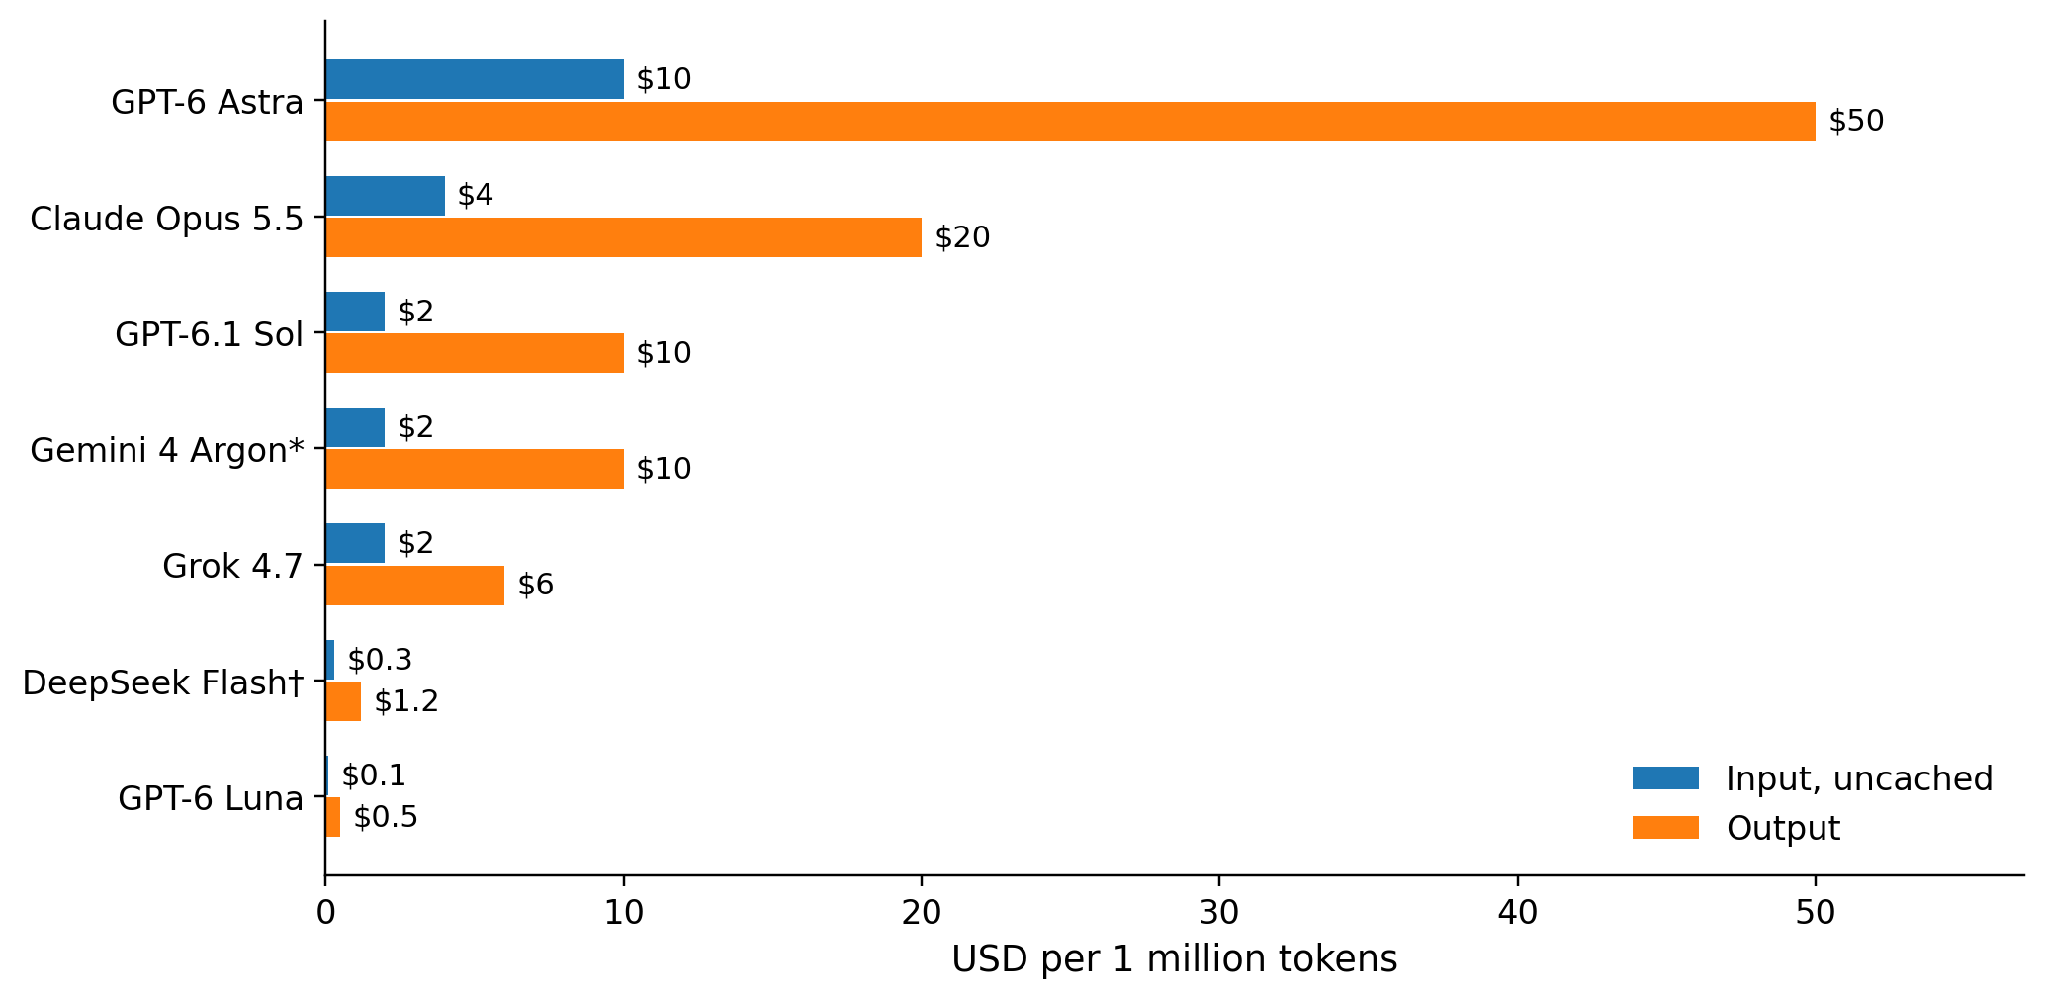
Figure 1. List prices for seven of the models above, USD per 1M tokens. Argon at introductory rate; DeepSeek at peak rate.
How to read the comparison table (and how not to)
The Intelligence Index is an overall score built from ten separate evaluations, not one test. That’s its strength and its catch. GPT-6.1 Sol and Muse Wonder both score 52, but Artificial Analysis puts Sol’s cost per index task at $0.72 and Claude Opus 5.5’s at $5.98. Which means a one-point lead on the composite can cost you eight times as much per answer. If your workload is 10,000 support tickets a day, the leaderboard winner is almost never the model you ship.
Output speed tells you how the model feels rather than how long you’re actually waiting. At maximum reasoning effort Opus 5.5 takes approximately 562 seconds to spit out its first visible chunk of answer. At medium effort it’s about 10 seconds. GPT-6 Astra shows the same profile: 247 seconds at max, 4 seconds at medium. All the frontier models now have an effort dial and that dial has an effect on the bill, the latency and the score all at the same time.
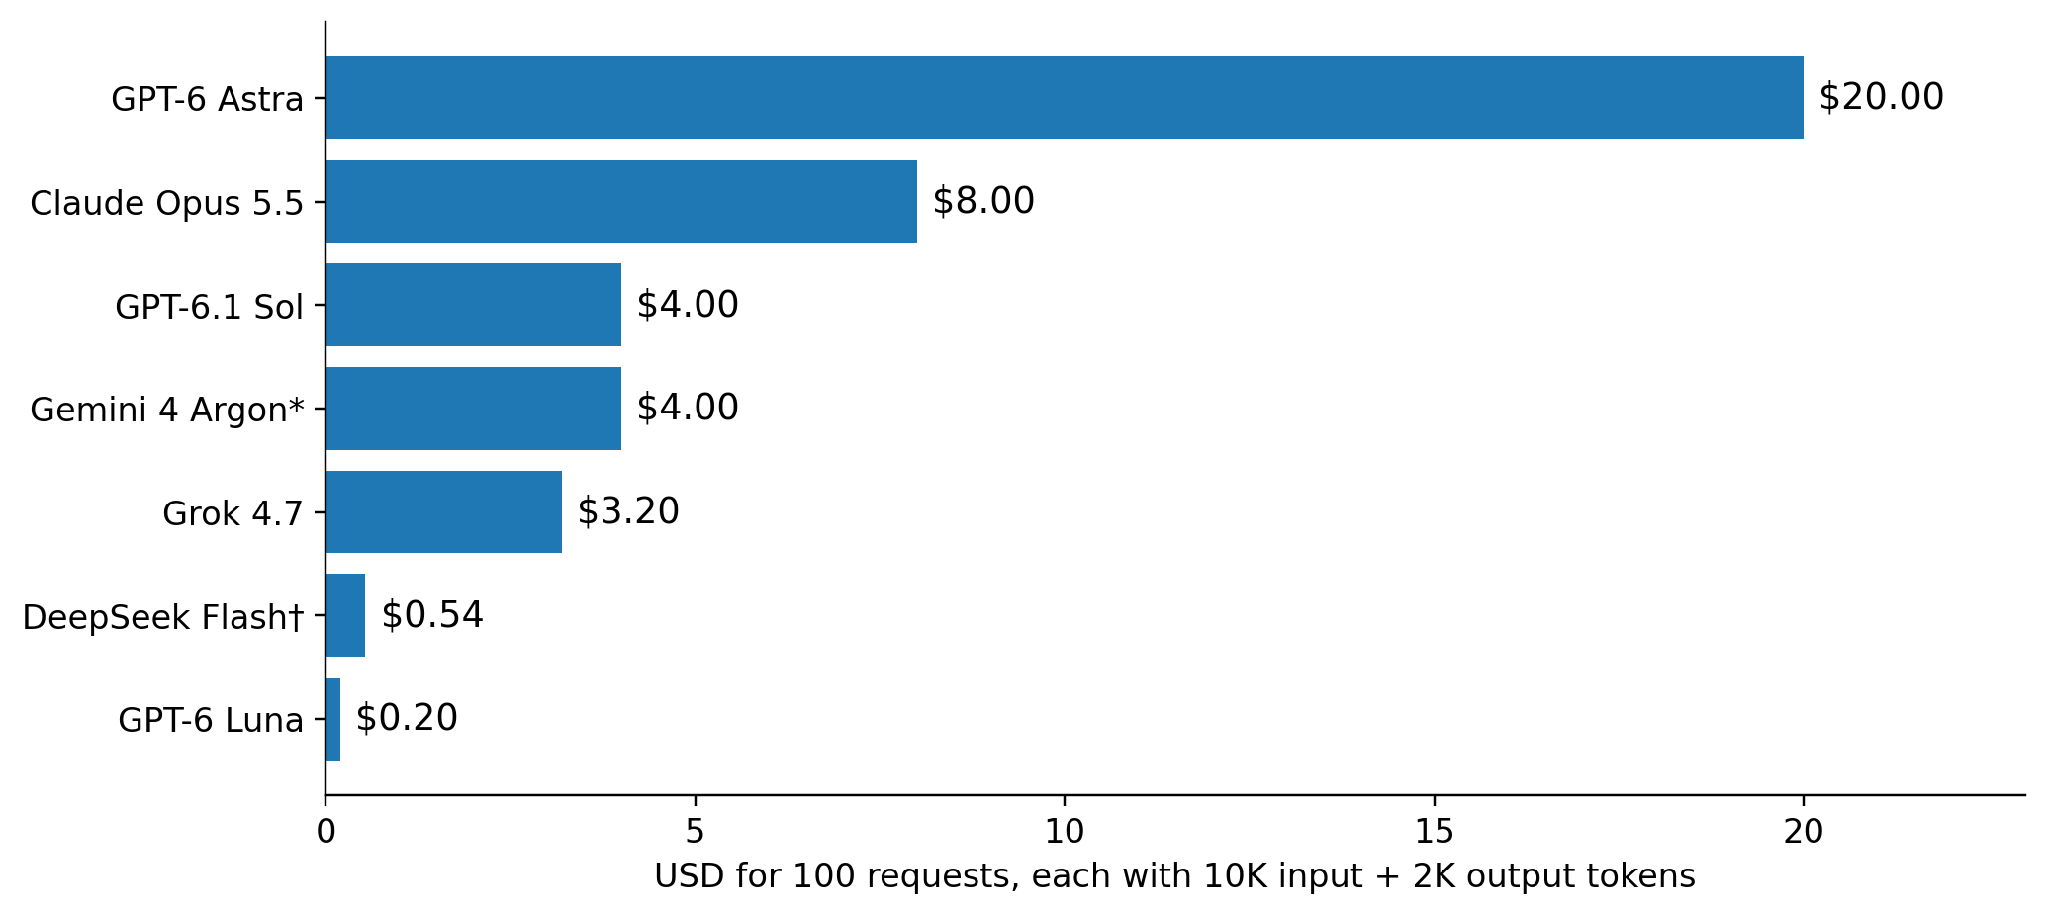
Figure 2. Token-only cost of 100 requests, each 10K input and 2K output tokens (1M in + 0.2M out total). Author calculation from the rates in Figure 1. Not a quality comparison.
Largest context window vs. usable context
A 1M-token context window is now table stakes: Opus, Sonnet, and Haiku 5.5, the whole GPT-6 family, Argon, Kimi, DeepSeek, MiMo. Grok 4.7 lists 500K. Llama 4 Scout still advertises the largest window of any model on the leaderboard and scores 6 on the index, which tells you everything about why window size stopped being a selling point.
The real question is “does it use the context?” Argon’s 1,048,576 is a combined input+output limit so a 900K prompt leaves you with 148K for your answer. GPT-6 charges you double for long prompts. And every model we’ve tested on documents over 100K tokens (more on Summalegal below) gets progressively worse at retrieving a clause from page 60 which modifies page 12 as the window fills. Run that test on your own files before you trust any context number.
Cheapest model, free plan, paid plan: the budget tier got good
Two things that occurred in Sept/Oct change the maths for high volume work. Anthropic priced Claude Haiku 5.5 at $0.10/$0.50 with a 1M window and 236 tokens per second (around 75% cheaper to run than Haiku 4.5). OpenAI responded with GPT-6 Luna at the same rate and put Luna in front of both Free and Go users. On the open weight side DeepSeek V4.1 Flash is undercutting both at $0.30/$1.20 peak and half that off peak.
On the consumer side, free versions now carry a real model rather than a demo: Luna on ChatGPT Free, the Gemini app’s free tier, and Claude’s free plan. The paid plans ($20-ish a month across the board) buy higher usage limits, the top model, and features like deep research and agent modes. Usage limits are the thing to read before you choose, and they change monthly; Anthropic raised Claude’s five-hour limits for Pro, Max, Team, and Enterprise with the Opus 5.5 launch.
How LITSLINK Evaluates AI Systems in Practice
It started with a disagreement in a code review.
Andrii, one of our senior backend engineers, had used GPT-6 Sol to build the ACH reconciliation service for a lending client in Austin. Clean code, passed the linter, 100% test coverage. It also assumes same-day ACH settles in one window. It doesn’t. NACHA runs three same-day windows, the last one closing at 4:45 p.m. Eastern, and a return that landed in that third window would have been classified as a failed payment and kicked off a dunning email to a borrower who had, in fact, paid. The kind of bug that slips through every unit test, because the unit tests were written by the same model that made the assumption.
The engineer running Claude Opus 5.5 on the same ticket in parallel never wrote that bug. It’s not that Opus is the smartest AI in the world (in some abstract sense), it’s that its very first response was a question: which same-day ACH window does your ODFI use for returns? The extended reasoning went through the entire settlement lifecycle before it ever tracked a single function.
That gap doesn’t show up in any benchmark.
We’ve done this kind of head-to-head across client projects for some time now (the public ones linked here and the others under NDA). Same task, different approaches, actual results measured. This is what we’ve found:
| Summalegal | Structured summaries of legal documents up to 25,000 words | Retrieval-augmented generation vs. recursive chunk summarization | Recursive chunking | RAG dropped the indemnification schedule on a merger agreement; recursion reads every clause. Under 1.5% factual drift on a 400-document attorney-scored set |
| LLM assistant for a CRM | Onboarding new sales reps inside the CRM | GPT-5 via LangChain for intent, locally served Falcon for lookups; free-form generation vs. validated API writes | GPT-5 with validated writes | Record completeness went from 60% to 96%; onboarding from 14 days to 5; 90% of queries resolved without escalation |
| RIV task planner | Turning vague briefs into subtasks and risk flags | GPT-5 workflows with and without a human approval gate before anything persists | GPT-5 with the gate | 30 to 45 minutes per brief down to 8 to 12, review included |
| ERP anomaly detection | Flagging wrong entries in financial data | Hand-written rules vs. an unsupervised distribution model | Unsupervised model | Manual spot-checks covered 10 to 15% of transactions; the rule engine drowned the team in false positives |
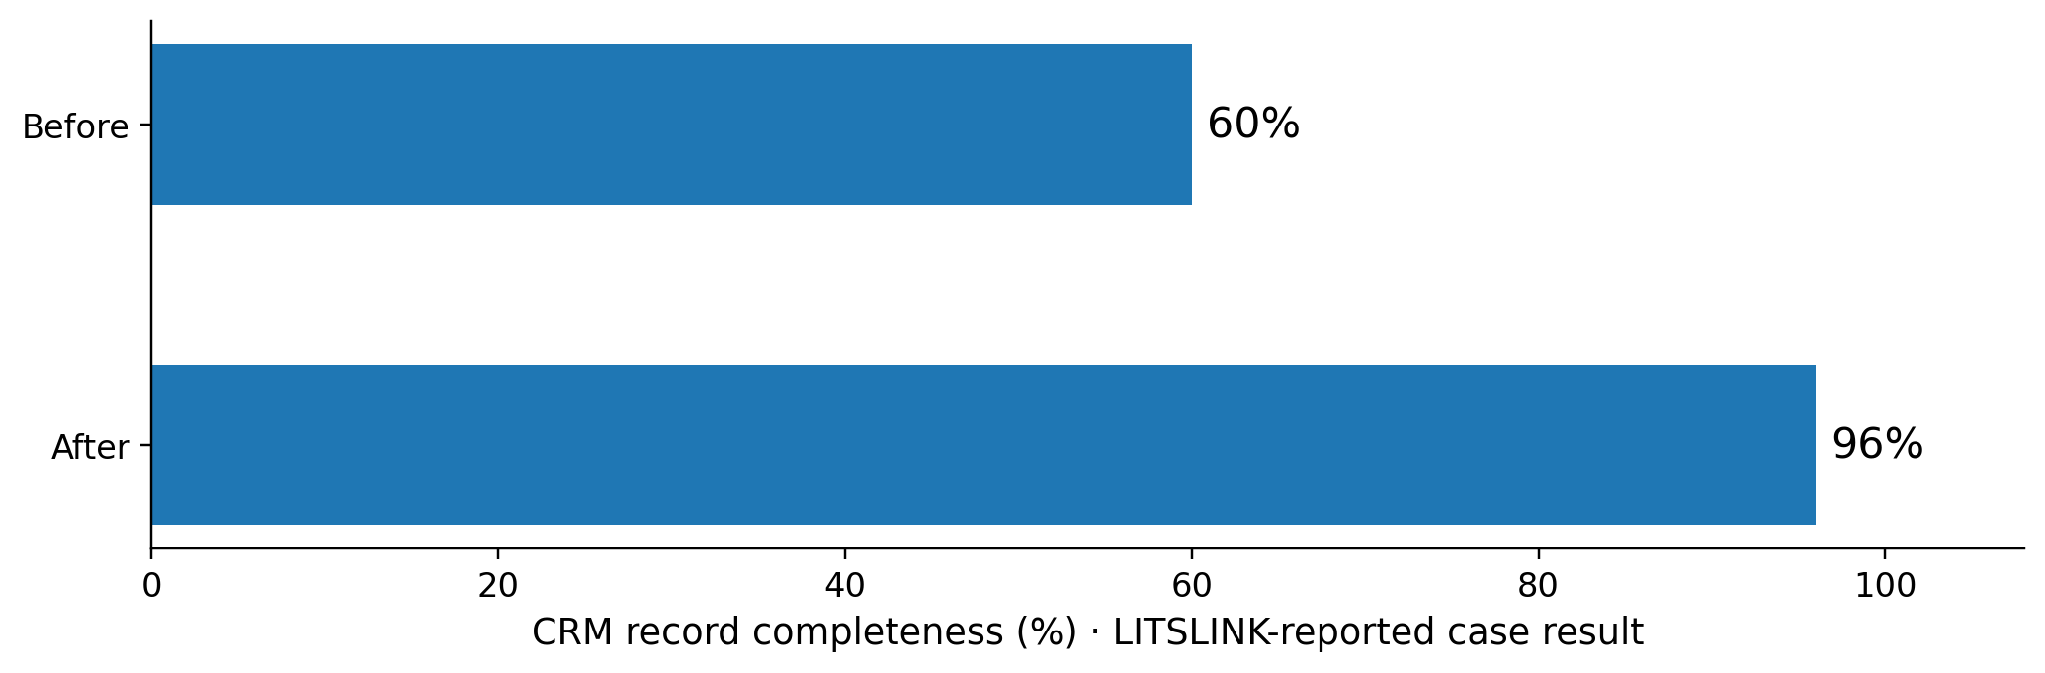
Figure 3. CRM record completeness before and after the assistant, as reported in the LITSLINK case study. A project outcome, not a general benchmark for GPT-5.
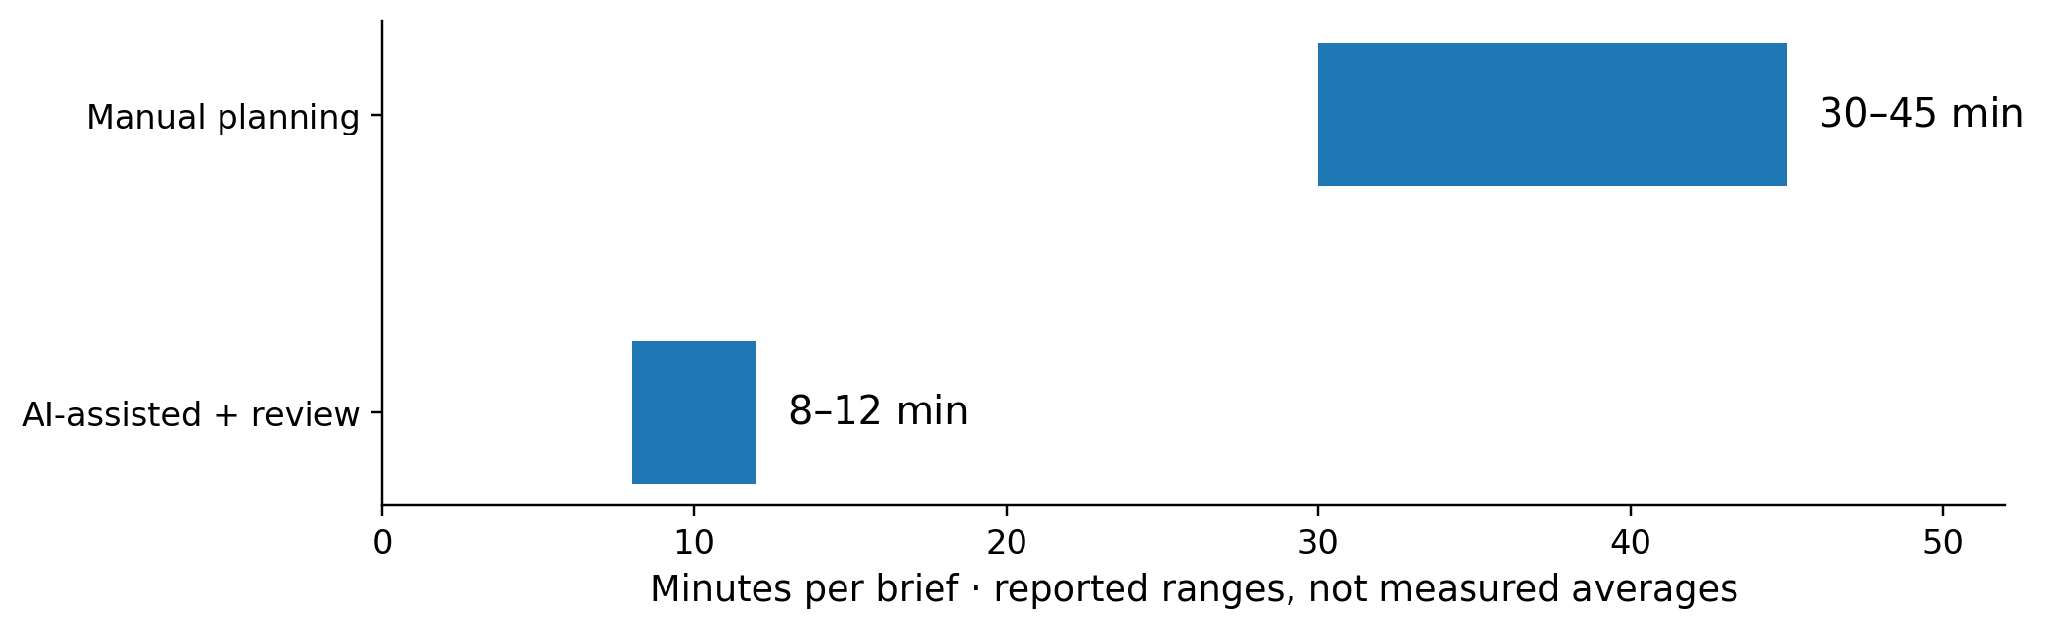
Figure 4. RIV’s reported planning time per brief. Range bars keep the reported intervals rather than inventing an average. Source.
Approaches to Measurement
To be clear about what we’re assessing and why it matters, the old guard of evaluation techniques still have a place. We still have the Turing Test, we still have the cognitive tests, we still have the ML metrics (accuracy/F1 etc) and we still have human evaluation.
That’s why we use the model scoreboard approach that Artificial Analysis employ (their models page compares the systems on quality/intelligence, price, output speed, latency, context window etc). It’s not simply ‘who is the smartest AI’ it’s ‘which of the top AIs is actually usable’.
Here’s the simple framework we use:
| Intelligence (composite) | “Which AI is the best at hard tasks?” | Avoids ranking by a single cherry-picked benchmark |
| Latency & speed | “How fast does it feel?” | UX + agent reliability depend on responsiveness |
| End-to-end time | “How long to get a usable answer?” | Captures input processing + “thinking” + generation |
| Price (blended) | “What does this cost per outcome?” | Determines if a “most powerful AI” is practical |
| Context window | “How much can it handle at once?” | Big docs, repos, and RAG workflows need room |
On the metrics side, Artificial Analysis defines Time to First Token (TTFT), Time to First Answer Token (after any thinking), and End-to-End Response Time (e.g., seconds to output 500 tokens), which together describe “how fast” a model actually feels. For cost, they often use a blended price assuming a 3:1 input-to-output token mix (handy for comparing chat, RAG, and content workloads fairly). We add one line to that framework: cost per accepted task, with the reviewer’s minutes counted. A token price is not an ROI number.
Inside the Summalegal build: five questions we ask every project engineer
Before any system goes into an article like this one, we sit down with the engineer who shipped it. Here’s the Summalegal conversation, condensed. The full numbers are in the case study.
What problem were we solving and what was the baseline? Associates at two pilot law firms were reading 80-page merger agreements line by line and producing the same three-paragraph summary from scratch each time. Document review was about 60% of the recorded time. Roughly 2300 documents a month (around 14k words). Three off-the-shelf summarisers were trialed on 40 actual contracts first, and the attorneys marked 71% of those as unusable without a full re-read. On two of the documents, the parties were swapped.
Why this rather than the obvious (RAG)? We tried RAG on 20 documents and it just failed. RAG is all about retrieval, and it optimizes for the best passages. A summary, however, needs all the passages. It would drop the indemnity schedule on one merger agreement. So the pipeline takes each document, breaks it into sentence-bounded chunks of about 1,200 tokens with 150 tokens of overlap, summarises each chunk, then merges and summarises again, doing this three levels deep on the longer documents. RAG still made the build (the Q&A function that allows an attorney to query a document afterward and have the answer reference the relevant clauses is built on it).
What was the actual impact? The merger agreement, which previously took 3-4 hours, now takes 20-25 minutes (including attorney review). 92% of the summaries were accepted without any correction following fine-tuning. Factual drift was less than 1.5% on a 400-document set that the client’s own attorneys scored manually. A 92-page asset purchase agreement with 141 clauses comes back as a 640-word summary in 41 seconds.
What went wrong? 22 rounds of prompt work (none of which you budget for). A clause comparison view that three people on the team absolutely adored and nobody could for the life of them, work out how the workflow worked. It got cut in design review. The thing that saved the project was the two-week loop with actual attorneys scoring actual contracts. A single big end-of-project review would have cost us around six weeks of rework.
#1 piece of guidance for someone in this exact situation? Hardcode the line the model must not cross. In Summalegal, the model never states a legal conclusion. It identifies; the attorney decides. That one rule did more for adoption than any benchmark score, and nine weeks after launch, 78% of eligible attorneys were summarizing at least one document a week.
AI development services evolve from year to year to surpass limitations and expand the technology. Keeping the measurement methods in mind, let’s get to the question people actually search for.
What Is the Smartest AI in 2026? The Answer Depends on How Long You’re Willing to Wait
“Smartest” used to mean the biggest model. By 2026, it means the model you let think the longest. All the frontier systems now come with an effort setting (low, medium, high, xhigh, max) and that setting moves the score, the latency, and the invoice together.
Reasoning models and extended thinking: the same model, two different IQs
Claude Opus 5.5 gets a 58 on the Intelligence Index at max effort and takes circa 562 seconds before the first chunk of answer appears. At medium effort it’s 51 and it takes about 10 seconds. That’s one model, one price point and a seven-point difference that you can toggle with a parameter. GPT-6 Astra is identical in its behavior: 53 at max (247 seconds to first chunk), 4 seconds at medium. Artificial Analysis publishes both figures; most of the comparison pieces only quote the top one.
Think of it like a hospital. A board-certified diagnostician given a full afternoon and a complete chart will beat the ER resident almost every time. Put the same diagnostician on a Saturday night with ninety seconds per patient and the gap mostly disappears. The smartest AI in the world, measured at max effort, is a diagnostician with the afternoon. Your product usually needs the resident.
On the hardest public tests, here is where the frontier models stand, with the caveat that most of these are vendor-reported:
- Humanity’s Last Exam (with tools): Claude Opus 5.5 67.7%, Fable 5.1 65.6%, Sonnet 5.5 64.5%, GPT-6 Astra 57.2% (Anthropic; OpenAI’s own page lists Astra at 57.2% against Fable 5.1 at 65.0%).
- FrontierMath Tier 4: GPT-6 Astra 97.6% (OpenAI). Epoch AI, which runs the benchmark, notes OpenAI funded it and holds exclusive access to part of it. Worth being skeptical of, in the way a sponsored race time is.
- GPQA Diamond: GPT-6 Astra 96.0% (OpenAI). At this level, the test is effectively saturated.
- ARC-AGI-3: Astra 62.7% on the standard harness, 99.9% with the provider adapter, per ARC Prize. Astra also used 51.7% fewer actions per level than the median human tester.
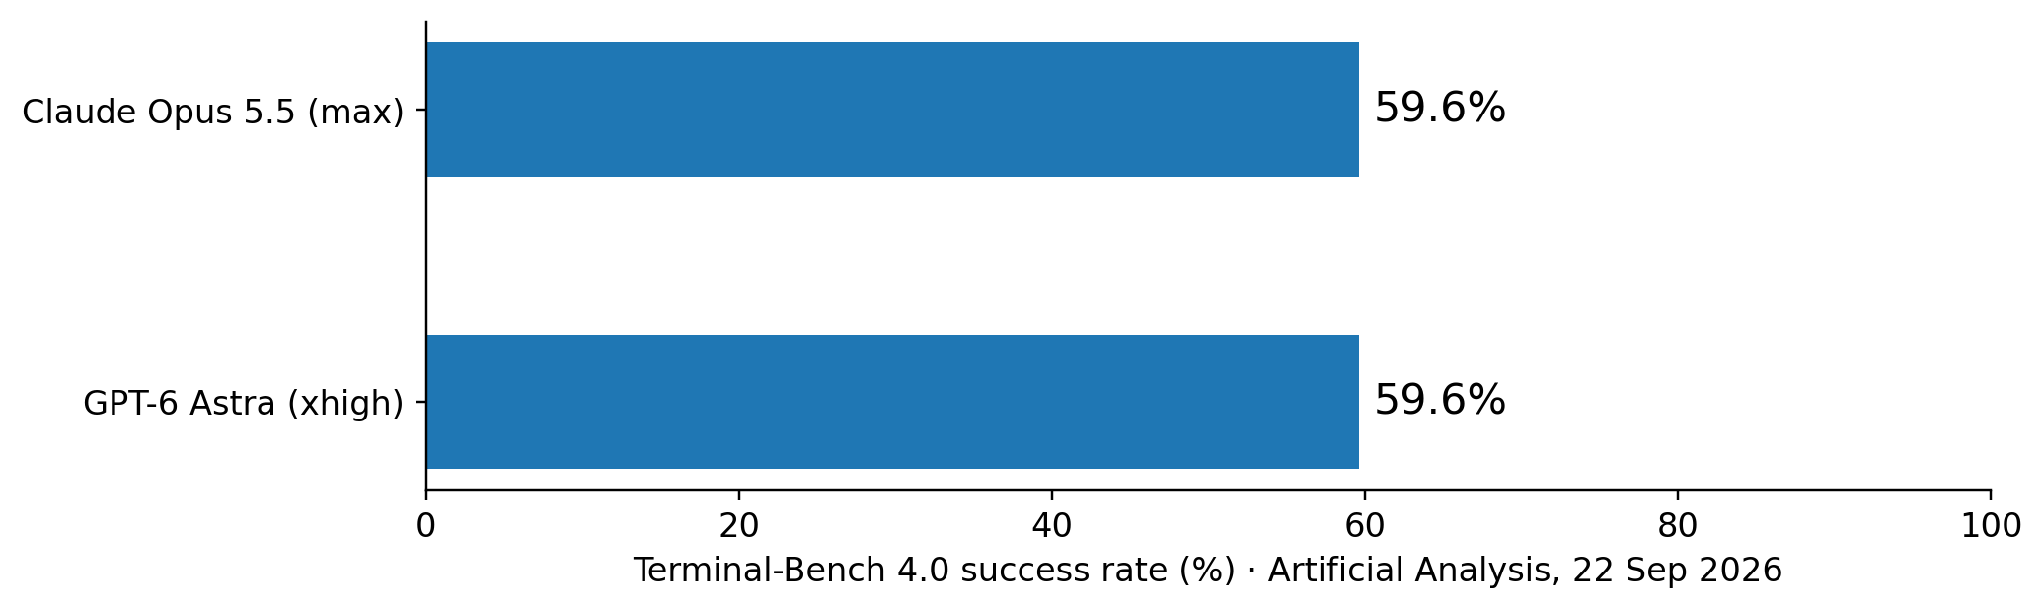
Figure 5. One independent coding benchmark, one tie. Artificial Analysis measured both at 59.6% on Terminal-Bench 4.0; the two ran at different named effort settings, so this is not an equal-compute experiment. Source.
Why benchmark margins stopped predicting real-world gaps
Anthropic’s own launch notes for Opus 5.5 state it plainly: at these capability levels benchmark margins have become “a less reliable guide to actual differences”. I’d go even further. A single pass benchmark is just one test, one prompt, no retries, no tools. Real-world production is the exact opposite: multiple passes, awful input, a tool that times out on the third attempt. The Terminal-Bench tie above is the true picture of the frontier. Two labs, two architectures, 59.6% each.
What actually separates them in the real world is their behavior in the face of failure. Does the model ask the question (the ACH one above) before it assumes? Does it stop when a tool returns nothing or does it just make something up? Does it tell you it doesn’t know? None of that is on the LLM leaderboard and all of that is what determines whether an AI system can survive a real interaction with a customer.
Most Powerful AI by Category: Eight Jobs, Eight Different Winners
“What is the most powerful AI model right now?” is the question we hear on almost every discovery call, and the honest response is the table below.
| Text and knowledge work | Claude Opus 5.5 | Claude Sonnet 5.5 (value) | #1 on the Intelligence Index at 58; GDPval-AA v2.1 Elo 1846 vs. GPT-6 Astra 1542 | Independent; vendor-reported |
| Agentic coding | Claude Sonnet 5.5 / Opus 5.5 | GPT-6 Astra | Terminal-Bench 4.0: Sonnet 5.5 70.6%, Opus 5.5 66.4%, Astra 57.9% on Anthropic’s harness; 59.6% tie on Artificial Analysis’ | Vendor-reported; independent |
| Computer use and automation | Claude Sonnet 5.5 | GPT-6 Astra | OSWorld 2.1 offline: Sonnet 5.5 83.9%, Opus 5.5 81.8%; AutomationBench: Astra 41.4%, Opus 5.5 40.0% | Vendor-reported |
| Human-preferred chat | Gemini 4 Argon | Claude Opus 5.5 | LMArena text: 1532 vs. 1516, preliminary | Independent |
| Deep research | GPT-6 Astra | Claude Opus 5.5 | BrowseComp 91.5% (OpenAI); Opus 5.5 produced 16 of 18 research reports with no invented figures in Anthropic’s internal test | Vendor-reported |
| Video generation | Gemini Omni 1.1 Flash | Seedance 2.0 / Wan 3.0 | Arena text-to-video: 1516 vs. 1479 and 1476; Veo 3.1 at 1364 (#12), Sora 2 at 1343, Runway Gen-4.5 at 1225 (#27) | Independent, Sep 21, 2026 |
| Cheap, high-volume work | Claude Haiku 5.5 | GPT-6 Luna, DeepSeek V4.1 Flash | $0.10 / $0.50 per 1M; 236 tokens/s; DeepSeek at $0.26 per index task | Vendor list price; independent |
| Open-weight, self-hosted | MiMo-V2.6-Pro | DeepSeek V4.1 Flash, GLM-5.3 | Index scores 46, 45, 45; the top open-weight entries on the leaderboard | Independent |
Two things jump out of that table. First, Anthropic owns the agentic column, and Google owns the human-preference and video columns, which map almost exactly onto what each company sells. Second, the top 10 most powerful AI systems in the world no longer come from three US labs. Kimi, MiMo, DeepSeek, and GLM are all in the top 15 of the composite index, and all four ship open weights or near-frontier pricing.
The 18 Most Advanced AI Systems in 2026, Field by Field
Artificial intelligence and machine learning keep changing how we work, and the list of systems worth your attention changes with them. Here are the most powerful AI tools currently available to enterprises, grouped into five fields by the job they do rather than the company that makes them. Each entry gets the same treatment: what it is, what it’s best for, why it’s advanced in late 2026, and the one limitation the sales deck leaves out.
While there are many examples of advanced AI systems, not all are sufficiently capable to compete with those presented here.
Field 1: Text & Knowledge Work
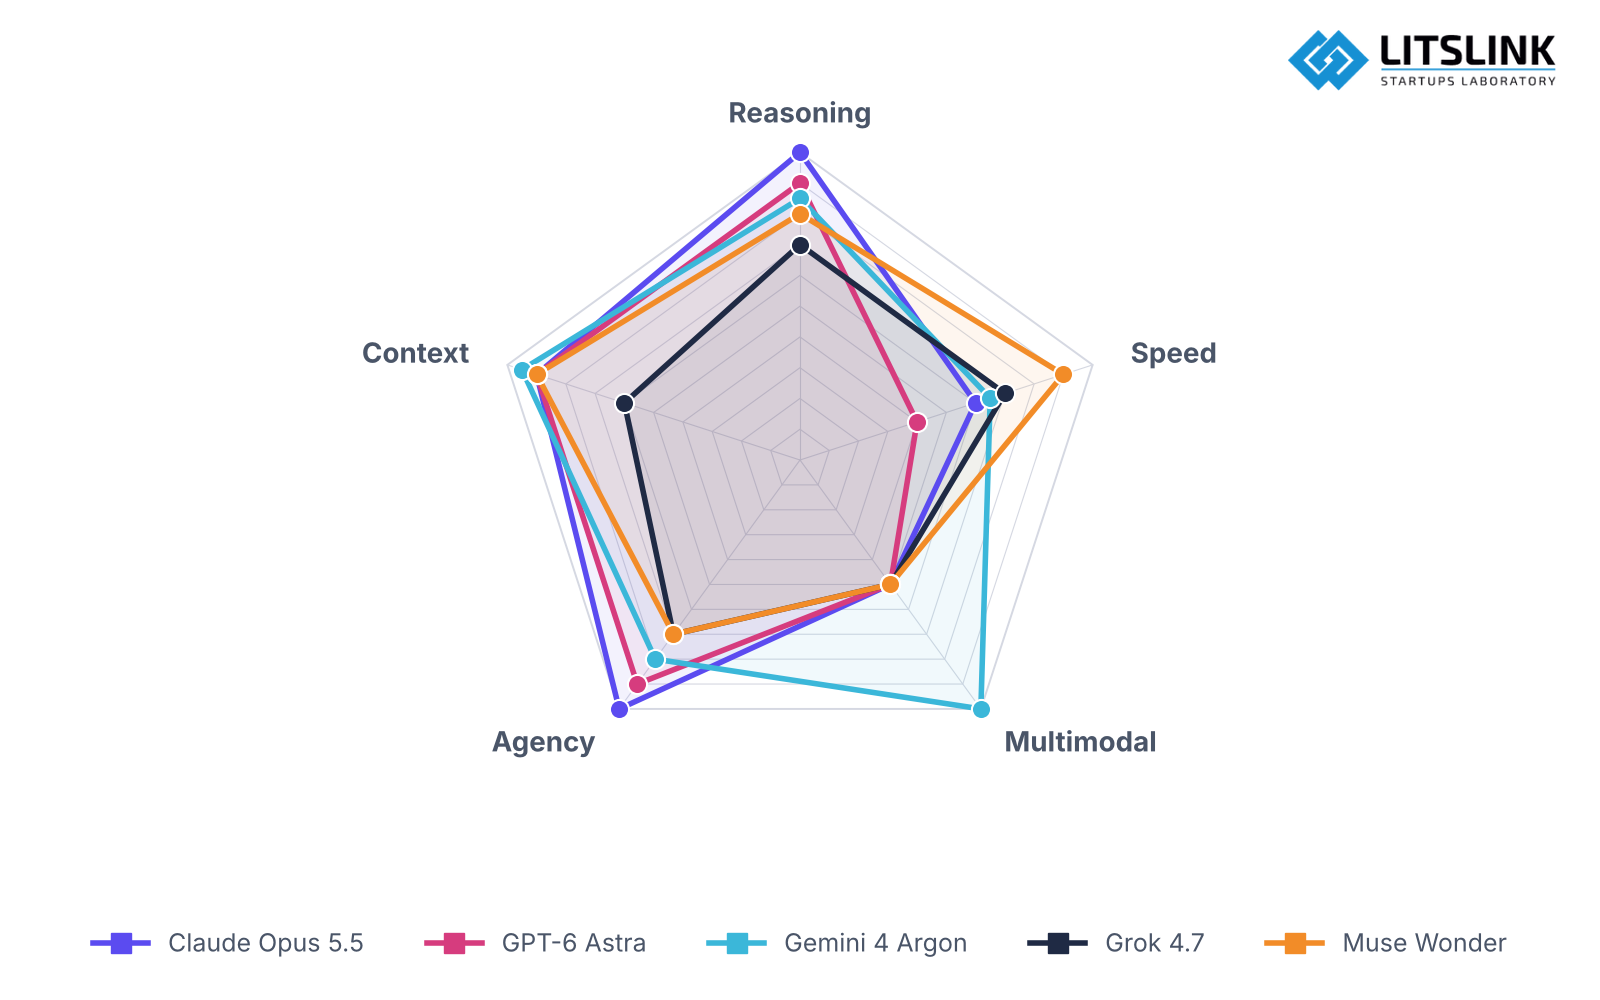
Five frontier models on five axes. LITSLINK editorial assessment, 1–10 scale, October 2026, informed by the Artificial Analysis data in the table above; not a benchmark.
1) Anthropic – Claude Opus 5.5 and Claude Sonnet 5.5
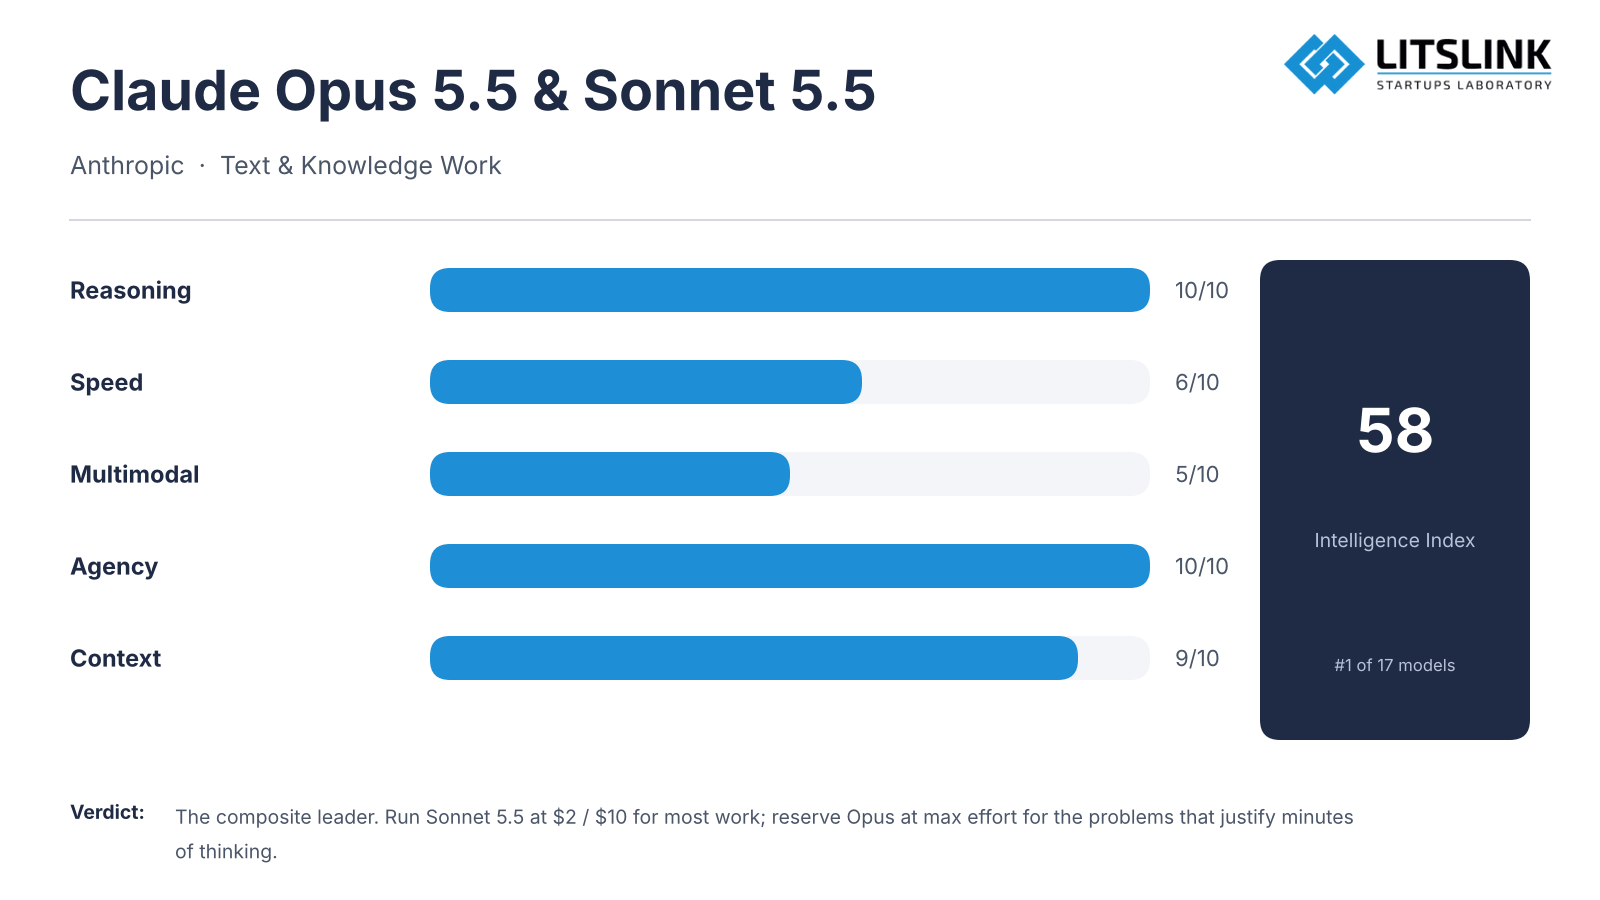
What it is: Anthropic’s flagship pair. Opus 5.5 is the model that tops the independent composite; Sonnet 5.5 is the one most teams will actually run, at half the price and a third more speed.
Best for:
- Long-document analysis where a missed clause costs money
- Agentic coding and multi-step tool use
- High-quality writing with uniform tone across a whole deliverable
Why it’s advanced in late 2026: Claude Opus 5.5 shipped on September 22 at $4 / $20 per 1M tokens, a 20% cut from Opus 5, with cache reads at $0.20 and a 1M-token window on by default. It scores 58 on the Artificial Analysis Intelligence Index, first by two points. Anthropic’s own evaluations put it at 67.7% on Humanity’s Last Exam with tools and 66.4% on Terminal-Bench 4.0. Sonnet 5.5 followed on September 28 at $2 / $10, scores 56, runs at 133 tokens per second, and on October 7 Anthropic cut its cache reads to $0.10. Adaptive thinking means the model decides how much reasoning a request needs, and thinking can no longer be switched off entirely on either model, which is a design statement as much as a feature.
The catch: At max effort, Opus 5.5 takes minutes to start answering. Budget for the medium setting in anything interactive, and read the Claude Opus 5.5 vs. Sonnet tradeoff before defaulting to the expensive one. Sonnet beats Opus on Terminal-Bench 4.0 (70.6% vs. 66.4%) in Anthropic’s own numbers.
2) OpenAI – GPT-6 Astra, Sol, and Luna
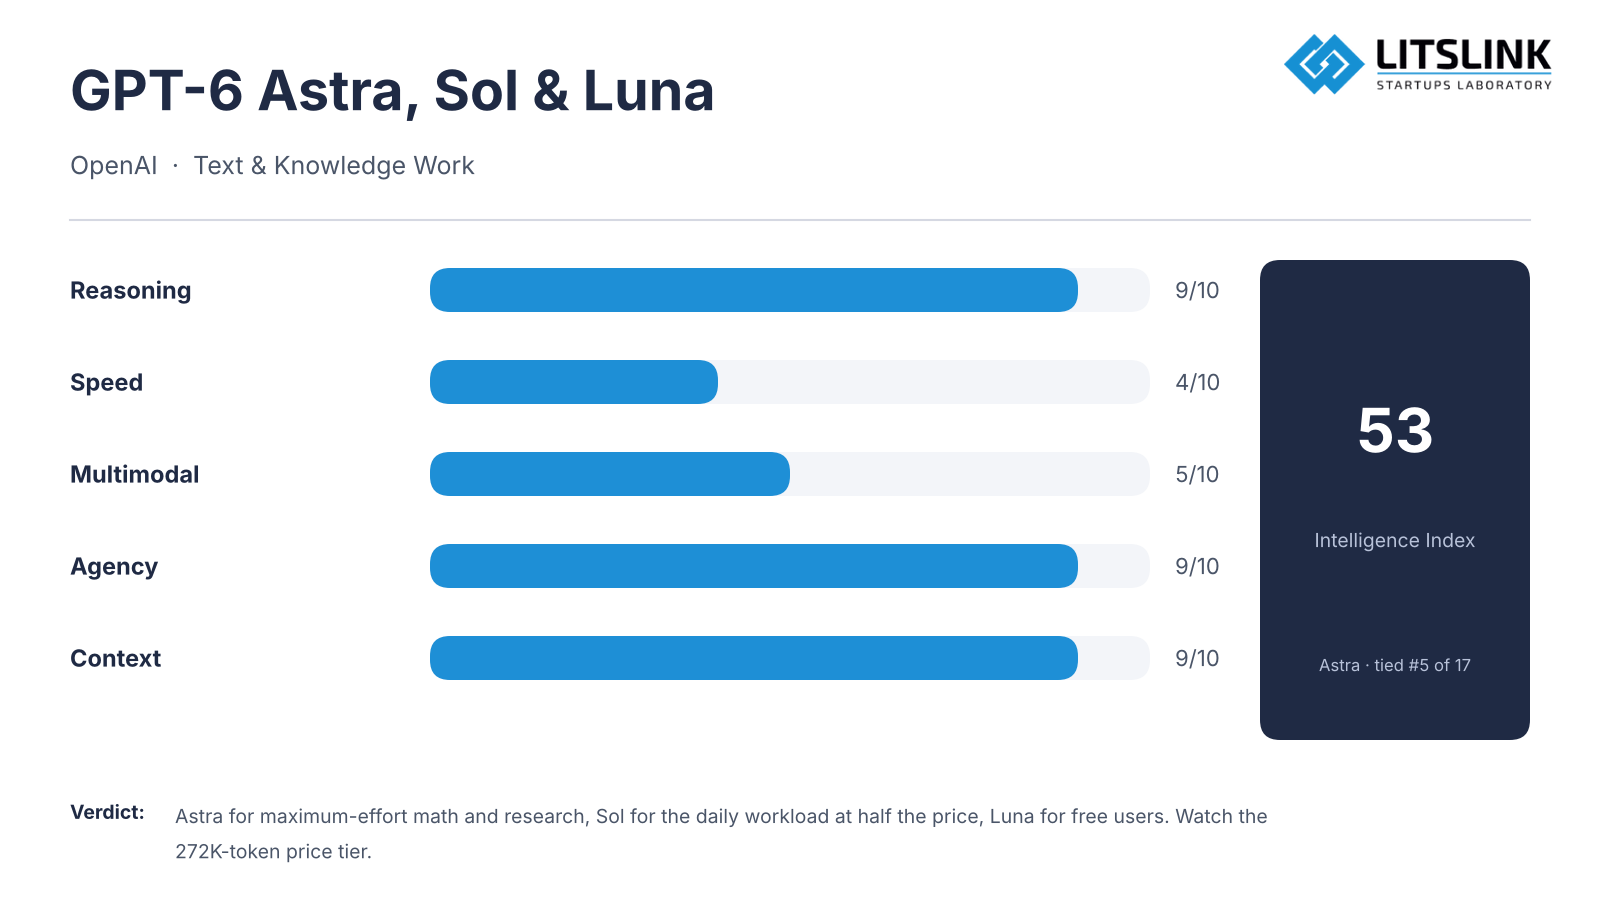
What it is: OpenAI’s three-tier family, released in September 2026. Astra is the high-effort reasoning model, Sol is the workhorse and Luna is the budget tier (the one that Free and Go users get).
Best for:
- Hardest math, science, and multi-step agent tasks (Astra)
- Structured writing, briefs, specs, and research synthesis with citations (Sol)
- High-volume everyday work where $0.10 per 1M input tokens is the point (Luna)
Why it’s advanced in late 2026: GPT-6 Astra reports 97.6% on FrontierMath Tier 4, 96.0% on GPQA Diamond, 91.5% on BrowseComp, and 72.6% on OSWorld 2.0, and ARC Prize measured it at 99.9% on ARC-AGI-3 with OpenAI’s provider adapter. It costs $10 / $50 per 1M tokens with a 1.05M window and a 128K max output. GPT-6 Sol and Luna landed the same day as Opus 5.5 (September 22; not a coincidence) at $2 / $10 and $0.10 / $0.50, half the GPT-5.6 rates. Sol scores 68.8% on DeepSWE v1.1 and 60.5% on OSWorld 2.0 in OpenAI’s tests; GPT-6.1 Sol, released at DevDay on September 29, nudges those numbers and scores 52 on the independent index.
The catch: Prompts over 272K input tokens are billed at 2x input and 1.5x output for the whole request. A 1M-token window you pay double to use is a smaller window than it looks. And the family is text and image in, text out; audio and video live in separate Realtime models.
Read about ChatGPT’s accuracy in our article, and the GPT-4 to GPT-6 lineage if you need the history.
3) Google – Gemini 4 Argon (Gemini App + API)
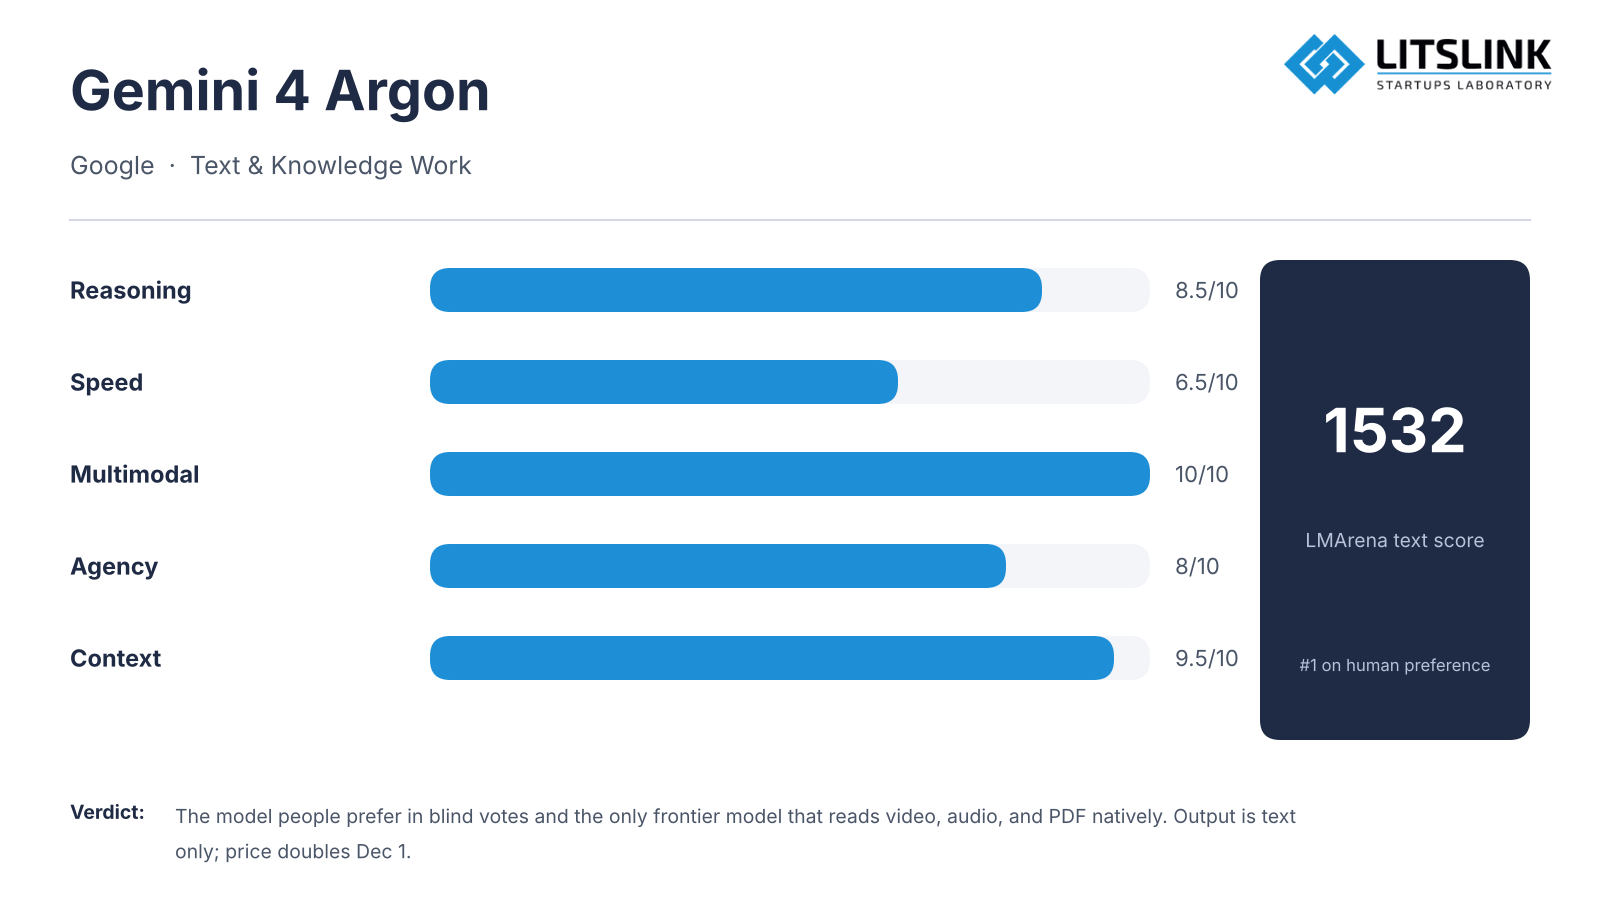
What it is: Google’s frontier model, announced September 30 and in the Gemini app for AI Pro and Ultra subscribers since October 13. Natively multimodal on input, tightly wired into Workspace and Search.
Best for:
- Knowledge work inside Google Workspace platform (Drive, Docs, Gmail, Meet)
- Mixed-media input: a PDF, a video, and a spreadsheet in the same prompt
- Human-facing chat, where it currently wins blind preference votes
Why it’s advanced in late 2026: Gemini 4 Argon scores 53 on the Intelligence Index, is #1 on LMArena at 1532 and takes text, image, video, audio and PDF input against a 1,048,576 token unified limit. Google reports a #1 rank on the VALS Index, 87% on the ERQA embodied reasoning benchmark and attack success down to 0.7% on the Gray Swan indirect prompt injection test. Introductory API pricing is $2/$10 with cached input 95% off, increasing to $4/$20 on 1st December 2026. Gemini has been integrated into the Workspace apps so it can search Drive, Docs and Gmail to answer questions, making it the best AI for the enterprise that’s already in the Google ecosystem.
The catch: Output is text only. No native image or audio generation on this endpoint; no Live API. Argon reads your video; it doesn’t make one. For that, see Gemini Omni in Field 3.
4) SpaceXAI – Grok 4.7
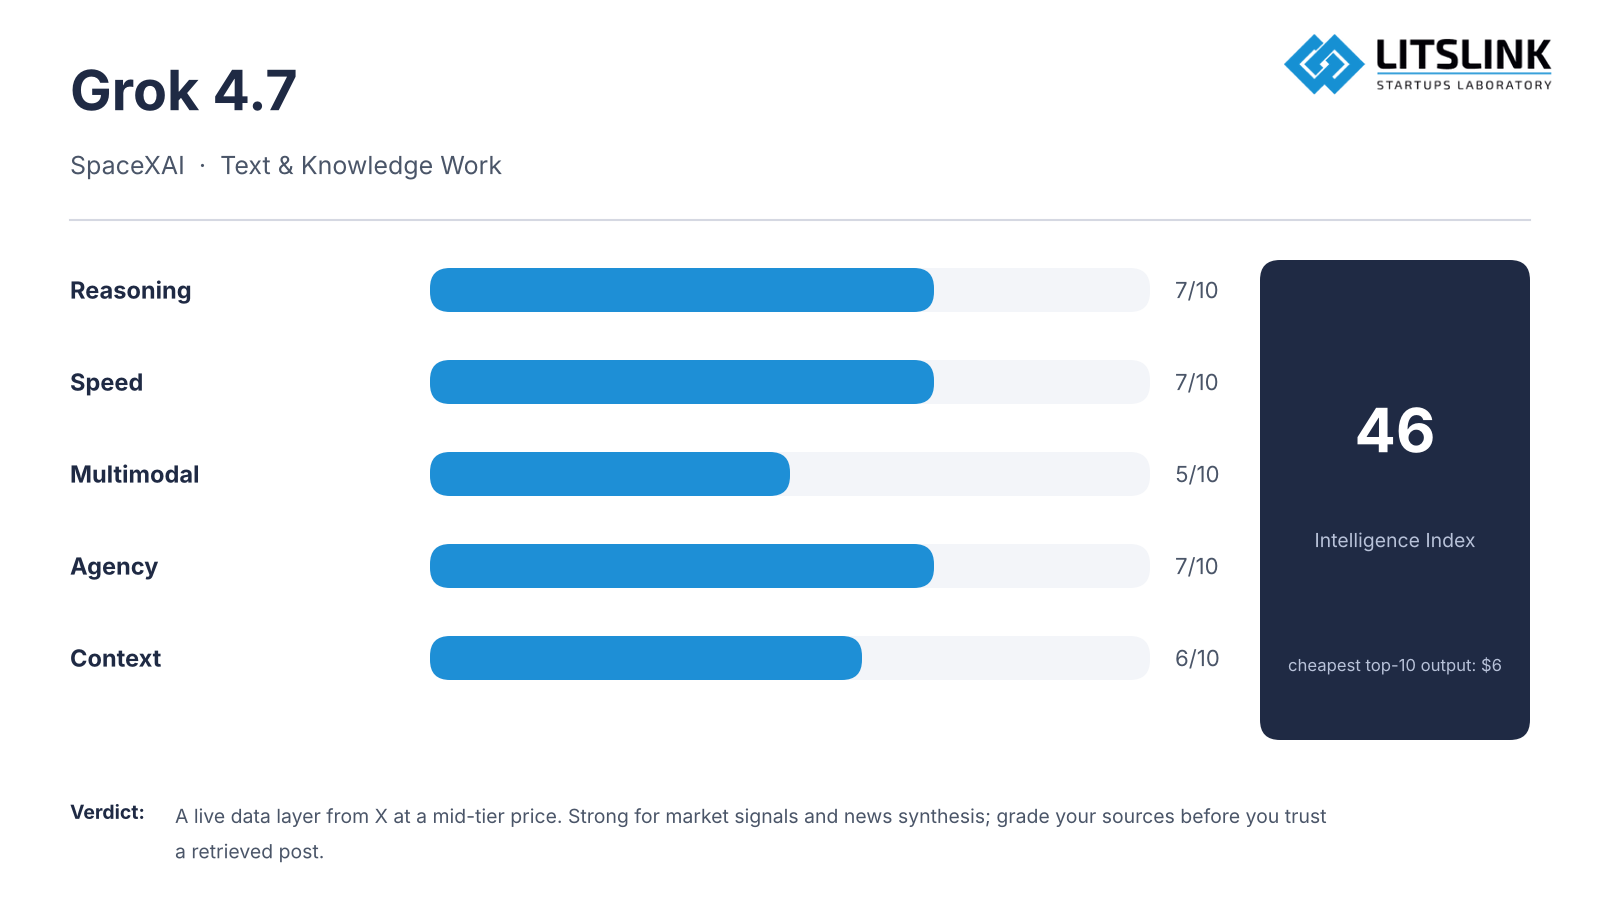
What it is: The flagship model from what was xAI and is now SpaceXAI following the SpaceX acquisition. It has native access to real-time X platform data via connected search.
Best for:
- Teams that need live market signals, breaking news synthesis, or real-time competitive intelligence
- Coding and agentic tasks at a mid-tier price
- Financial research, investment thesis development, and analysis tasks where yesterday’s data changes the answer
Why it’s advanced in late 2026: Grok 4.7 shipped September 21 at $2 / $6 per 1M tokens, the cheapest output price of any model in the top 10, with a 500K-token window and 97 tokens per second. It scores 46 on the Intelligence Index. What actually sets Grok apart from the other top AI models in this category isn’t a benchmark score; it’s the live data layer. Claude and GPT-6 work from fixed training snapshots plus web search; Grok can pull breaking posts from X, regulatory updates, and earnings chatter into the same reasoning context, lacking a separate retrieval step.
The catch: A retrieved post is not a verified fact, and live awareness without source grading is a liability in financial work. Pricing moves to a higher tier above 200K prompt tokens. And the model is text and image only.
5) Meta – Muse Wonder and Muse Wonder Full
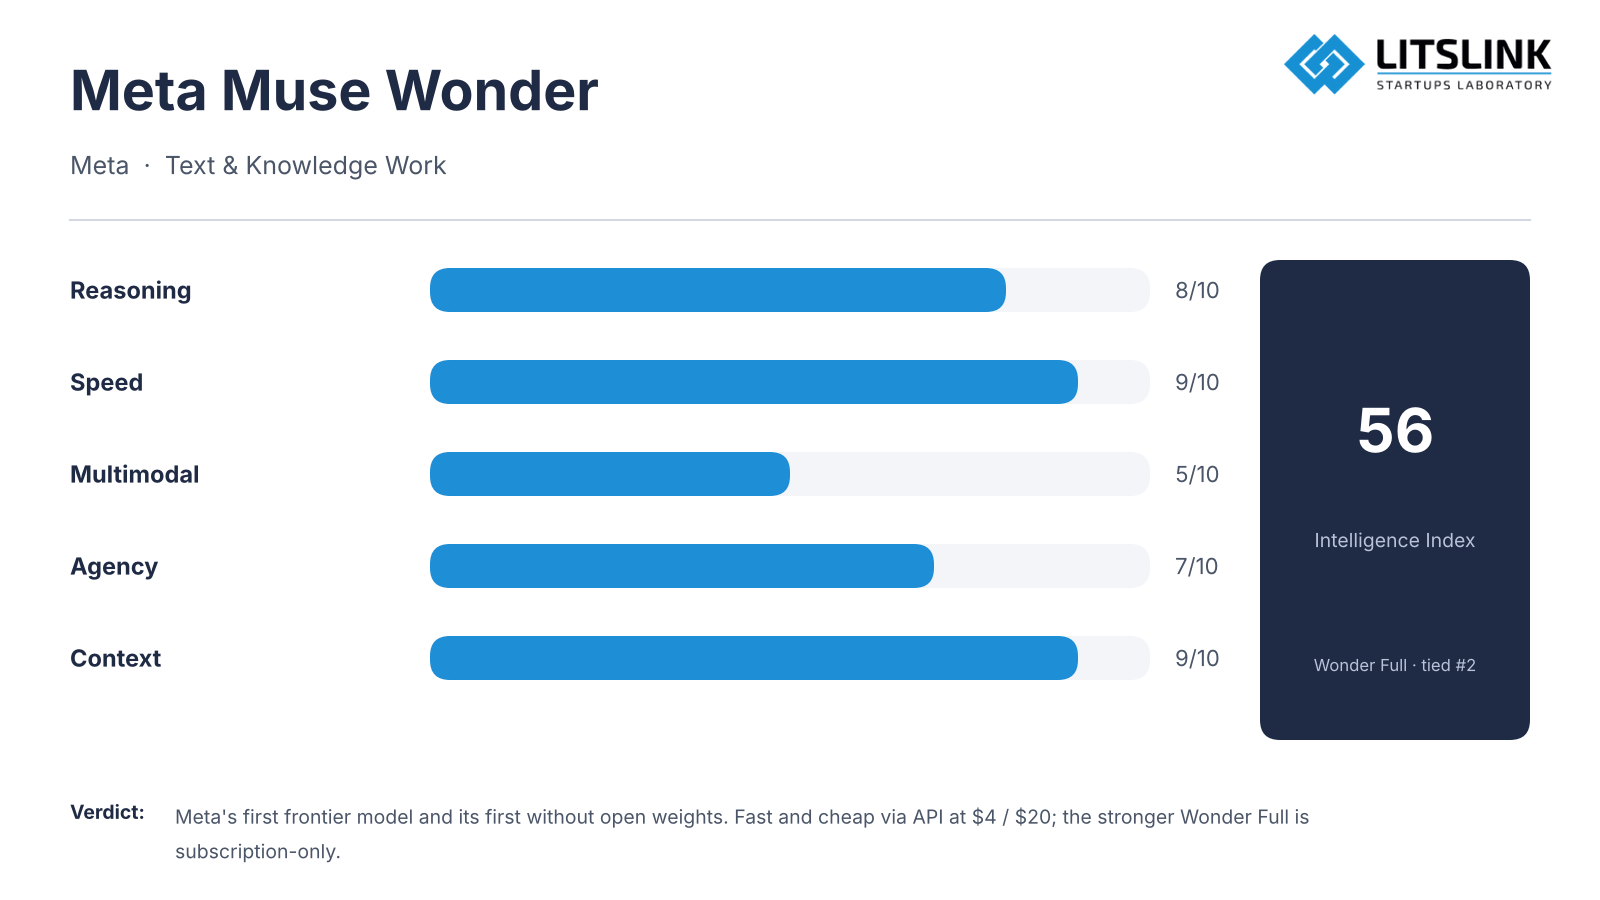
What it is: Meta’s first frontier model, released October 12, and the first Meta model since Llama that ships without open weights.
Best for:
- Fast, high-throughput knowledge work (Muse Wonder runs at 145 tokens per second)
- Teams on Meta’s own coding product, Muse Code, which is the only place Wonder Full is available
Why it’s advanced in late 2026: Muse Wonder Full scores 56 on the Intelligence Index, tied for second with Sonnet 5.5, and the API-available Muse Wonder scores 52 at $4 / $20 with a 1.05M-token window. After two years of Llama releases that trailed the frontier, Meta is suddenly in the top three.
The catch: Wonder Full has no API and no weights. If you built your 2025 stack on “Meta will always open-source the good one,” that assumption expired on October 12.
Need to integrate AI into a text or knowledge workflow? LITSLINK helps teams move from model evaluation to production. Talk to our team →
Field 2: Coding and Engineering
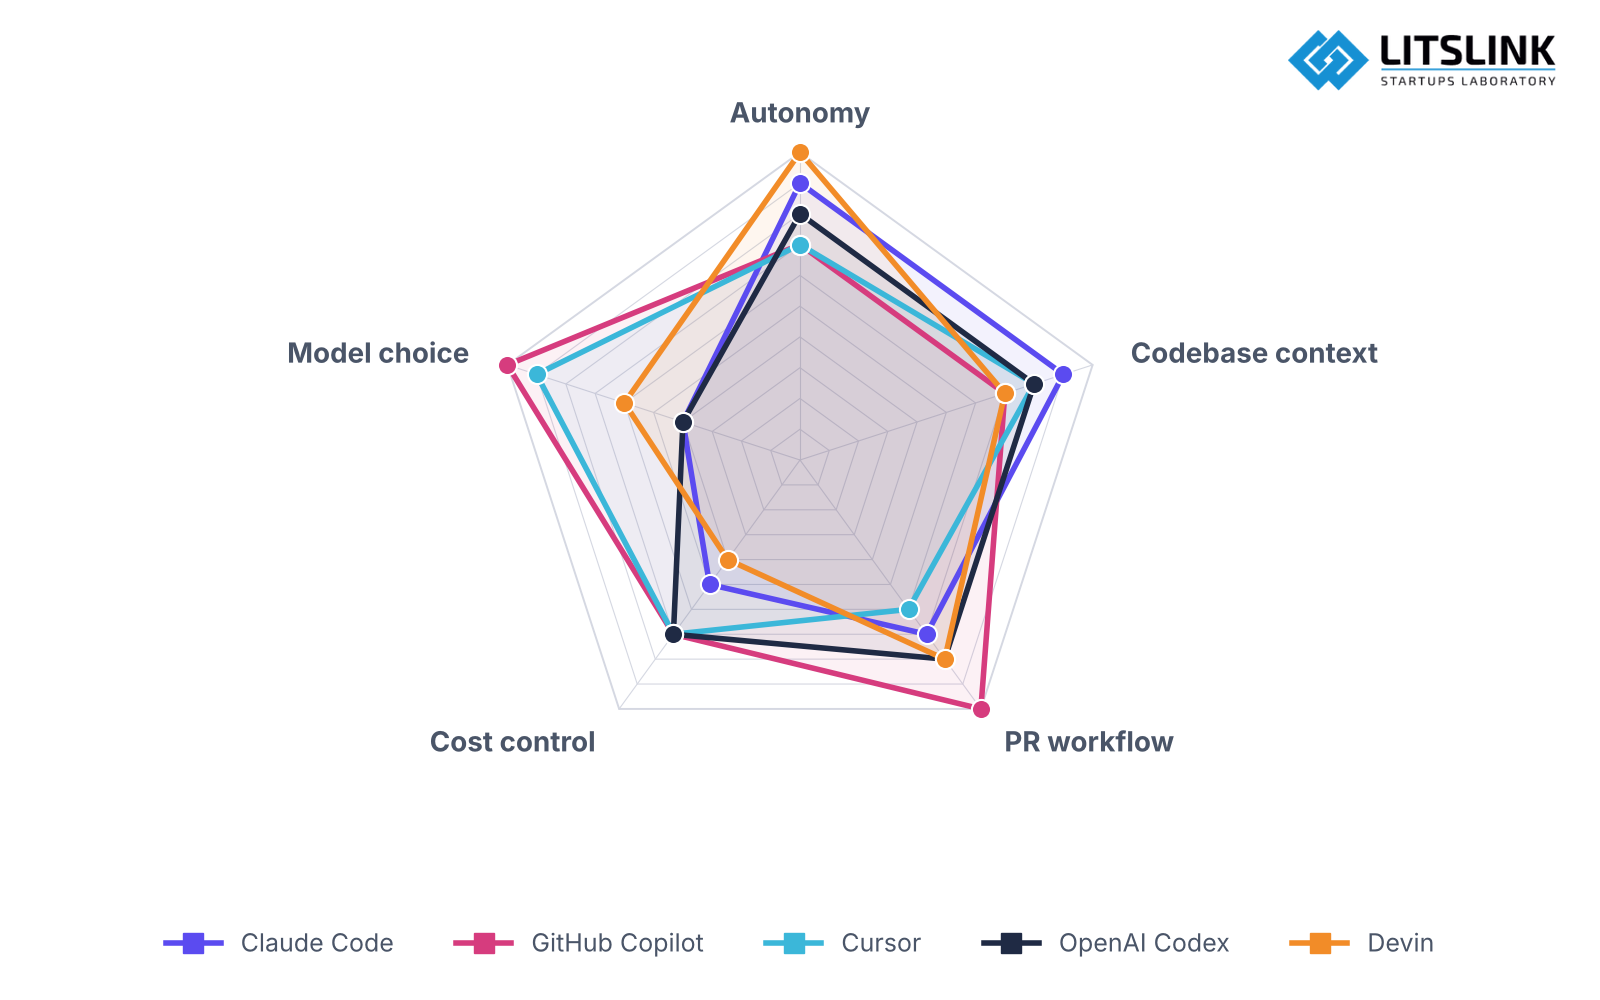
Five coding tools on five axes. LITSLINK editorial assessment, 1–10 scale, October 2026; products, not models, so no leaderboard applies.
6) Anthropic – Claude Code
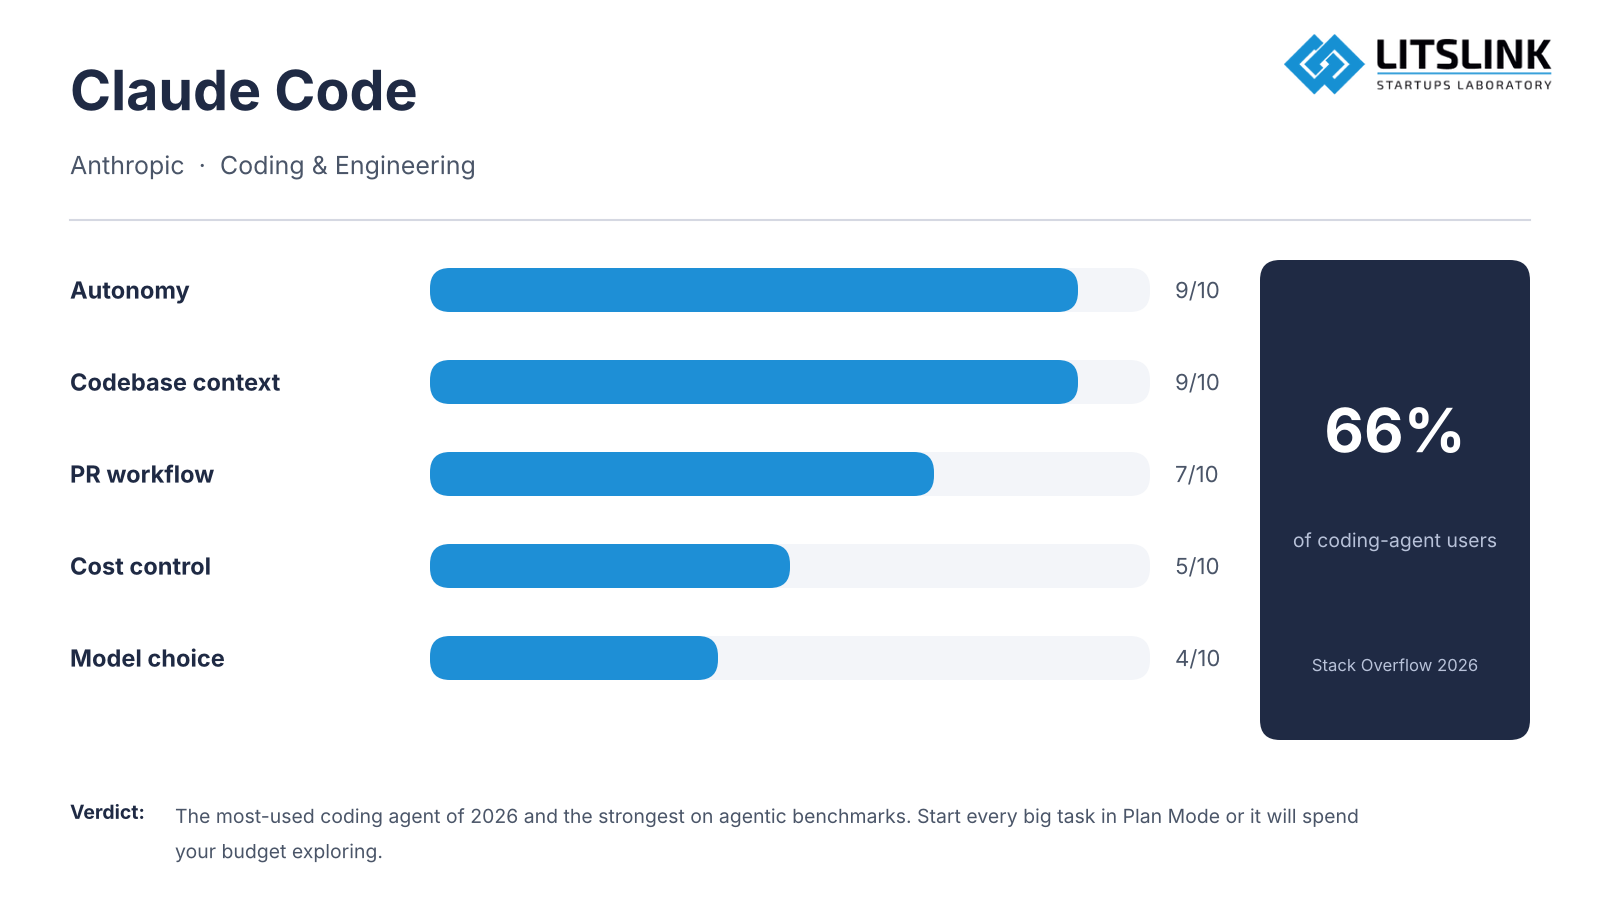
What it is: Anthropic’s agentic coding tool that lives in the terminal, the IDE, and CI, and runs the same Claude models with full repository context.
Best for:
- Multi-file changes across an entire codebase, with tests run and fixed in the loop
- Long-running delegated tasks (migrations, refactors, test coverage)
- Teams that want one agent harness across terminal, VS Code, and GitHub Actions
Why it’s advanced in late 2026: In the Stack Overflow 2026 Developer Survey, Claude Code is the most-used coding agent at 66% of agent users, ahead of GitHub Copilot at 59%. The reason is mostly the model underneath: Anthropic reports Opus 5.5 at 57.8% on CursorBench 4.0 against 41.7% for GPT-5.6 Sol, and GitHub’s own product team said Opus 5.5 “used among the fewest tokens and steps we measured” in Copilot CLI. Claude Code also made subagents a default pattern: a frontier model plans, a Haiku 5.5 subagent at $0.10 per 1M input does the retrieval and the summaries.
The catch: It is not cheap at the top setting, and it will happily spend an hour on a task you could have scoped in a sentence. Plan Mode first, always.
7) GitHub – GitHub Copilot (Agent Mode + Cloud Agent)
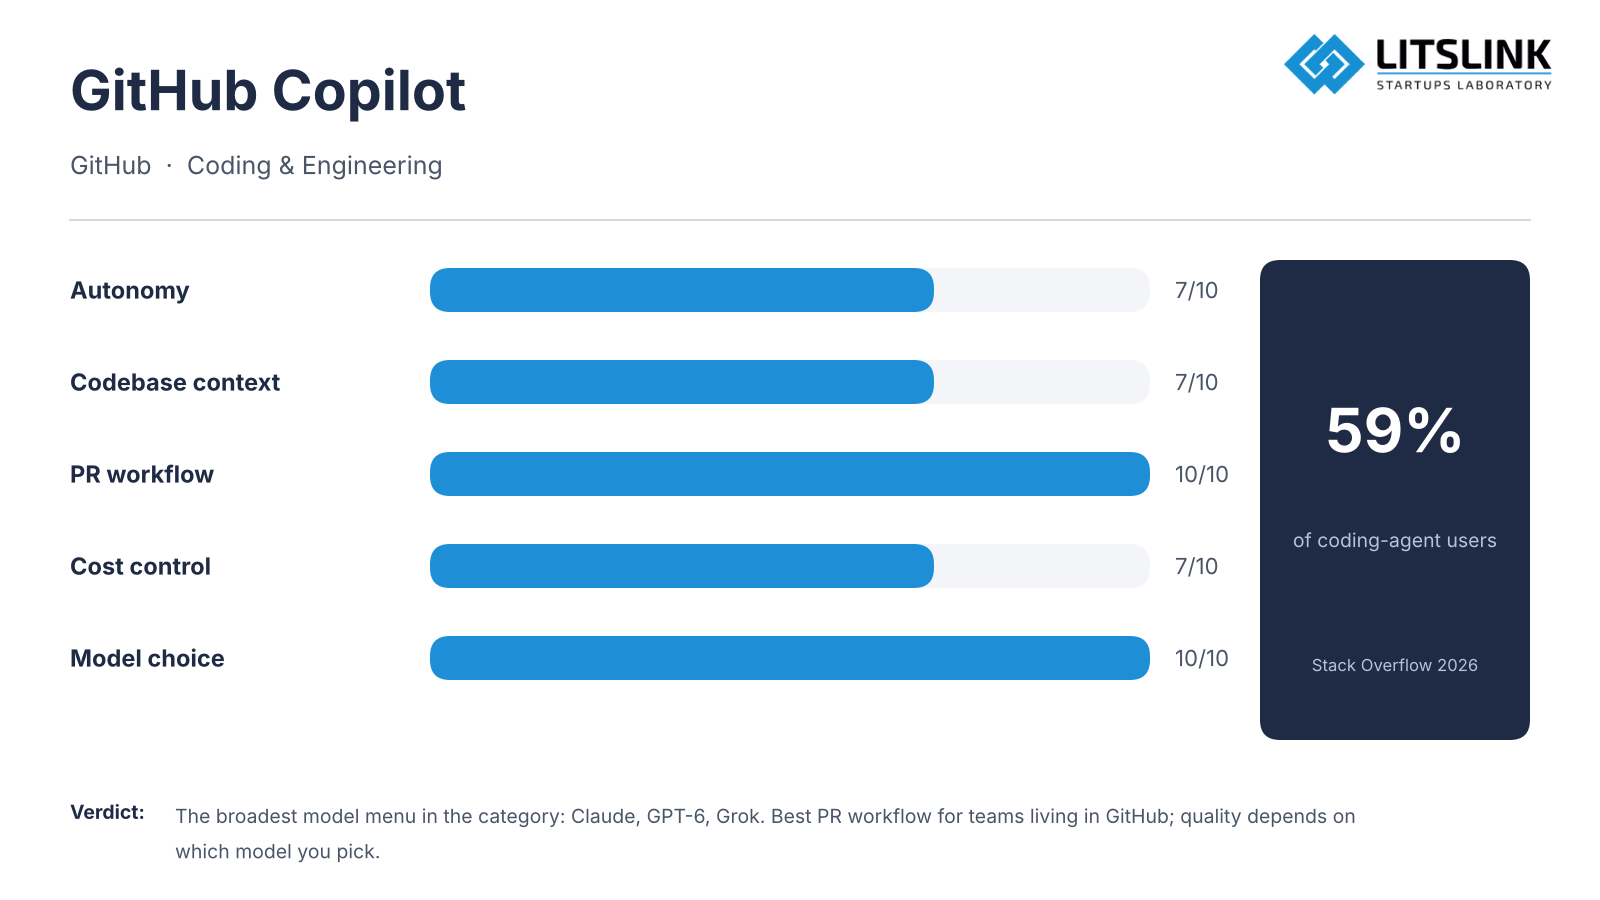
What it is: Copilot has moved on from being just autocomplete to actually being an agent that can perform workflows. It has a real understanding of ML algorithms and can therefore plan tasks, modify files and manage the PR/review cycle.
Best for:
- Teams already living in GitHub and VS Code
- PR generation; code review assistance; test generation
- “Delegate the boring parts” while keeping developers in control
Why it’s advanced in late 2026: Copilot’s cloud agent works in an isolated development environment, prepares the change, and opens the pull request for a human to review, which is a different thing from the live Agent Mode in the editor. The model menu is now the broadest in the category: Claude Opus 5.5 and Haiku 5.5, the GPT-6 family, and Grok 4.6 since August 14. The practical effect is that Copilot became a router. You pick the model per task, and 27% of organizations in the Stack Overflow survey now do exactly that.
While Copilot is a general-purpose tool, its heightened reasoning is especially effective for teams building specialized, high-stakes software, such as:
- FinTech: Streamlining secure financial software development through automated bug analysis.
- HealthTech: Accelerating the creation of compliant healthcare software solutions using parallel subagents for faster testing and validation.
The catch: Copilot is only as good as the model you select, and the default isn’t always the best one for the ticket.
8) Cursor (now part of SpaceXAI) – AI-Native IDE Workflows
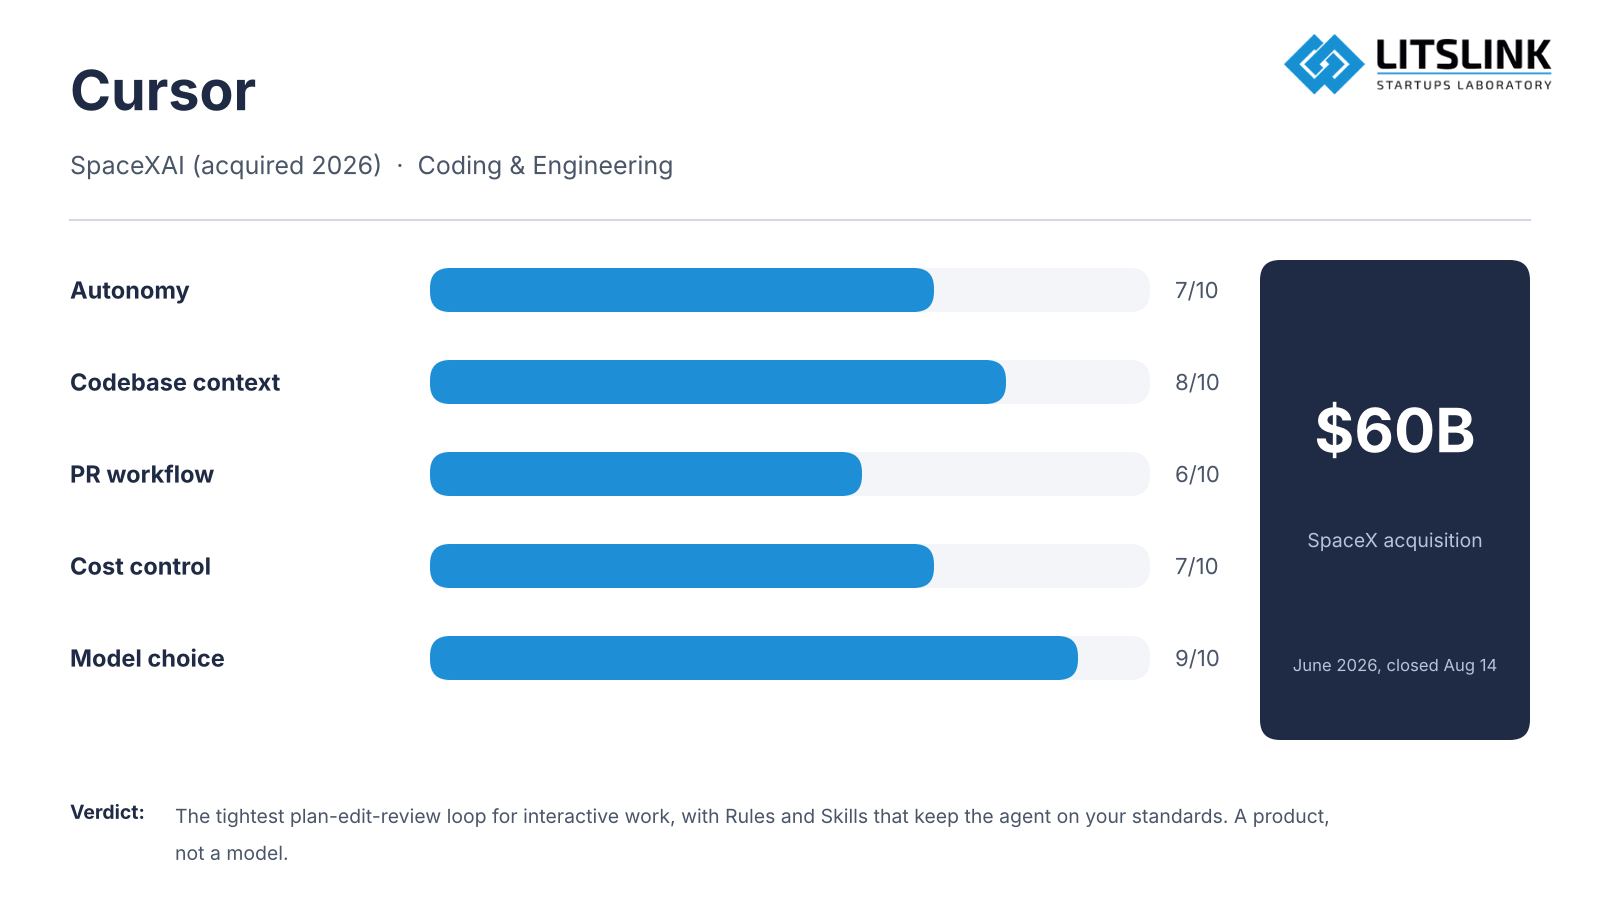
What it is: Cursor is a programming environment built around the “plan-edit-review” loop, widely regarded as the best AI software for rapid iteration. In June, SpaceX agreed to buy it for $60 billion in stock; the deal closed in August.
Best for:
- Fast iteration in medium-to-large codebases
- Developers who want a tight loop: explain, change, verify
- Organizations adopting an AI-first editor workflow
Why it’s advanced in late 2026: Cursor documents an agent loop built from models, instructions, and tools for working with a codebase. Teams define “Rules” (e.g., tech stacks) in their file system. For example, a rule might mandate the use of Tailwind CSS. The model sees these rules before writing, guaranteeing adherence to project standards. Cursor also supports “Agent Skills” via SKILL.md files, which load custom commands and hooks and turn the model from a text generator into a task executor. Grok 4.6 and 4.7 are now first-class options alongside Claude and GPT-6.
Useful Tips for Cursor Users:
- Start big features in Plan Mode to create durable artifacts.
- Use @git to include recent commits in the context window.
- Check your rules into git so everyone benefits.
The catch: Cursor is a product, not a model. Don’t put it on the same ranking as GPT-6 or Claude; put it next to Copilot and Claude Code.
9) OpenAI – Codex
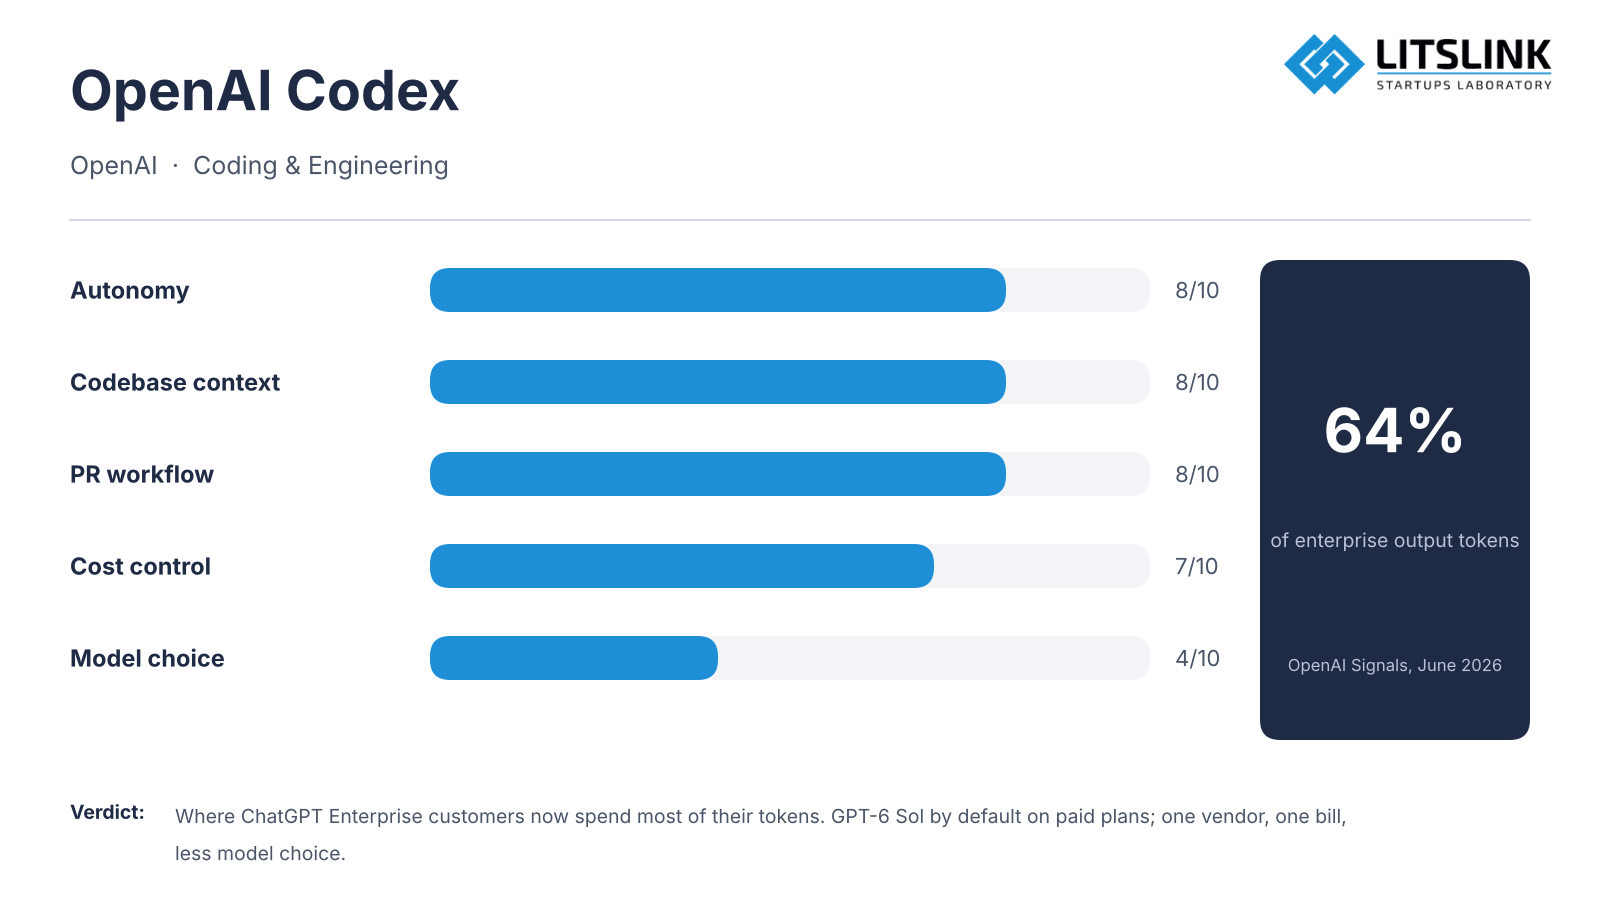
What it is: OpenAI’s agentic coding product, available in ChatGPT, the terminal, and the IDE, running GPT-6 Sol by default on paid plans.
Best for:
- Teams standardized on ChatGPT Enterprise who want one vendor
- Parallel delegated tasks in cloud sandboxes
- Bug fixing and PR review at scale
Why it’s advanced in late 2026: OpenAI’s own enterprise telemetry says Codex accounted for 64% of combined ChatGPT and Codex enterprise output tokens in June 2026, which means the median enterprise ChatGPT customer now spends more tokens on code than on chat. GPT-6 Sol scores 68.8% on DeepSWE v1.1 at max effort in OpenAI’s evaluation; Astra scores 74.1%. GPT-6 Sol and Luna rolled into Codex for Plus, Pro, Business, Enterprise, and Edu users on September 22.
The catch: The telemetry comes from OpenAI’s own customers; it’s a usage number, not a quality number. A longer agent run can be a complex workflow or a failed one.
10) Cognition – Devin
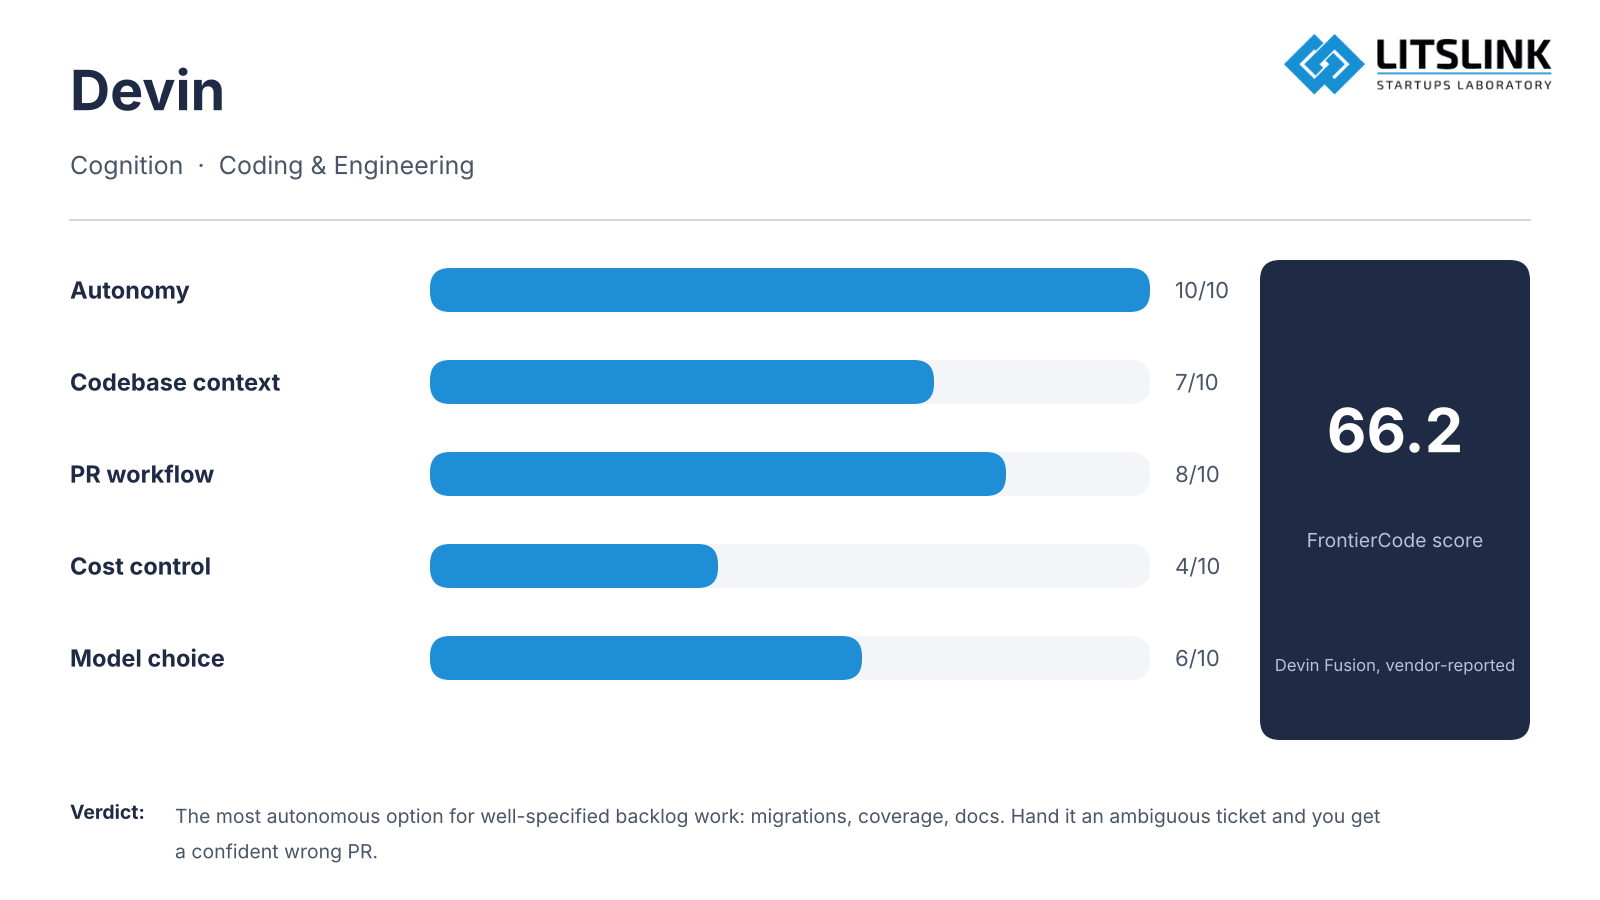
What it is: A collaborative AI teammate designed to take on engineering tasks end-to-end. It can understand a goal, plan the steps, and ship a pull request. Major firms like Infosys and Cognizant have deployed Devin at scale, using it to reinvent junior software engineering roles.
Best for:
- Backlog cleanup, including small-to-medium tickets, test coverage, and documentation updates
- Repetitive engineering tasks like migration scripts and minor refactors
- Groups that can define a clear “definition of done” or review procedures
Why it’s advanced in late 2026: Cognition’s “Devin Review” is used to help engineers triage complex PRs by augmenting their attention. Devin Fusion (the multi-model mode) has Claude Opus 5.5 as the lead and Haiku 5.5 as the sidekick and has a FrontierCode score of 66.2 in Cognition’s reporting. Devin’s documented role is explicitly to do the work with clear completion criteria in mind: migrations, issue fixing, test coverage.
The catch: Devin is the world’s strongest AI for backlog cleanup when the backlog is well specified. Hand it an ambiguous ticket and you’ll get a confident, wrong PR by morning.
Building AI-powered software or evaluating coding tools for your stack? LITSLINK engineers have worked with advanced AI models on real client projects. Hire vetted AI developers →
Field 3: Generative Media (Image, Video, Audio)
A note on what’s not in the list. Sora 2 came out as the leader in the spring. OpenAI shut down the Sora app on April 26 and the API on September 24 2026 so it’s no longer in the list. If your pipeline is still calling it that’s an incident waiting to happen.
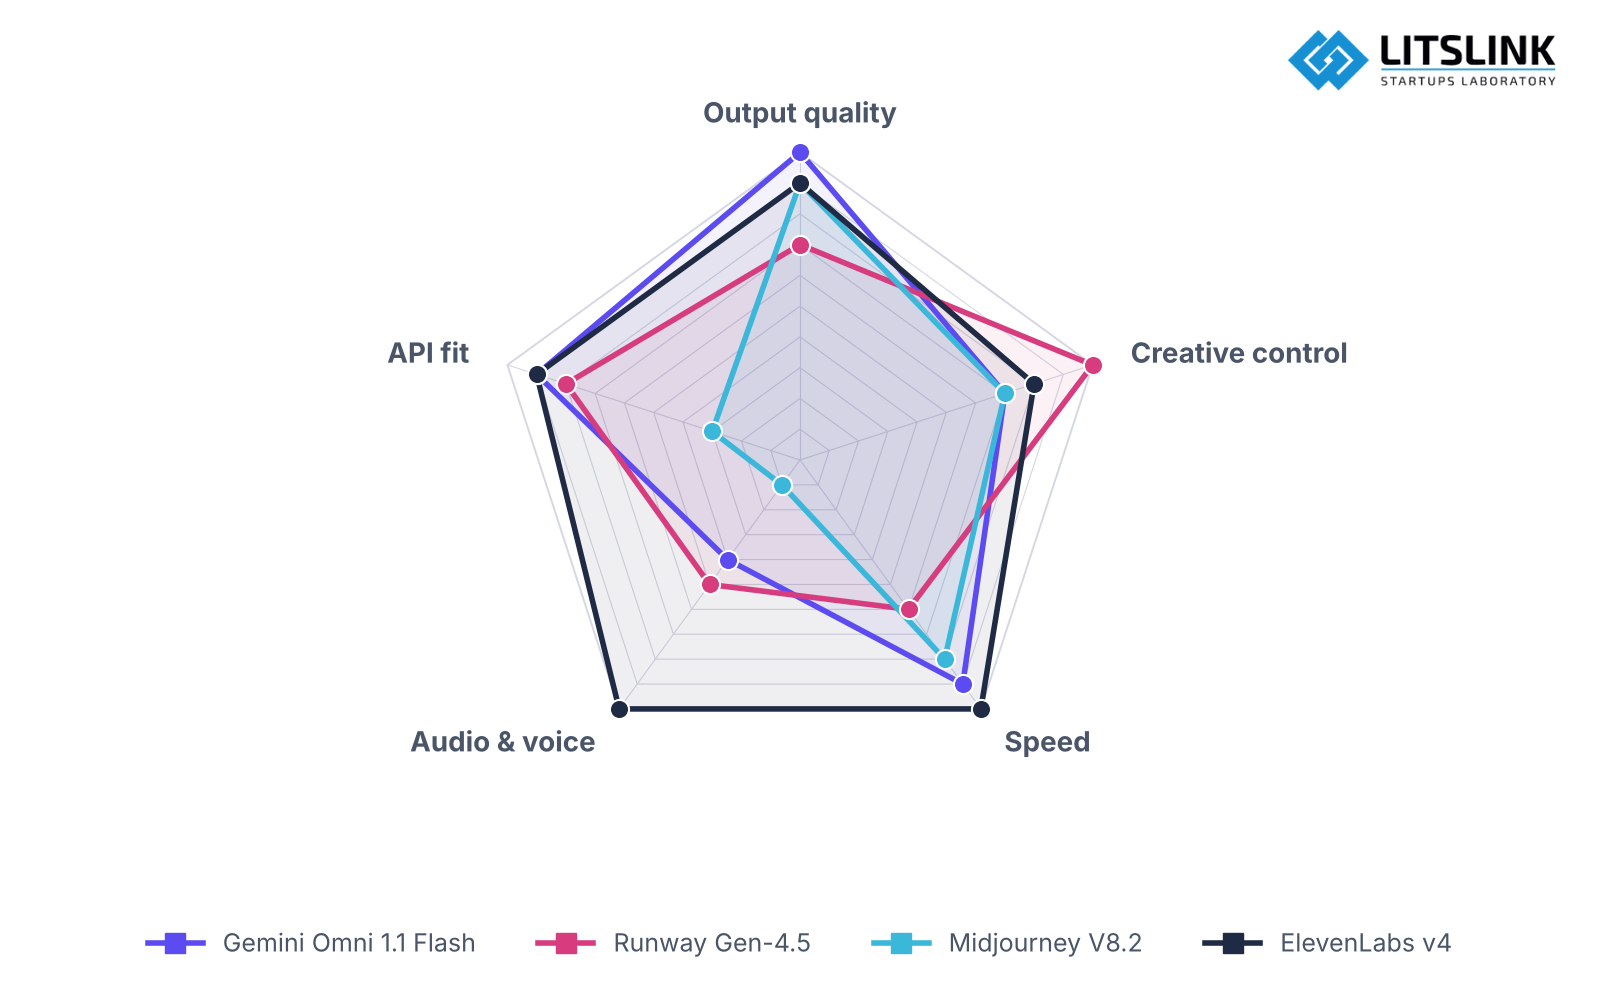
Four media systems on five axes. LITSLINK editorial assessment, 1–10 scale, October 2026. Output quality is judged within each system’s own medium.
11) Google – Gemini Omni 1.1 Flash (with Veo 3.1)
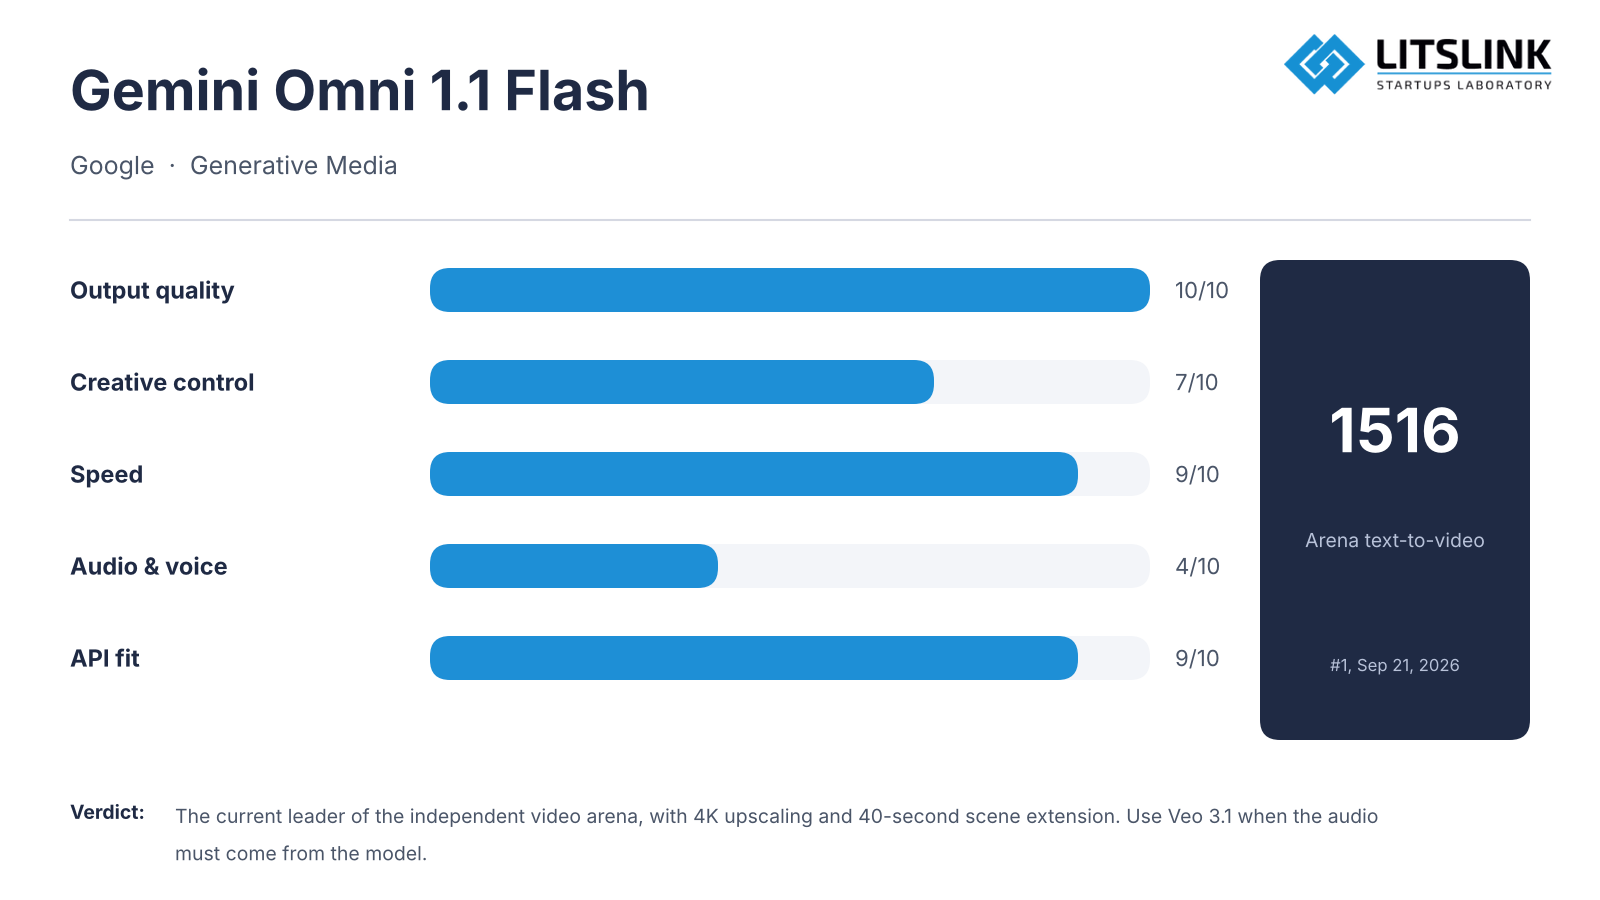
What it is: Google’s video generation model, released August 27, and the current leader of the independent text-to-video arena. Veo 3.1 remains the option for synchronized audio.
Best for:
- Marketing content prototypes, concept videos, storyboarding
- Short-form creative exploration with high iteration
- Teams that need fast “draft-to-visual” workflows at 360p before committing to 4K
Why it’s advanced in late 2026: Gemini Omni 1.1 Flash sits at 1516 on the Arena text-to-video leaderboard, ahead of ByteDance’s Seedance 2.0 (1479), Alibaba’s Wan 3.0 (1476), and MiniMax H3 (1460). It takes text, images, and video as input, generates 3-to-10-second clips, extends them in 10-second steps up to 40 seconds, interpolates between a first and last frame, and upscales to 1080p and 4K. Google says 360p drafts run up to 60% faster at a third of the cost of 720p, which is the feature that matters for iteration. Veo 3.1 with audio sits at 1364 (#12), still the pick when the soundtrack has to come out of the same model.
The catch: The top of the video leaderboard is the most volatile table in this article; three of the top eight entries are marked preliminary. Re-check before you build a pipeline around any of them.
12) Runway Gen-4.5 (Runway)
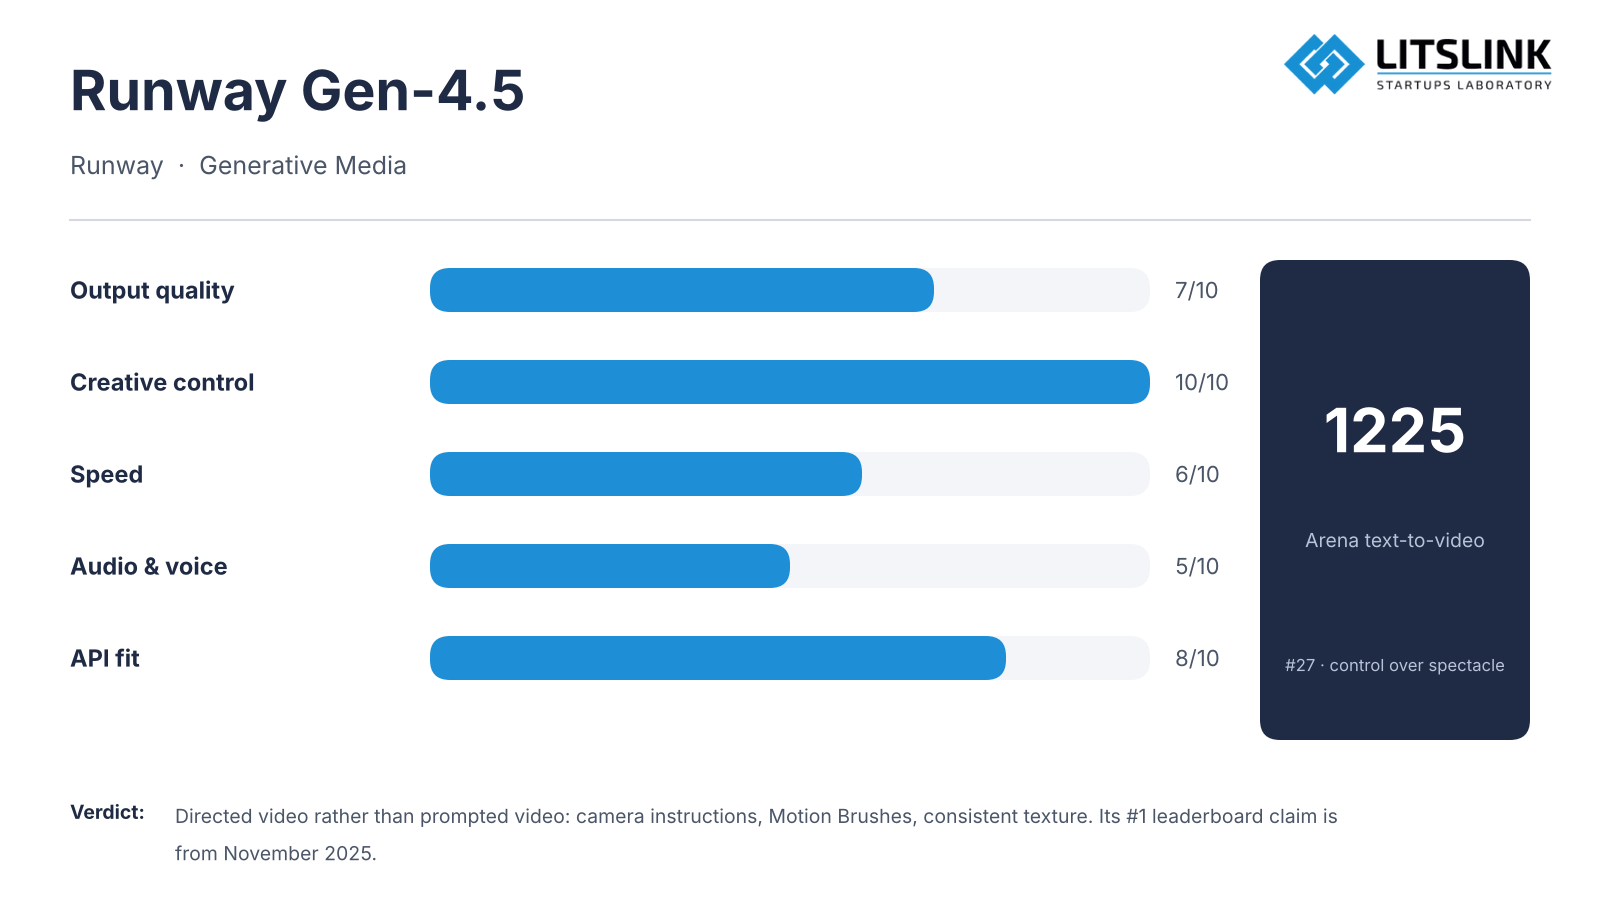
What it is: A high-end video generation model positioned around motion quality, fidelity, and creative control. Runway Gen-4.5 is the tool for directed video rather than prompted video.
Best for:
- Creative teams that need cinematic video generation with more control knobs
- Rapid pre-production, including visual ideation, style exploration, and short sequences
- Agencies building repeatable workflows for clients
Why it’s advanced in late 2026: Gen-4.5 was the leader on the Artificial Analysis text-to-video leaderboard at launch (December 2025). It’s now at 1225 (#27) on the Arena board which sounds like a drop and is actually a shift in what the board is rewarding. Runway’s strength is in its granular directorial control (via very detailed camera instructions), consistent skin texture, layered objects and dynamic illumination transitions. The blind preference voters will reward the spectacle; the director will reward the shot that fits the storyboard.
Information for Runway:
- Use Gen-4.5 for the ‘short and sharp’ hero shots in the social ads.
- Use ‘Motion Brushes’ to paint areas of movement.
- Generate high impact transitions for the emotional beats in a brand film.
The catch: Its launch leaderboard claim is dated November 2025. Treat it as history, not a current ranking.
13) Midjourney V8.2 (Midjourney)
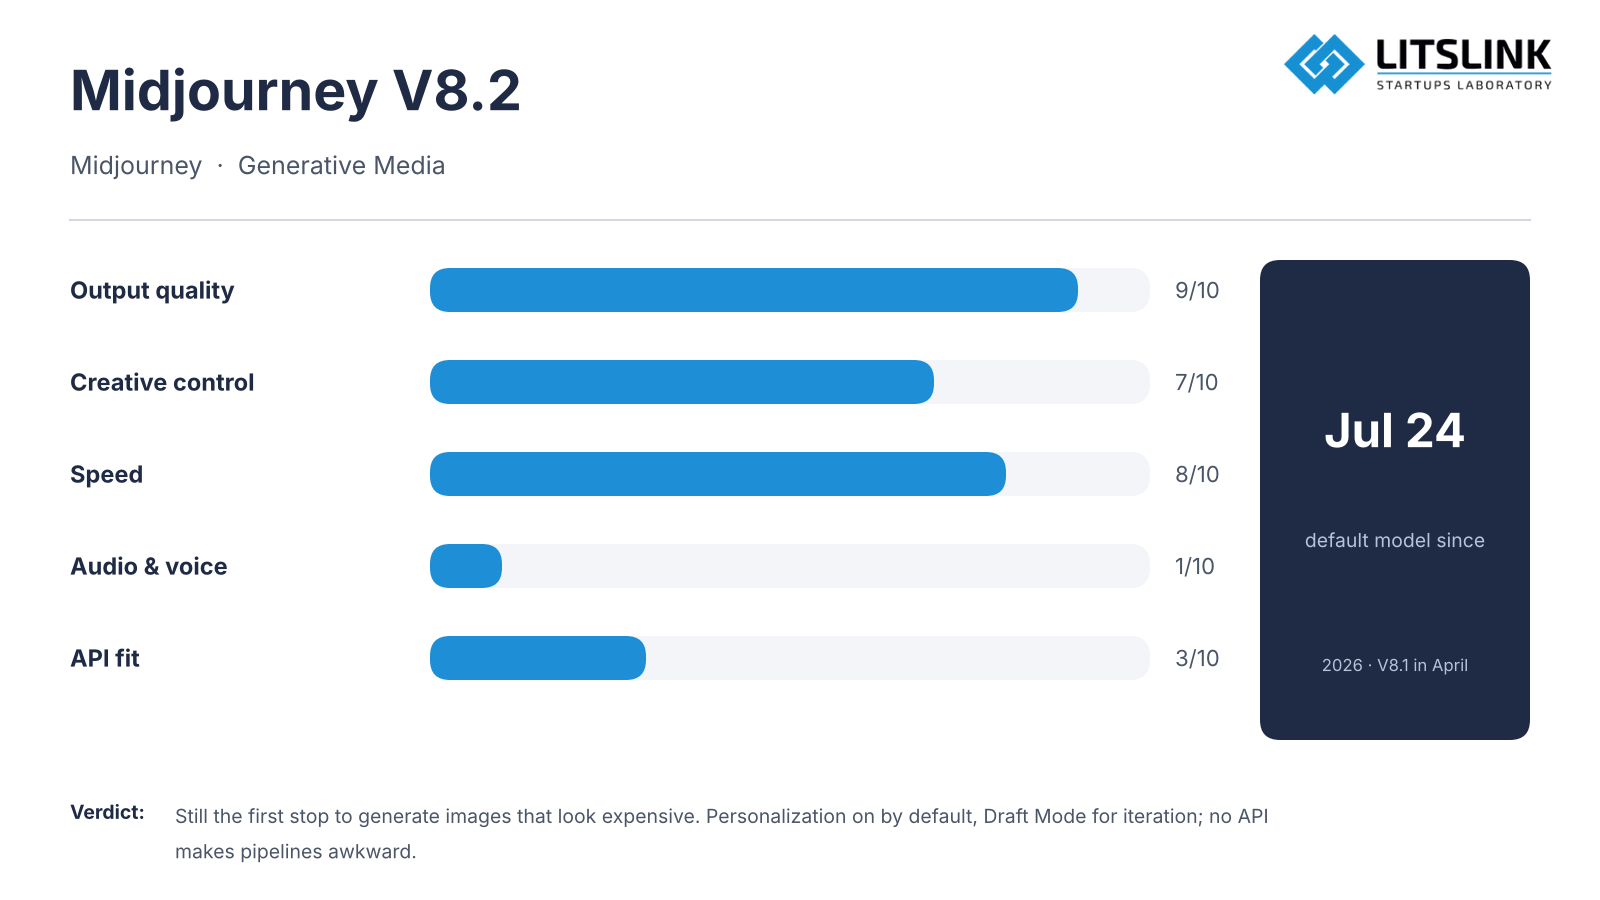
What it is: An image generation system known for high aesthetic quality and strong creative outputs.
Best for:
- Brand and marketing visuals, including concept art, product scenes, and style exploration
- Fast visual ideation for UI/UX and campaigns
- Creating a “visual direction” quickly, before production
Why it’s advanced in late 2026: Midjourney V8.2 has been the default model since July 24, 2026, following V8.1 in April. Personalization is on by default, so the model understands what you find beautiful. Draft Mode gives you rapid, low-cost iteration before a full render, and “Omni Reference” keeps logos and specific objects consistent across a campaign. For the “generate images that look like they cost money” job, it’s still the one most designers reach for first.
The catch: “Best artistic quality” is a taste judgment, not a benchmark, and Midjourney’s no-API, Discord-and-web model makes it harder to put in a pipeline than Google’s or OpenAI’s image endpoints.
14) ElevenLabs – Eleven v4 and v4 Turbo (AI Voice)
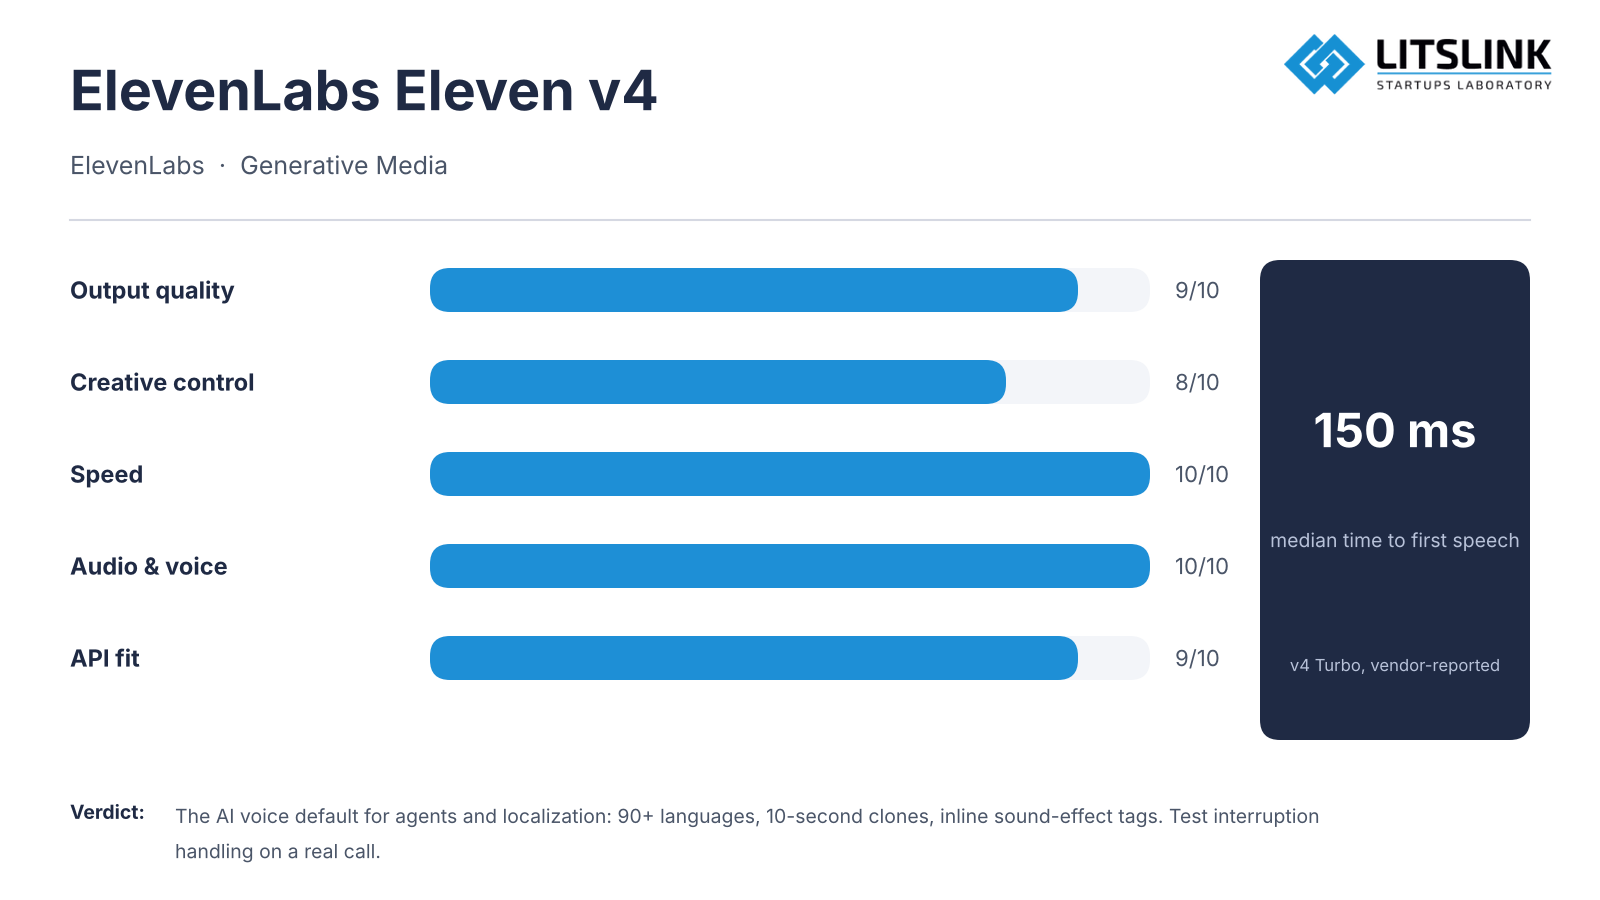
What it is: The text-to-speech and voice-agent models that most AI voice products run on, released September 28, 2026.
Best for:
- Voice agents for support and sales, where turn-taking latency decides whether the call feels human
- Multi-speaker dialogue, audiobooks, and localized video voiceover across 90+ languages
- Products that need a consistent cloned brand voice with verified consent
Why it’s advanced in late 2026: Eleven v4 reads the mood, pacing and emotion from context and takes inline tags such as [laughs] or [light rain] to provide the appropriate sound effect within the speech. ElevenLabs reports v4 Turbo has a median time to first speech of around 150ms over WebSocket (compared to 262 to 814ms for the alternatives it tested) and is preferred by around 75% of listeners in blind tests. Instant voice clones require 10 seconds of audio. The alternatives are real: OpenAI’s GPT-Realtime-2 (May 2026, $32 / $64 per 1M audio tokens, 5 reasoning levels, 128K context) and Google’s Gemini 3.8 Live which streams audio as an async function call runs.
The catch: of course voice quality is the easy bit. The difficult bits are how you handle interruption, how you say your product names and what you do when the CRM lookup times out. None of the vendor benchmarks really cover those. You have to test it in a real call in real time.
Need generative media built into a product?
We help teams build and deliver AI-powered media workflows that work at scale.
Field 4: Agents & Automation
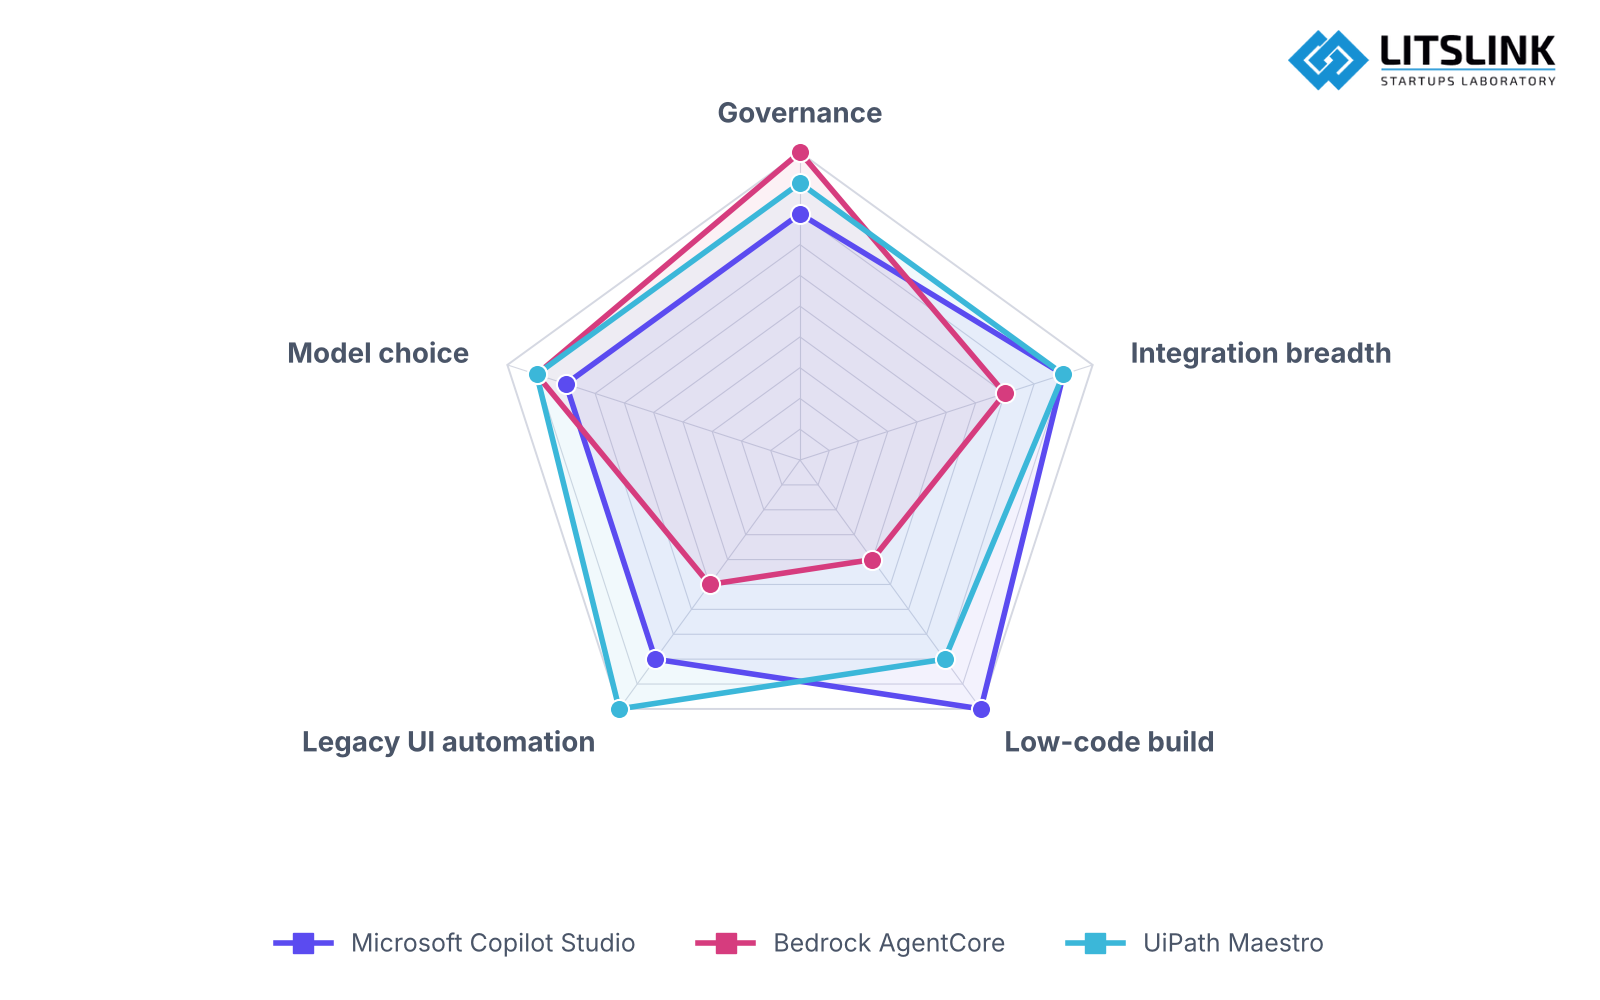
Three agent platforms on five axes. LITSLINK editorial assessment, 1–10 scale, October 2026, based on documented features rather than measured performance.
15) Microsoft – Microsoft 365 Copilot and Copilot Studio
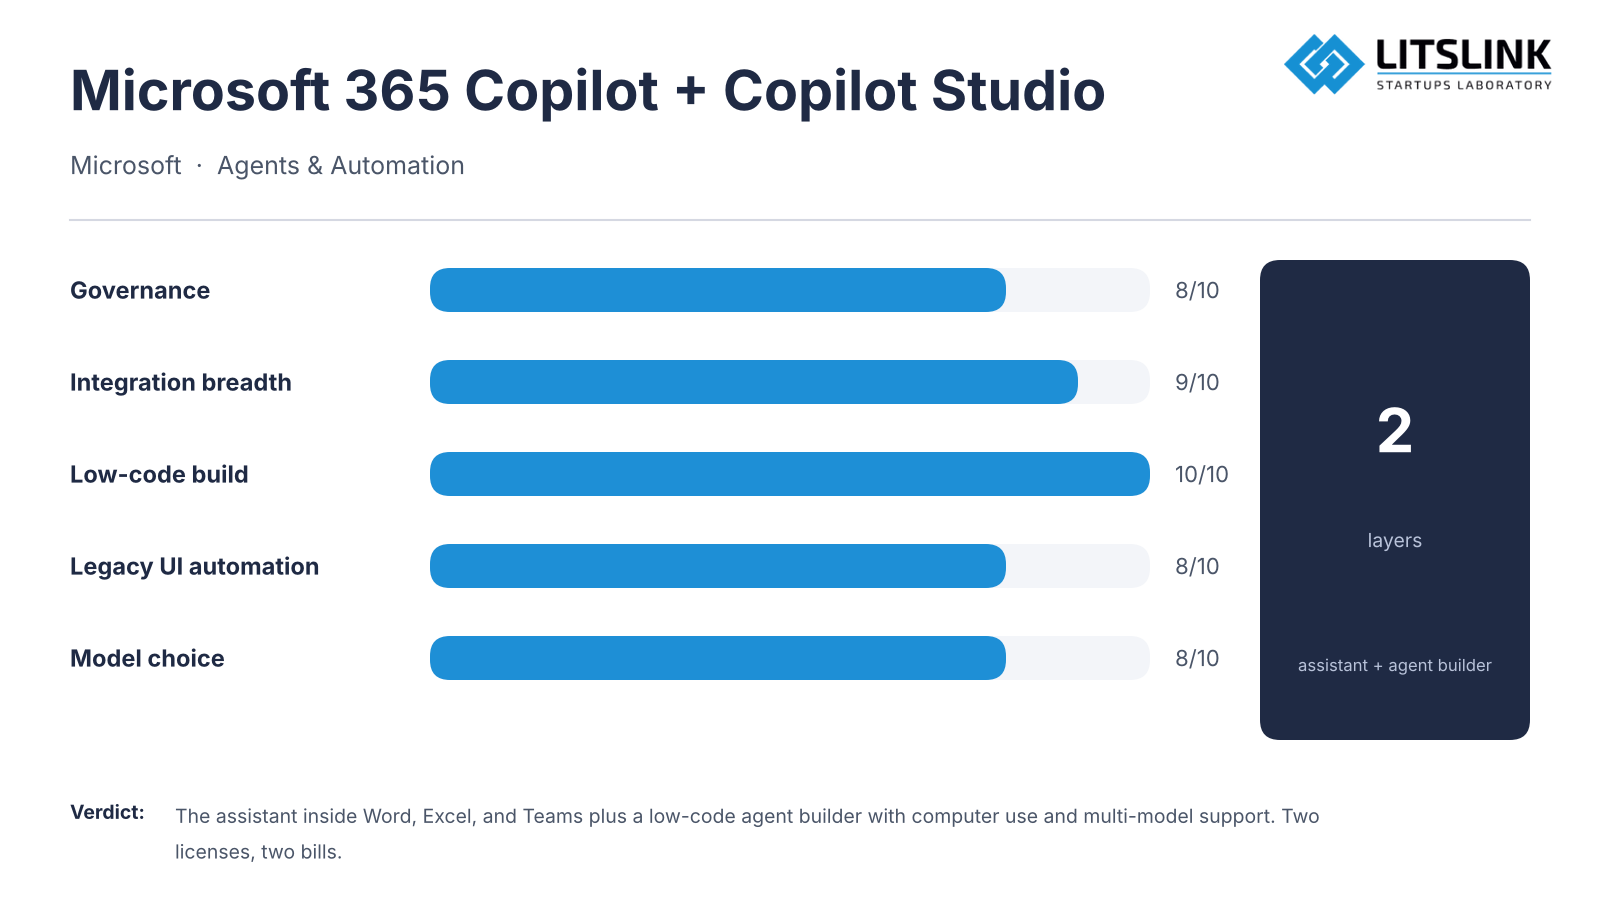
What it is: Two layers that get confused for each other. Microsoft 365 Copilot is the assistant inside Word, Excel, PowerPoint, Outlook, and Teams, drawing on organizational context through Microsoft Graph. Copilot Studio is the low-code platform for building and governing your own agents.
Best for:
- Enterprises building internal AI for support, IT ops, HR, and finance operations
- “AI plus governance” scenarios, including logs, admin control, and lifecycle management
- Automations operating without modern APIs
Why it’s advanced in late 2026: the Copilot Studio feature page now has “computer use” as an option which enables agents to interact with Windows apps just the way a human would (clicking buttons, typing into legacy systems that have no API). It also has real time voice agents, agent evaluation tooling and multi-model support (including Anthropic models as well as the GPT family) which would have been absolutely impossible in 2024. You can take natural language intent and turn it into automation. A sales or HR lead can build an agent that owns the entire onboarding workflow end to end without any developer.
Microsoft emphasizes that human-AI teams are growing globally. Copilot Studio provides tools enabling tracking agent ROI and performance and protects enterprise data under Zero Trust principles.
The catch: The Microsoft 365 Copilot license and the Copilot Studio consumption bill are separate line items, and the second one is the one finance asks about in Q2.
16) Amazon Web Services – Amazon Bedrock AgentCore
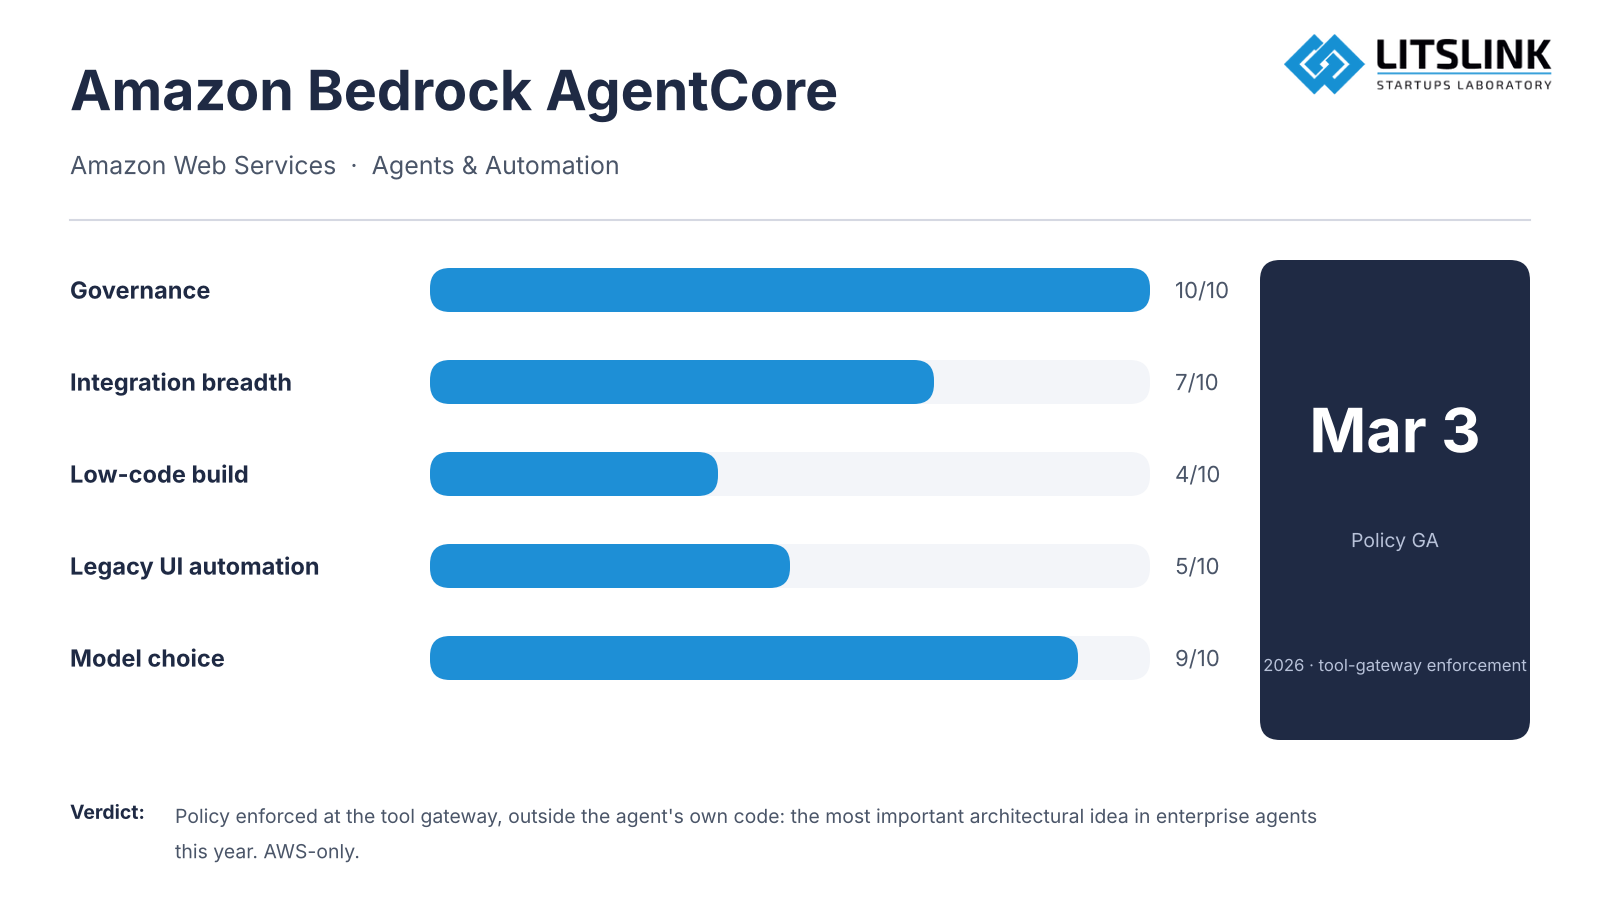
What it is: A managed service to build AI agents that will go on to orchestrate foundation models, call APIs and use knowledge bases with the infrastructure, memory and sandboxing all being provided by AWS.
Best for:
- Teams building AI products in AWS
- Workflows that require tool calling, plus RAG, plus strong controls
- Scaling from prototype to production with security posture and ops tooling
Why it’s advanced in late 2026: AgentCore has managed memory for personalised conversations and sandboxed code execution. The feature that really matters has gone GA as of March 3rd 2026: Policy in Amazon Bedrock AgentCore which enforces policies at the tool gateway (i.e. outside of the agent’s own code). You can have a policy that says “block all refunds over $1k” and the model has no way of getting around that because it never sees the gate. That’s the one key architectural idea that’s going to be important in enterprise agents this year.
AgentCore is perfect for organizations looking to reduce their operational burden. It takes care of the infrastructure, security and scaling so the developers can concentrate on the bit that’s actually unique to them.
The catch: It’s AWS. If your data lives in Google Cloud or Azure, the connection cost eats the convenience.
17) UiPath – UiPath Maestro (Agent Builder + Autopilot)
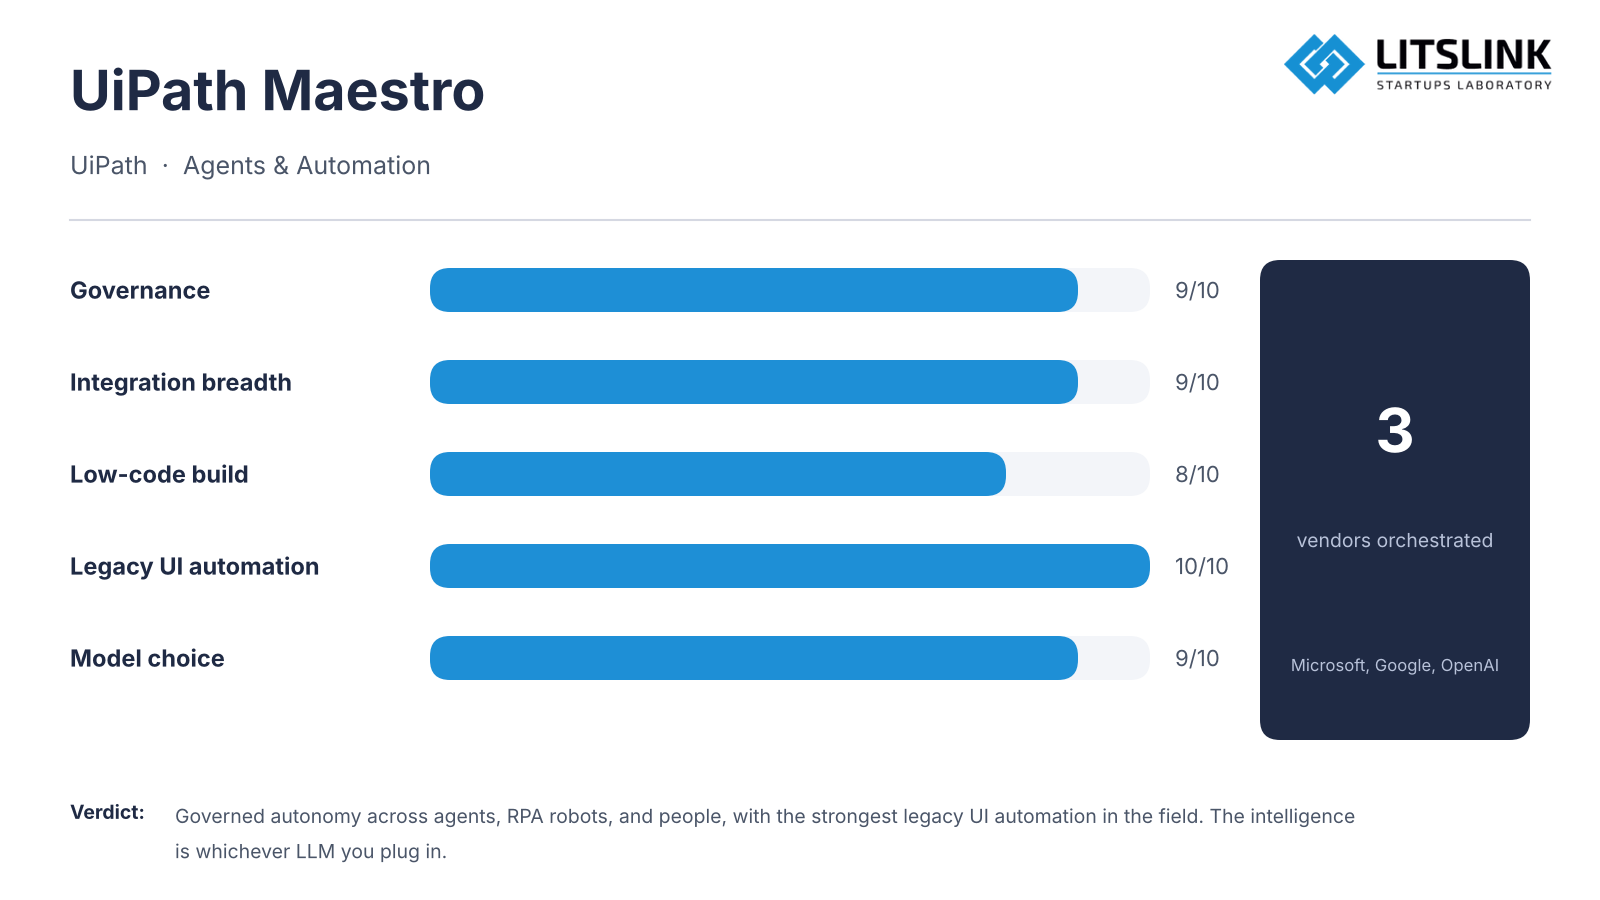
What it is: AI-powered automation across business workflows. UiPath has repositioned itself as the orchestration layer that coordinates agents, RPA robots, and people in one process.
Best for:
- Enterprise process automation with strong governance needs
- Document-heavy operations like claims, underwriting, onboarding, and procurement
- Orchestrating “AI plus automation plus humans” across end-to-end processes
Why it’s advanced in late 2026: Maestro is all about combining AI agents with RPA building blocks within a ‘governed autonomy’ framework so that decisions are transparent and policy-compliant. ScreenPlay is their natural language UI automation capability, which can understand the intent and then carry out multi-step plans. The WorkFusion acquisition has given them industry-specific agents that have been pre-trained for financial crime compliance. It can run systems from Microsoft, Google, and OpenAI and cross-vendor orchestration is the quiet trend of 2026. ‘Agentic Testing’ is the feature that automatically fixes broken tests and that’s what keeps enterprise automation reliable at scale.
The catch: Maestro is an orchestration and governance win, not a smarter base model. The intelligence still comes from whichever LLM you plug in.
Field 5: Open-Weight and Self-Hosted Models
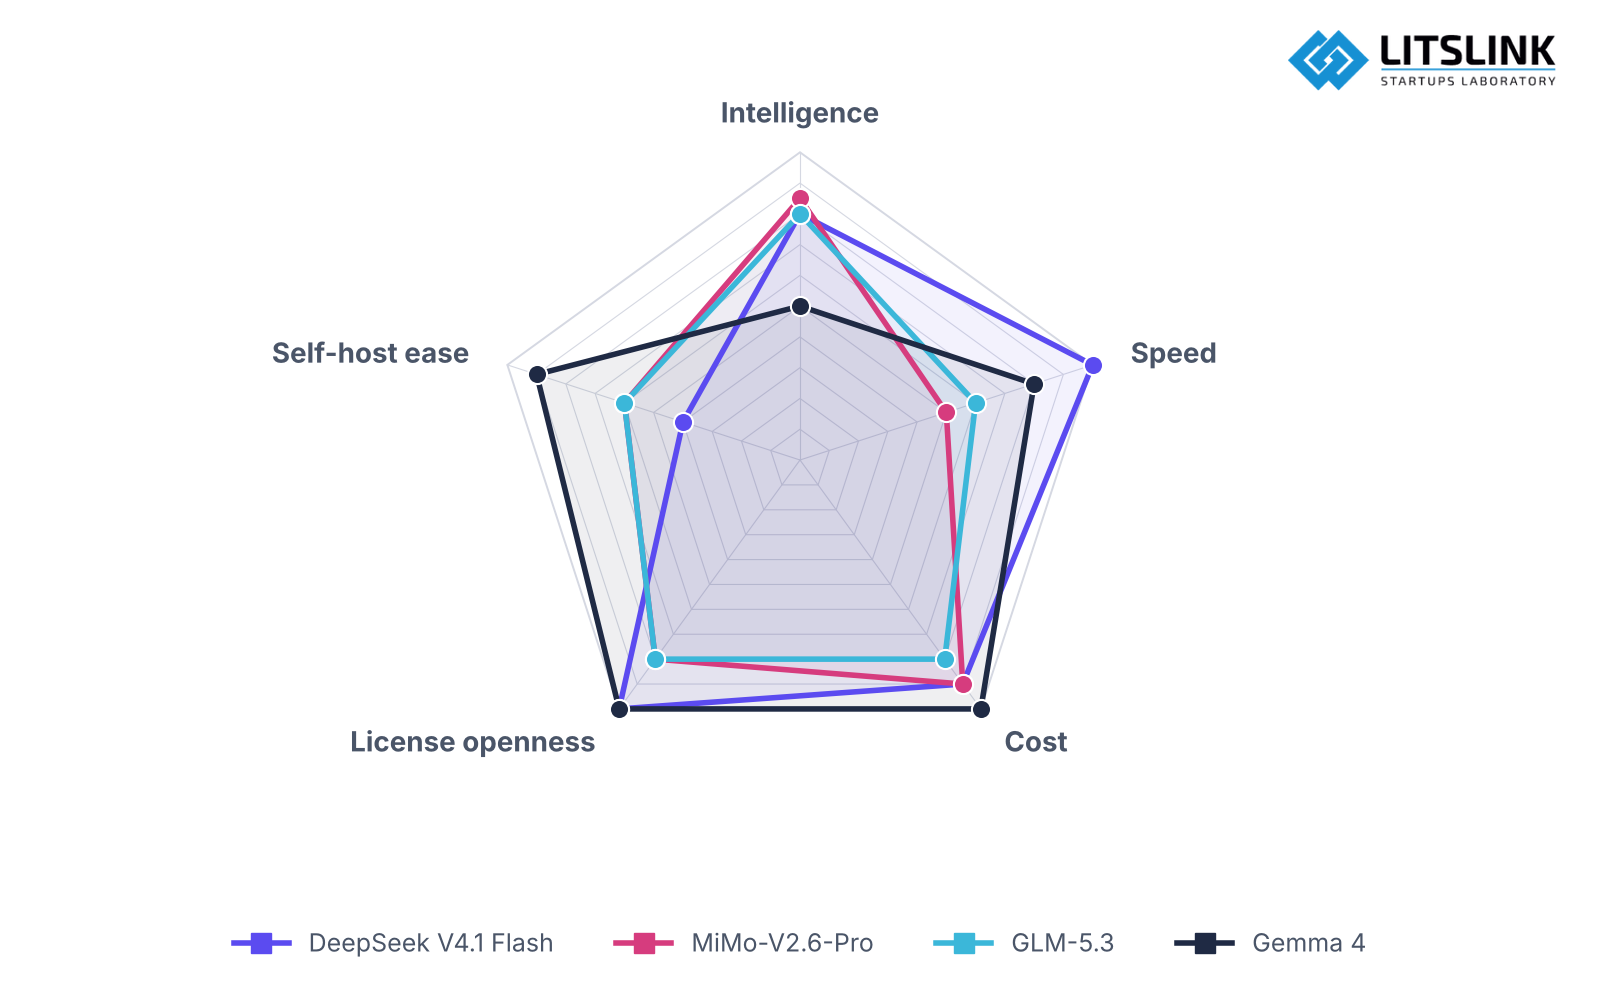
Four open-weight models on five axes. LITSLINK editorial assessment, 1–10 scale, October 2026; Intelligence and Speed follow the Artificial Analysis index, the rest are judgment calls.
18) DeepSeek V4.1 Flash, and the open-weight pack behind it
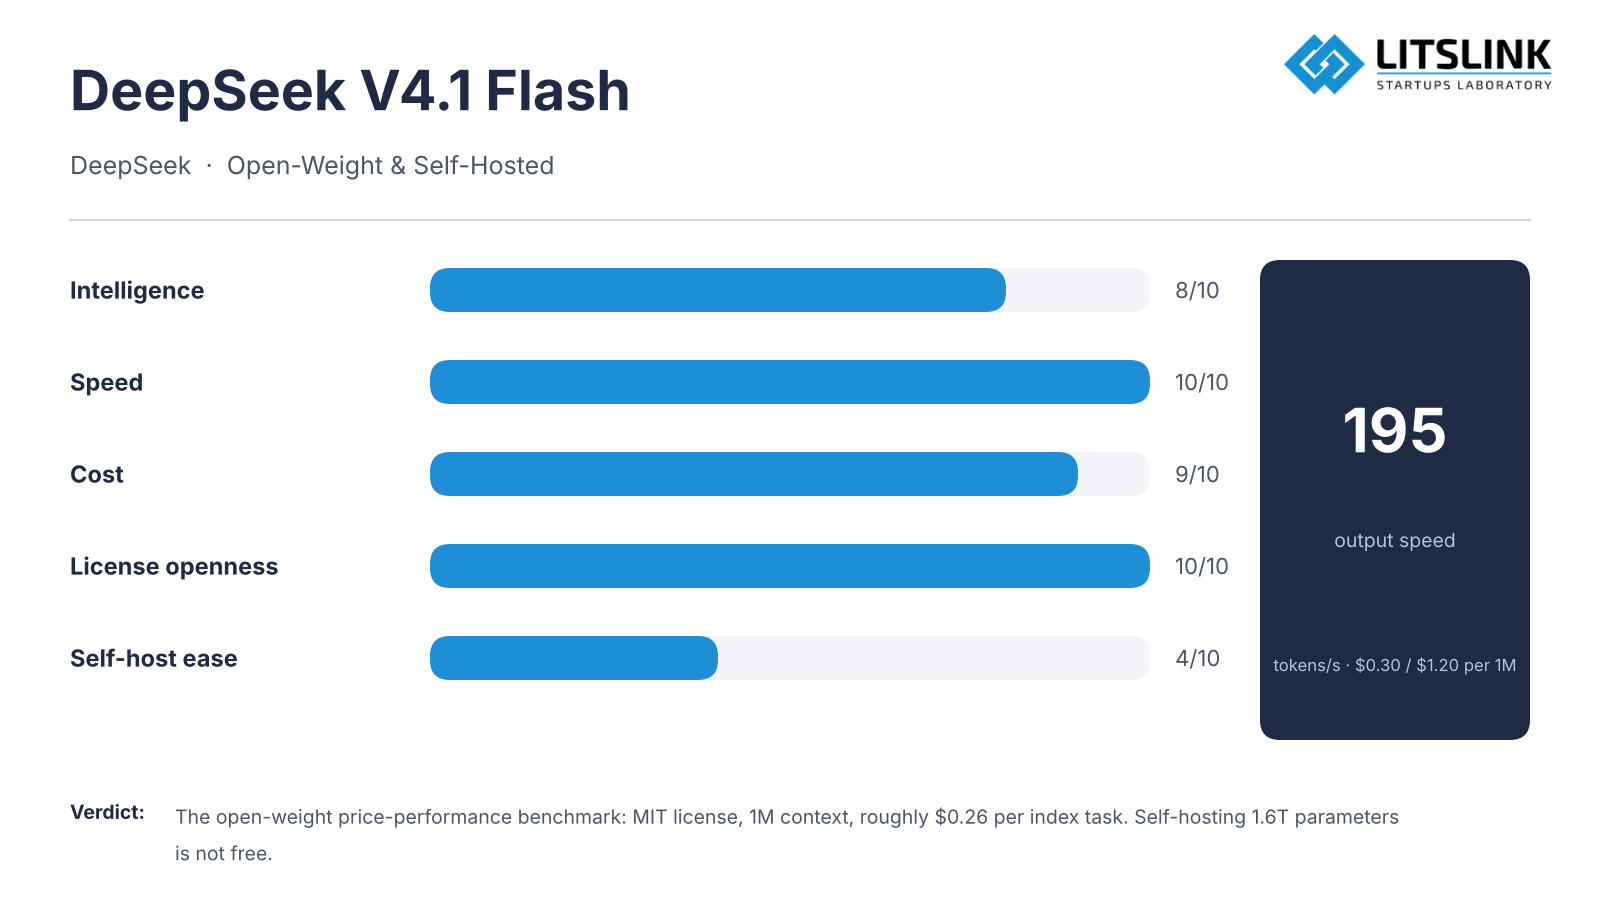
What it is: The models you can download, fine-tune, and self-host. A year ago this was an honorable mention. In October 2026, four of them sit in the top 15 of the composite index.
Best for:
- Teams running high-volume inference who treat frontier API pricing as a fixed cost of doing business and want it to stop being one
- Regulated workloads that cannot leave your own infrastructure
- Fine-tuning on a proprietary corpus where a hosted model’s terms get in the way
Why it’s advanced in late 2026: DeepSeek V4 landed on April 24 under an MIT license: V4-Pro with 1.6 trillion total and 49 billion active parameters and a 1M-token window. The V4.1 Flash revision of October 17 scores 45 on the Intelligence Index at 195 tokens per second and $0.30 / $1.20 per 1M tokens at peak, half that off-peak, which puts it at roughly $0.26 per index task against $5.98 for Opus 5.5. Around it: Xiaomi’s MiMo-V2.6-Pro is the top open-weight model on the leaderboard at 46, Zhipu’s GLM-5.3 scores 45, Moonshot’s Kimi K3.1 Pro scores 55 as an API model, and Google moved Gemma 4 to Apache 2.0 in April. Stanford’s AI Index 2026 measured the gap between the top US and top Chinese model at 2.7% on Arena as of March. It has not widened since.
The catch: Free weights aren’t free operations. Self-hosting a 1.6T parameter model means you’re looking at GPUs, an inference stack, a security review, and an update plan every time a new revision comes out (DeepSeek ships a new revision roughly every 6 weeks). Establish a prompt and retrieval baseline on a hosted model first and only fine-tune when that baseline fails on your data. For US enterprises, there’s also a procurement discussion to be had about where the model was trained, irrespective of what the benchmarks tell you.
Best AI for Coding, Research, Business, Automation, and Multimodal Tasks
The honest version of “which AI is the best” is a lookup table keyed on the job. Here it is, with the reasoning, because a recommendation without the reasoning expires in a quarter.
Best AI for coding: Claude for the agent, your own repo for the test
For writing code across an entire codebase, the pick is Claude Sonnet 5.5 or Opus 5.5 inside Claude Code, and the evidence is unusually consistent: 66% of agent users in the Stack Overflow survey, the top CursorBench and Terminal-Bench numbers in Anthropic’s harness, a tie with GPT-6 Astra in Artificial Analysis’ harness, and GitHub reporting the fewest tokens and steps per task in Copilot. The runner-up is GPT-6 Astra for the hardest single problems and Sol for volume.
The catch is that all those figures are single-pass benchmarks or surveys. In that same survey, developers use AI mainly for code generation in well-understood areas (67%) and for debugging (61%). Only 20% of them are using it for production operations. The right test is the one that Cognition, GitHub and we all agree on: same repos, same tickets, same acceptance tests and you record whether the patch passes, whether a maintainer accepts it, the review minutes and any new defects. You keep the failed runs. A convincing demo is not the point.
Best AI for research: the tool that cites, not the model that scores
For deep research with sources you can check, the strongest model result belongs to GPT-6 Astra at 91.5% on BrowseComp (OpenAI’s number). The strongest product behavior we’ve seen belongs to Claude Opus 5.5, which in Anthropic’s internal test produced 16 of 18 long research reports with no invented figures. Perplexity’s Research mode runs dozens of searches and reads hundreds of sources in about three minutes, picks its own models, and limits free users on a rolling window. Gemini’s Deep Research is the pick when the sources are in your Drive.
Retrieval is not verification. A citation is useful only when the referenced passage supports the exact claim, and the thing to check in any research tool is what it does when a search returns nothing. The good ones say so. The bad ones write a plausible paragraph.
Best AI for business: whichever one is already inside your documents
For a Google shop, Gemini 4 Argon in Workspace reads your Drive, Docs, Gmail, and Meet transcripts without an integration project, and it’s included in the Google AI Pro plan. For a Microsoft shop, Microsoft 365 Copilot does the same across Word, Excel, Outlook, and Teams through Microsoft Graph. For everyone else, ChatGPT with GPT-6 Sol (plus custom GPTs for repeatable internal tasks) or Claude with its Excel and PowerPoint integrations.
I’d argue against the instinct to go for the most intelligent model. A 5 point difference on the Intelligence Index is completely invisible to a sales manager who just wants last quarter’s numbers in brief form. It’s all about data access, the permissions and the data control clauses in the contract.
Best AI for automation and AI agents: the one with the policy gate
For agents that are actually taking actions in real systems, the model is far less important than the control layer around it. Claude Sonnet 5.5 comes out on top in the computer use metric (83.9% on OSWorld 2.1 in Anthropic’s tests); GPT-6 Astra comes out on top in the AutomationBench score (41.4%). Those numbers tell the same story: the best agent in the world still fails about 3 out of 5 business tasks. The platform choice is therefore about recovery. Bedrock AgentCore has the policy at the tool gateway, Copilot Studio has it in the admin controls and the evals and UiPath Maestro has it in the process orchestration with a human step where you’d want one.
Here’s the control flow we run every production agent through, synthesized from AgentCore’s policy model and our own deployments:
- Define the goal, the data that is allowed, and a testable condition for completion.
- Plan and read: get the authorized evidence and put together a bounded action plan.
- Check the policy: check the scope and the permissions; get approval where required.
- Execute via scoped APIs or a sandbox. Forbidden actions are blocked rather than just discouraged.
- Verify: read back the state, run the tests and compare against the completion condition.
- Log and recover: record the evidence and the cost; retry safely or escalate to a human.
Measure the intervention rate against the automation rate. An agent which automates 80% of a workflow and silently corrupts 2% of it is a net loss.
Best AI for multimodal tasks: read with Argon, make with specialists
“Multimodal” is doing two jobs in vendor copy, and only one of them is usually true. For reading mixed media in one prompt (a PDF, a call recording, a product video), Gemini 4 Argon is the only frontier model with native text, image, video, audio, and PDF input, and it still outputs text only. GPT-6 and Claude take text and images. For making media, you go to specialists: Gemini Omni 1.1 Flash for video, Midjourney V8.2 to generate images, ElevenLabs v4 for AI voice, and Veo 3.1 when the audio has to come out of the same model as the picture. No single model does all of it in real time, whatever the keynote implied.
Single model or multiple models? Start with one, earn the second
Routing is now the norm. 27% of the organizations in the Stack Overflow survey use different models for different work, 38% have usage caps and 25% of individual developers will go with a cheaper model if they can. The architecture that keeps cropping up in 2026 is the frontier planner (Opus 5.5, Astra, Argon) with a Haiku 5.5 or Luna class subagent doing the retrieval and summarisation at $0.10 per 1M input tokens. Cognition’s Devin Fusion is the productized version of that architecture.
My advice is rather pedestrian. Establish a single model baseline with assessed quality first. Add in a cheaper model only for a task segment where it clears the same quality floor. Log every handoff and escalate the ambiguous cases. The cost of routing the failures is going to be more than the cost of the tokens you save.
How AI Changed in 2026: A Month-by-Month Timeline of New Models
This is the part of the guide we update rather than rewrite. Newest first; “announced,” “preview,” and “available” are different states and are labeled as such. Last verified: Oct 25, 2026.
| Oct 23 | Kimi K3.1 Pro (Moonshot AI) | Top non-US model on the composite at 55 | Artificial Analysis |
| Oct 13 | Gemini 4 Argon in the Gemini app for AI Pro and Ultra | Human-preference leader reaches subscribers | |
| Oct 12 | Meta Muse Wonder and Wonder Full | Meta’s first frontier model, and its first without open weights | Meta |
| Oct 7 | Claude Haiku 5.5 at $0.10 / $0.50; GPT-6 Instant in ChatGPT | Budget tier with a 1M window and adjustable effort | Anthropic |
| Oct 6 | Stack Overflow 2026 Developer Survey | Claude Code 66%, Copilot 59%; 73% of AI users use it daily | Stack Overflow |
| Sep 30 | Gemini 4 Argon announced, $2 / $10 intro pricing to Nov 30 | 1M unified context; Fairwind trusted-tester rollout | |
| Sep 29 | GPT-6.1 Sol (OpenAI DevDay) | Near-Astra performance at $2 / $10 | OpenAI docs |
| Sep 28 | Claude Sonnet 5.5; ElevenLabs Eleven v4 | Sonnet 30%+ faster and up to 30% cheaper than Sonnet 5 | Anthropic release notes; ElevenLabs |
| Sep 24 | Sora API shut down | Remove Sora from every video shortlist | OpenAI |
| Sep 22 | Claude Opus 5.5 ($4 / $20); GPT-6 Sol ($2 / $10) and Luna ($0.10 / $0.50) | Two labs cut flagship prices on the same day | Anthropic; OpenAI |
| Sep 21 | Grok 4.7 | 500K context at $2 / $6; xAI operating as SpaceXAI | xAI release notes |
| Sep 16 | Gartner raises 2026 AI spending forecast to $2.67T | +49.5% year over year | Gartner |
| Sep 10 | DeepSeek V4.1 Flash (1017 revision on Oct 17) | Open-weight at 195 tokens/s | DeepSeek |
| Sep 3 | GPT-6 Astra ($10 / $50) | Highest-priced frontier tier; ARC Prize publishes its results the same day | OpenAI; ARC Prize |
| Sep 2 | Gemini 3.8 Flash ($0.75 / $3.75) | 141 tokens/s mid-tier | Artificial Analysis |
| Sep 1 | Claude Fable 5.1 and Mythos 5.1 ($10 / $50; Mythos restricted to Project Glasswing) | Mythos-class model with public safeguards | Anthropic release notes |
| Aug 27 | Gemini Omni 1.1 Flash | 4K upscaling, 40-second scene extension; now #1 on the video arena | |
| Aug 14 | SpaceX closes the Cursor acquisition; Copilot adds Grok 4.6 | Model choice becomes the IDE’s main feature | AP |
| Aug 2 | EU AI Act becomes applicable; AI Office and national authorities begin enforcement | Transparency rules in force; high-risk obligations delayed to Dec 2, 2027 by the AI Omnibus | European Commission |
| Jul 24 | Midjourney V8.2 becomes the default | V7 framing is officially stale | Midjourney |
| Jul | GPT-5.6 Sol, Terra, and Luna; Grok 4.5; Claude Opus 5 ($5 / $25) | The pricing tiers GPT-6 and Opus 5.5 would halve two months later | Vendor announcements |
| Jun 9 | Claude Fable 5 and Mythos 5 | First Mythos-class public release; access paused Jun 12–Jul 1 for US export-control review | Anthropic |
| May 19 | Gartner forecasts $2.59T AI spending for 2026 | Revised up in September | Gartner |
| May 7 | GPT-Realtime-2, Realtime-Translate, Realtime-Whisper | Voice models with reasoning levels and 128K context | OpenAI |
| May 5 | GPT-5.5 Instant becomes the ChatGPT default | — | OpenAI |
| Apr 26 | Sora app and web discontinued | — | OpenAI |
| Apr 24 | DeepSeek V4 preview: 1.6T / 49B active, 1M context, MIT license | Open-weight frontier returns | DeepSeek |
| Apr 23 | GPT-5.5 ($5 / $30, 1M context) | — | OpenAI |
| Apr 7 | Claude Mythos Preview disclosed (Project Glasswing, restricted access) | Gated frontier access becomes a category | Anthropic |
| Mar 5 | GPT-5.4 Thinking and Pro | The model this guide led with in March | OpenAI |
| Mar 3 | Policy in Amazon Bedrock AgentCore generally available | Tool-gateway policy enforcement for agents | AWS |
| Feb | Claude Opus 4.6 and Sonnet 4.6; SpaceX acquires xAI | 1M context goes to beta on Opus | Anthropic |
Next scheduled change we know about: Gemini 4 Argon’s API list price moves to $4 / $20 on December 1, 2026.
AI Adoption and Spending in 2025–2026: Everyone Uses It, Almost Nobody Lets It Act
The adoption numbers and the autonomy numbers tell two different stories, and most articles only quote the first one.
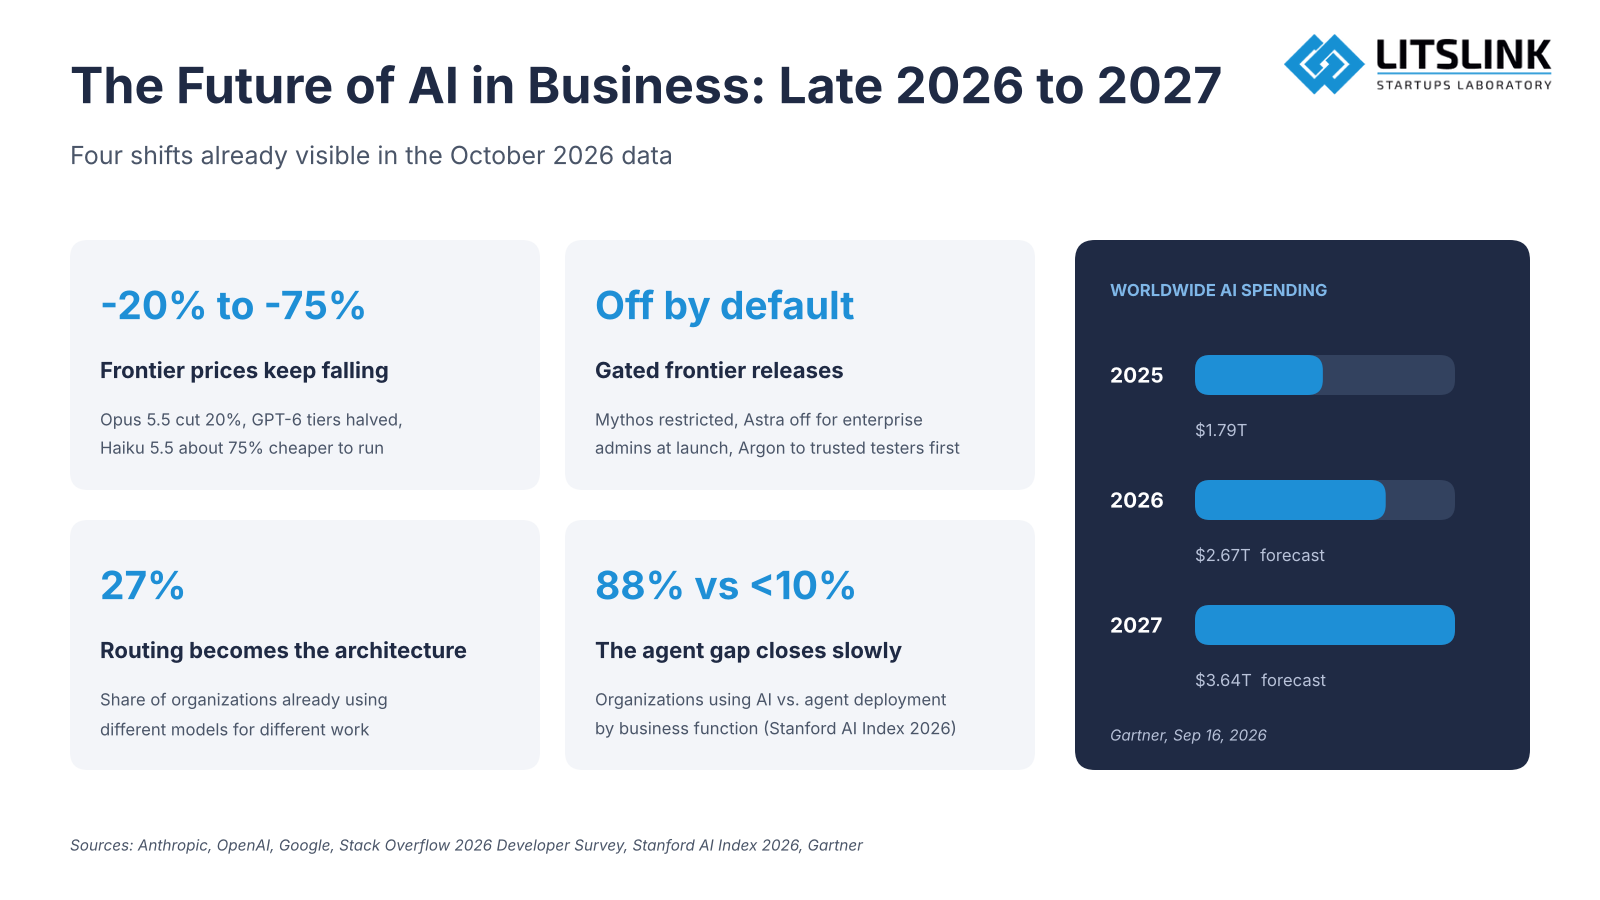
Gartner’s September 2026 forecast puts worldwide AI spending at $2.67 trillion in 2026, up 49.5% from $1.79 trillion in 2025, with $3.64 trillion penciled in for 2027. That’s roughly the GDP of France, spent in one year, on one category of technology. About $1.48 trillion of it is infrastructure; AI agents and assistants are a $29.2 billion line, up from $16.5 billion the year before. Which means the agent market is growing faster than almost anything else in the forecast and is still about 1% of the total. Gartner revised the total up by $80 billion between May and September, which shows how the year went.
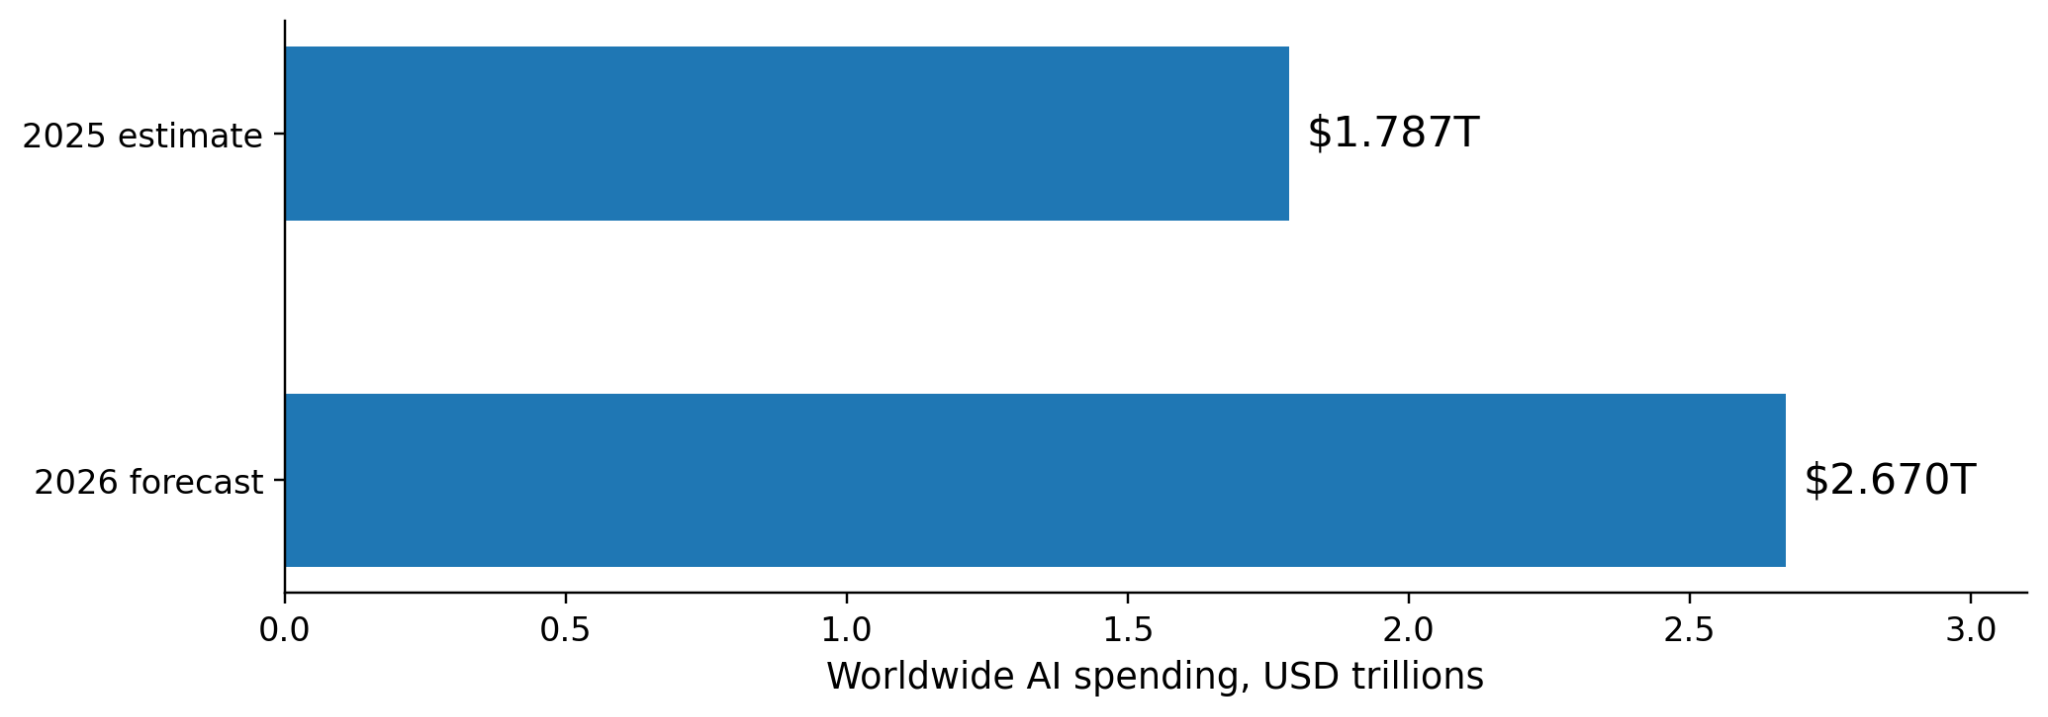
Figure 6. Gartner’s 2025 estimate and 2026 forecast, USD trillions. A forecast published in September 2026, not an observed total.
On the usage side, Stanford’s AI Index 2026 reports that 88% of surveyed organizations used AI in 2025, up from 55% in 2023, and 70% used generative AI in at least one business function. The same report says deployment of AI agents “was in the single digits across nearly all business functions.” So almost all companies use AI, and almost none of them let it take an action without a person in the loop. That gap is the entire market for the next two years.
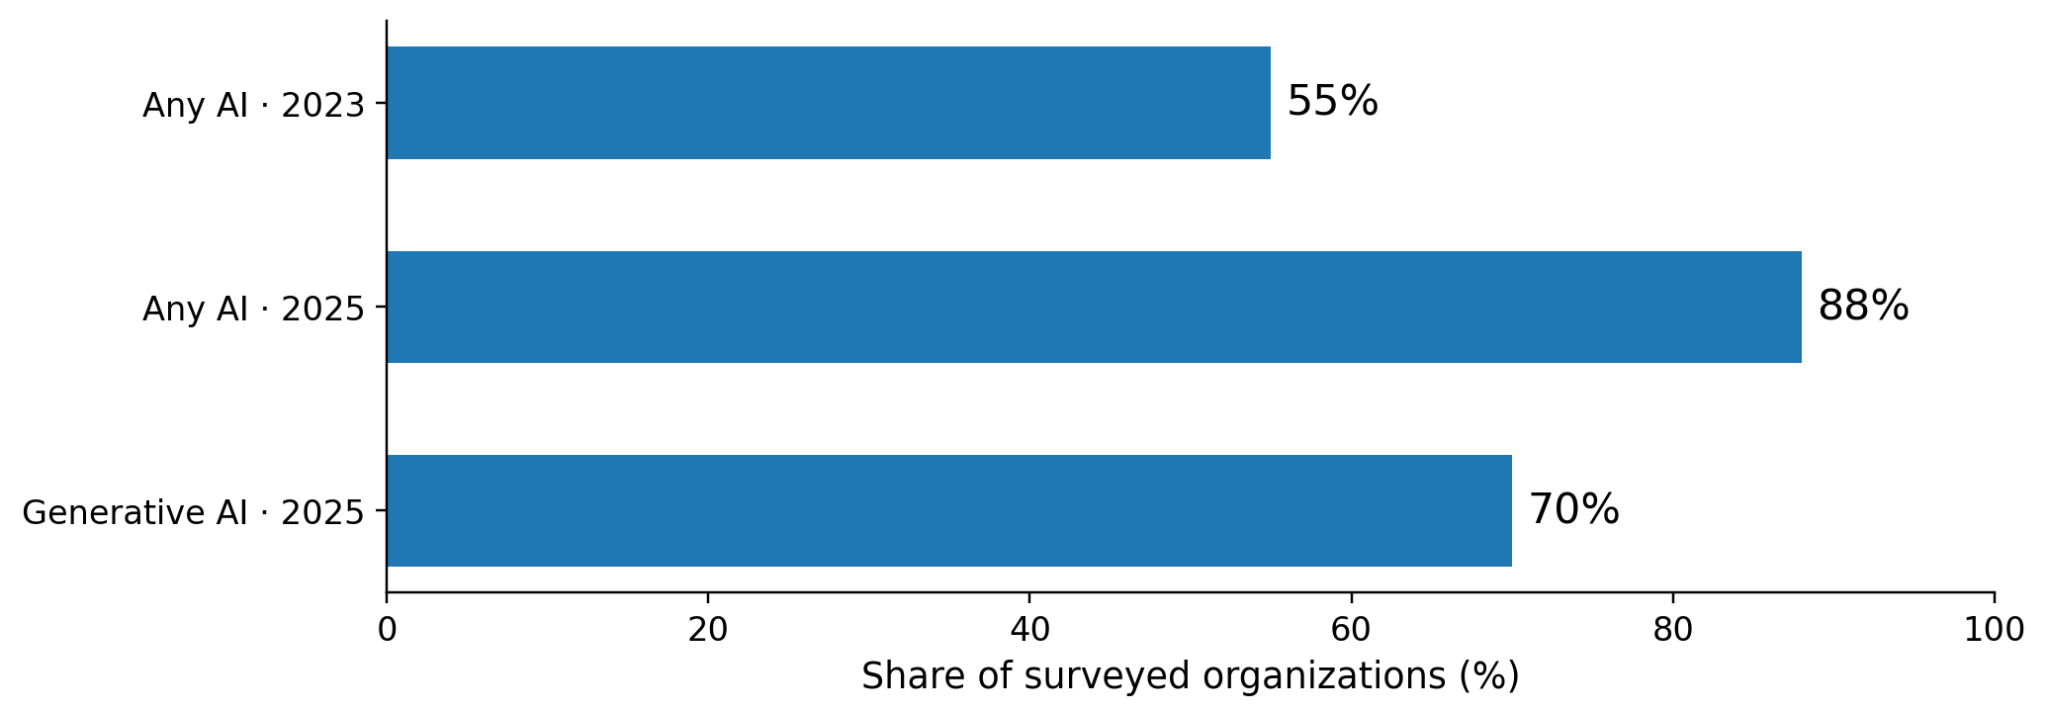
Figure 7. Share of surveyed organizations using any AI and generative AI, Stanford AI Index 2026 economy chapter. Different measures; not a census.
From the Stack Overflow 2026 survey of over 30,000 developers, we learn that 73% of those using AI coding tools do so on a daily basis, a third of the daily users spend 4+ hours per day with the tools and only 17.2% of developers use no AI tools whatsoever. The sentiment is positive for 62% of respondents and 71% of the daily users. OpenAI’s own enterprise telemetry is a little more pointed in that the gap in output tokens per active user between the heaviest-using companies and the average firm grew from 2.6x in January to 8.3x in June 2026. A few companies are clearly pulling away. The majority are still in the pilot.
Reliability is the counterweight. The AI Index counts 362 documented AI incidents in 2025, up from 233 in 2024. Reported counts depend on who’s looking, so that’s not a failure rate, but it’s not nothing either. METR’s time-horizon work measures the length of human task an agent can complete at a given success probability; an eight-hour benchmark horizon does not mean an eight-hour job is automated, and METR says so.
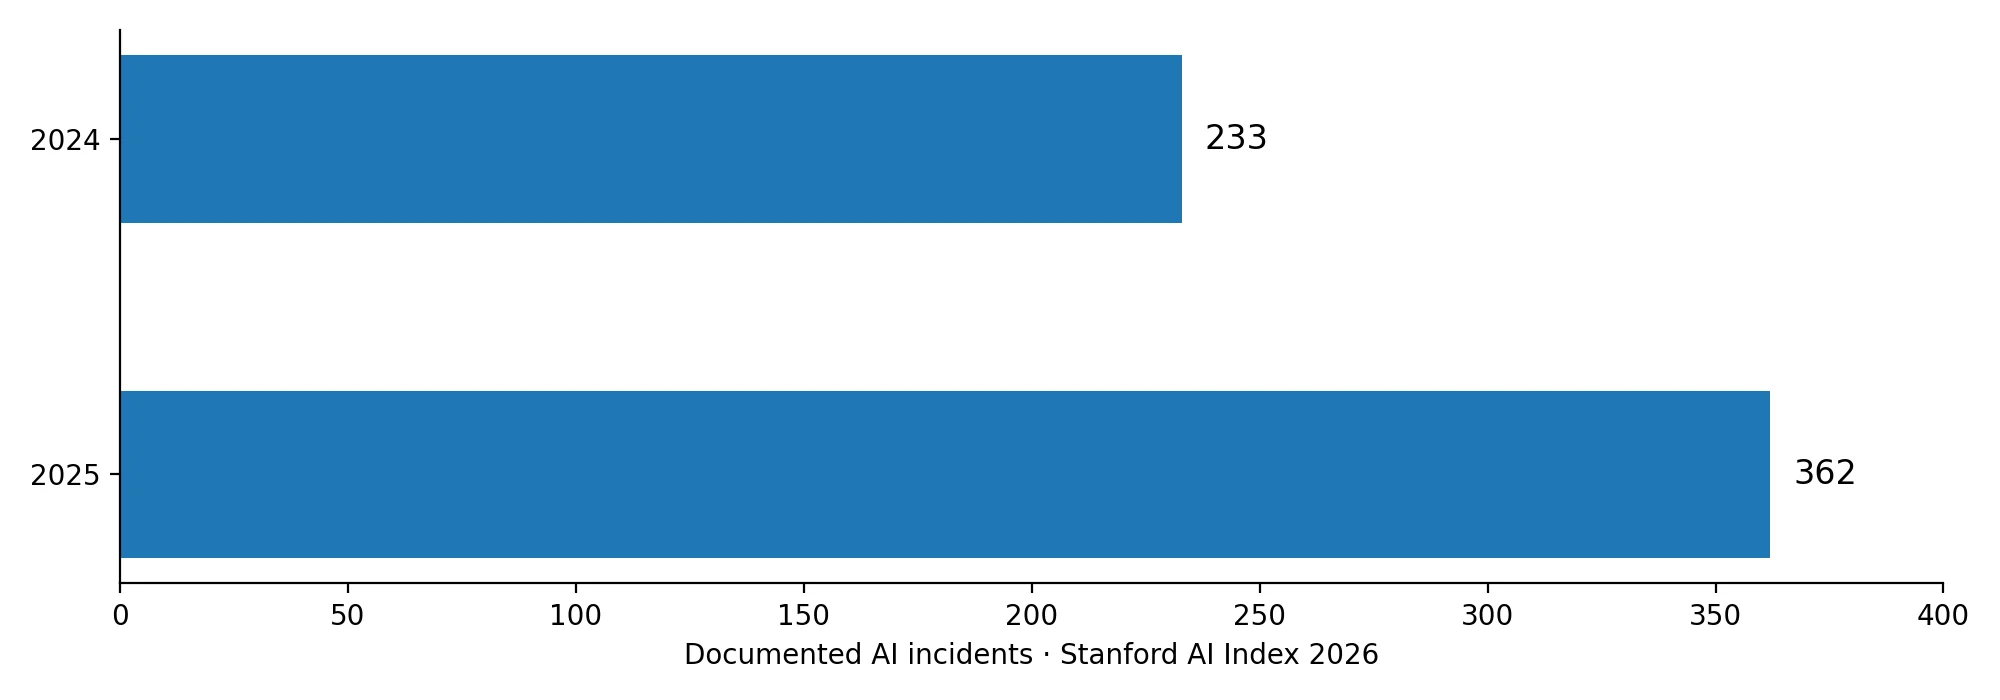
Figure 8. Documented AI incidents, Stanford AI Index 2026. Counts reflect exposure, detection, and reporting, not a per-deployment failure rate.
Who Depends on the Future of AI?
It’s so easy to think that the future belongs to the companies that are building the best AI models. In fact the future of AI is determined by everyone in the chain. It’s not just the people who are building it, the people who are funding it, the people who are deploying it; it’s the people who are actually using it and living with the outcomes.
1) Builders (startups and enterprises). Model releases are just the beginning. The real value is in the data pipelines, the guardrails, the evaluation, and the actual shipping. LITSLINK has seen this first-hand. Summalegal has an absolute requirement for accuracy, honesty, and the diligent handling of privileged content. Horoscope Generation is all about speed, customization, and cost. TestWiz is a great example of how AI can be of value when it’s part of a well-defined testing workflow rather than just a chatbot.
2) Data owners and domain experts. The “truth” is generally in the documents and processes themselves: legal teams, teachers, analysts, doctors. You can’t have a good model without good data and good rules. Without that, you’re just going to end up with an unreliable chatbot.
3) Infrastructure and tooling. Cloud platforms, GPUs, and deployment tooling determine what’s practical and affordable. Gartner’s $1.48 trillion infrastructure line is the evidence of that.
4) End users and regulators. Regulators enforce safety and openness (the EU AI Act has been enforceable since 2nd August 2026); users reward utility and trust.
What This Means for CTOs, Founders, and Product Owners
If you’re the one who has to sign off on the model for this quarter, then here’s the version of the article that would fit on an index card.
- Define the task before you even go to the model. “We need AI” is not a use case. “Summarise 2,300 legal documents a month with under 2% factual drift” is a use case, and that’s what tells you which model to test before you test any.
- Test on your own data with acceptance criteria defined upfront. Benchmarks are essentially eligibility criteria. Freeze the model version, the effort level, the prompt and the data snapshot. Run each task several times and keep the failures.
- Price per accepted task, not per token. Count the reviewer’s minutes, the retries, and the failed actions. A $0.10 model that needs a human to re-check 40% of its output is a $2 model.
- Set the autonomy boundary in code, not in the prompt. Policy at the tool gateway (AgentCore’s model), approval before anything persists (RIV’s model), a hardcoded line the model never crosses (Summalegal’s model). Pick one; use it.
- Record the model ID and the effort setting on every output. Three of the models in this guide changed name or price in the last 60 days. The version you tested is not the version you’ll be running in March unless you pin it.
Skip the first step and the other four don’t help. I’ve watched that happen in three different companies this year, and in all three the problem was the same: the model was fine.
What to Expect from the Industry in Late 2026 and 2027
In 2026, AI will be a major force driving global innovation. It is no longer only a trend. Businesses now prioritize artificial intelligence services to automate regular tasks, and the next five quarters have a clearer shape than the last five did.
Prices keep falling at the top. Opus 5.5 cut 20% from Opus 5. GPT-6 Sol and Luna halved the GPT-5.6 tiers. Haiku 5.5 is about 75% cheaper to run than Haiku 4.5. The pattern since 2024 has been a step down in price every six to nine months at constant capability, and nothing in the September announcements suggests it’s stopping. Budget for the model you’d want at a third of today’s price, because you’ll have it.
Gated frontier releases become normal. Claude Mythos stays restricted to Project Glasswing. GPT-6 Astra shipped with cyber-capability limits and is off by default for enterprise admins. Gemini 4 Argon went to trusted testers first. The most capable model in the world will increasingly be one you can’t buy, and the one you can buy will be a safeguarded version of it. Plan for the second.
Routing is the default architecture. The frontier-planner-plus-cheap-subagent pattern will be how most production systems look by mid-2027, and the tooling for it (Devin Fusion, Copilot’s model menu, Claude Code subagents) is already shipping.
The agent gap closes slowly. Stanford’s single-digit agent deployment and Gartner’s $29.2 billion agent line point the same way: wide adoption of assistants, narrow adoption of autonomy, and a lot of money chasing the difference. Big changes are coming in healthcare, entertainment, and other areas because of progress in large-context models, multimodal understanding, and computer vision technologies, but they’ll arrive as governed workflows, not as a model that “just does it.”
As artificial intelligence systems become more advanced, we’ll also see a greater emphasis on explainability and transparency. Businesses of all sizes will keep integrating the principles of responsible AI into their automation strategies, partly because the EU AI Act now requires disclosing chatbots and labeling synthetic media, and partly because the Scarlett Johansson and Kanye West deepfake was a preview, not an outlier. Google’s SynthID watermarking helps identify generated media; it doesn’t prove a claim is true or an asset is licensed.
Overall, advanced AI for business keeps accelerating. The biggest wins will go to teams who ship useful workflows, not demos.
Conclusion
In 2026, the “world’s most advanced AI” conversation exclusively becomes useful when you translate it into:
- Which field are we solving for?
- What tasks and metrics define success?
- What governance do we need before automation touches real systems?
The dated answer, for the record: in October 2026 the most advanced AI today is Claude Opus 5.5 by independent composite, Gemini 4 Argon by human preference, and GPT-6 Astra by maximum-effort math. Six months from now, at least one of those names will be wrong, and the three questions above will still be right.
If you’re building or integrating AI into a real product (customer support automation, internal copilots, agentic coding workflows, or generative media pipelines), LITSLINK can help you go from evaluation to production: architecture, data pipelines, model selection, guardrails, and monitoring.
Frequently Asked Questions (FAQ)
What is the most advanced AI model right now, in 2026?
As of October 25, 2026, Claude Opus 5.5 leads the independent Artificial Analysis Intelligence Index at 58. Gemini 4 Argon leads LMArena on human preference, and GPT-6 Astra holds the top vendor-reported math scores. Which one is “most advanced” for you depends on whether you’re measuring reasoning, conversation, or cost per task.
Which AI is the most advanced: ChatGPT, Claude, or Gemini?
They split the title three ways. Claude leads the composite index and agentic coding, Gemini leads blind human preference, and ChatGPT has the widest reach with GPT-6 Luna on its free tier. Among developers, the Stack Overflow 2026 survey puts Anthropic models at 75% usage and OpenAI’s at 74%.
What is the smartest AI in the world?
At maximum reasoning effort, Claude Opus 5.5 scores highest on Humanity’s Last Exam with tools (67.7%, per Anthropic) and GPT-6 Astra scores highest on FrontierMath Tier 4 (97.6%, per OpenAI). Both numbers come from the vendors, and both models take minutes to answer at that setting. The smartest AI is the one you let think longest.
What is the most powerful AI in the world?
Power is capability times autonomy. By composite capability, it’s Claude Opus 5.5; by what it can do on a computer unattended, Claude Sonnet 5.5 leads OSWorld 2.1 and GPT-6 Astra leads AutomationBench, and both still fail most multi-step business tasks. The “most powerful AI” for your company is the one wrapped in the best control layer.
What is the strongest AI for coding?
Claude Code with Sonnet 5.5 or Opus 5.5, by usage (66% of agent users in the Stack Overflow survey) and by the independent Terminal-Bench 4.0 result, where Opus 5.5 and GPT-6 Astra tied at 59.6%. GPT-6 Astra is the runner-up for the hardest individual problems, and GPT-6 Sol inside Codex for volume.
Is ChatGPT the most advanced AI?
Not by the independent composite, where GPT-6 Astra ties for fifth at 53. ChatGPT is the most accessible advanced AI: GPT-6 Luna, a 1M-context model, is on the Free and Go plans, and no competitor matches that at the free tier.
What is the most advanced AI chatbot?
For conversation quality, the Gemini app running Gemini 4 Argon, which leads the LMArena text leaderboard on blind votes. For long documents, Claude. For the broadest feature set at no cost, ChatGPT with GPT-6 Luna.
What is the most advanced form of AI?
In 2026, the most advanced AI technology is the reasoning model with adjustable effort and tool use: a system that plans, calls external tools, checks its own work, and runs for minutes on a hard problem. That’s the architecture behind every entry in this guide. Artificial general intelligence hasn’t been reached; ARC Prize said so explicitly even while publishing GPT-6 Astra’s 99.9% on ARC-AGI-3.
Who has the most advanced AI, the US or China?
The US, narrowly. Stanford’s AI Index 2026 measured the top US model’s lead over the top Chinese model at 2.7% on Arena as of March 2026, and in October Moonshot’s Kimi K3.1 Pro sits fourth on the Artificial Analysis index at 55. Chinese labs lead on open weights; US labs lead on the closed frontier.
What is the best AI model for the money?
Claude Sonnet 5.5: a score of 56, two points behind the leader, at $2 / $10 per 1M tokens. For budget work, Claude Haiku 5.5 and GPT-6 Luna at $0.10 / $0.50, or DeepSeek V4.1 Flash at $0.30 / $1.20 peak if you can self-host. Artificial Analysis puts GPT-6.1 Sol at $0.72 per index task against $5.98 for Opus 5.5.
What is the most advanced AI software for business automation?
The best AI for business is one that supports agentic workflows, where the AI can carry out tasks, and that connects with your existing systems, featuring strong guardrails: Copilot Studio for Microsoft environments, Bedrock AgentCore for AWS, UiPath Maestro for cross-system orchestration. Stanford reports agent deployment is still in the single digits across business functions, so start with one bounded process.
Which AI has the largest context window?
A 1M-token window is now standard across Claude Opus, Sonnet, and Haiku 5.5, the GPT-6 family (1.05M), Gemini 4 Argon (1,048,576 unified), Kimi K3.1, and DeepSeek V4.1. Llama 4 Scout still lists the largest window on the leaderboard and scores 6 on the index. Window size and comprehension are different things; test retrieval across your own long documents.
What is the most powerful free AI?
If “most powerful AI website” means the one you can open in a browser for free, it’s GPT-6 Luna on ChatGPT, the Gemini app’s free tier, or Claude’s free plan all run real 2026 models with usage limits. If “free” means open weights you can run yourself, DeepSeek V4.1 Flash (MIT license) and MiMo-V2.6-Pro are the strongest options on the independent index.